# Vapor Docs
> Vapor's documentation (web framework for Swift).

# Vapor Documentation
Welcome to the Vapor Documentation! Vapor is a web framework for Swift, allowing you to write backends, web apps APIs and HTTP servers in Swift. Vapor is written in Swift, which is a modern, powerful and safe language providing a number of benefits over the more traditional server languages.
## Getting Started
If this is your first time using Vapor, head to [Install → macOS](install/macos.md) to install Swift and Vapor.
Once you have Vapor installed, check out [Getting Started → Hello, world](getting-started/hello-world.md) to create your first Vapor app!
## Other Sources
Here are some other great places to find information about Vapor.
| name | description | link |
|----------------|--------------------------------------------------|-------------------------------------------------------------------|
| Vapor Discord | Chat with thousands of Vapor developers. | [visit →](https://vapor.team) |
| API docs | Auto-generated documentation from code comments. | [visit →](https://api.vapor.codes) |
| Stack Overflow | Ask and answer questions with the `vapor` tag. | [visit →](https://stackoverflow.com/questions/tagged/vapor) |
| Swift Forums | Post in Vapor's section of the Swift.org forums. | [visit →](https://forums.swift.org/c/related-projects/vapor) |
| Source Code | Learn how Vapor works under the hood. | [visit →](https://github.com/vapor/vapor) |
| GitHub Issues | Report bugs or request features on GitHub. | [visit →](https://github.com/vapor/vapor/issues) |
## Authors
The Vapor Core Team, and the hundreds of members of the Vapor community.
# Install on macOS
To use Vapor on macOS, you will need Swift 5.9 or greater. Swift and all of its dependencies come bundled with Xcode.
## Install Xcode
Install [Xcode](https://itunes.apple.com/us/app/xcode/id497799835?mt=12) from the Mac App Store.
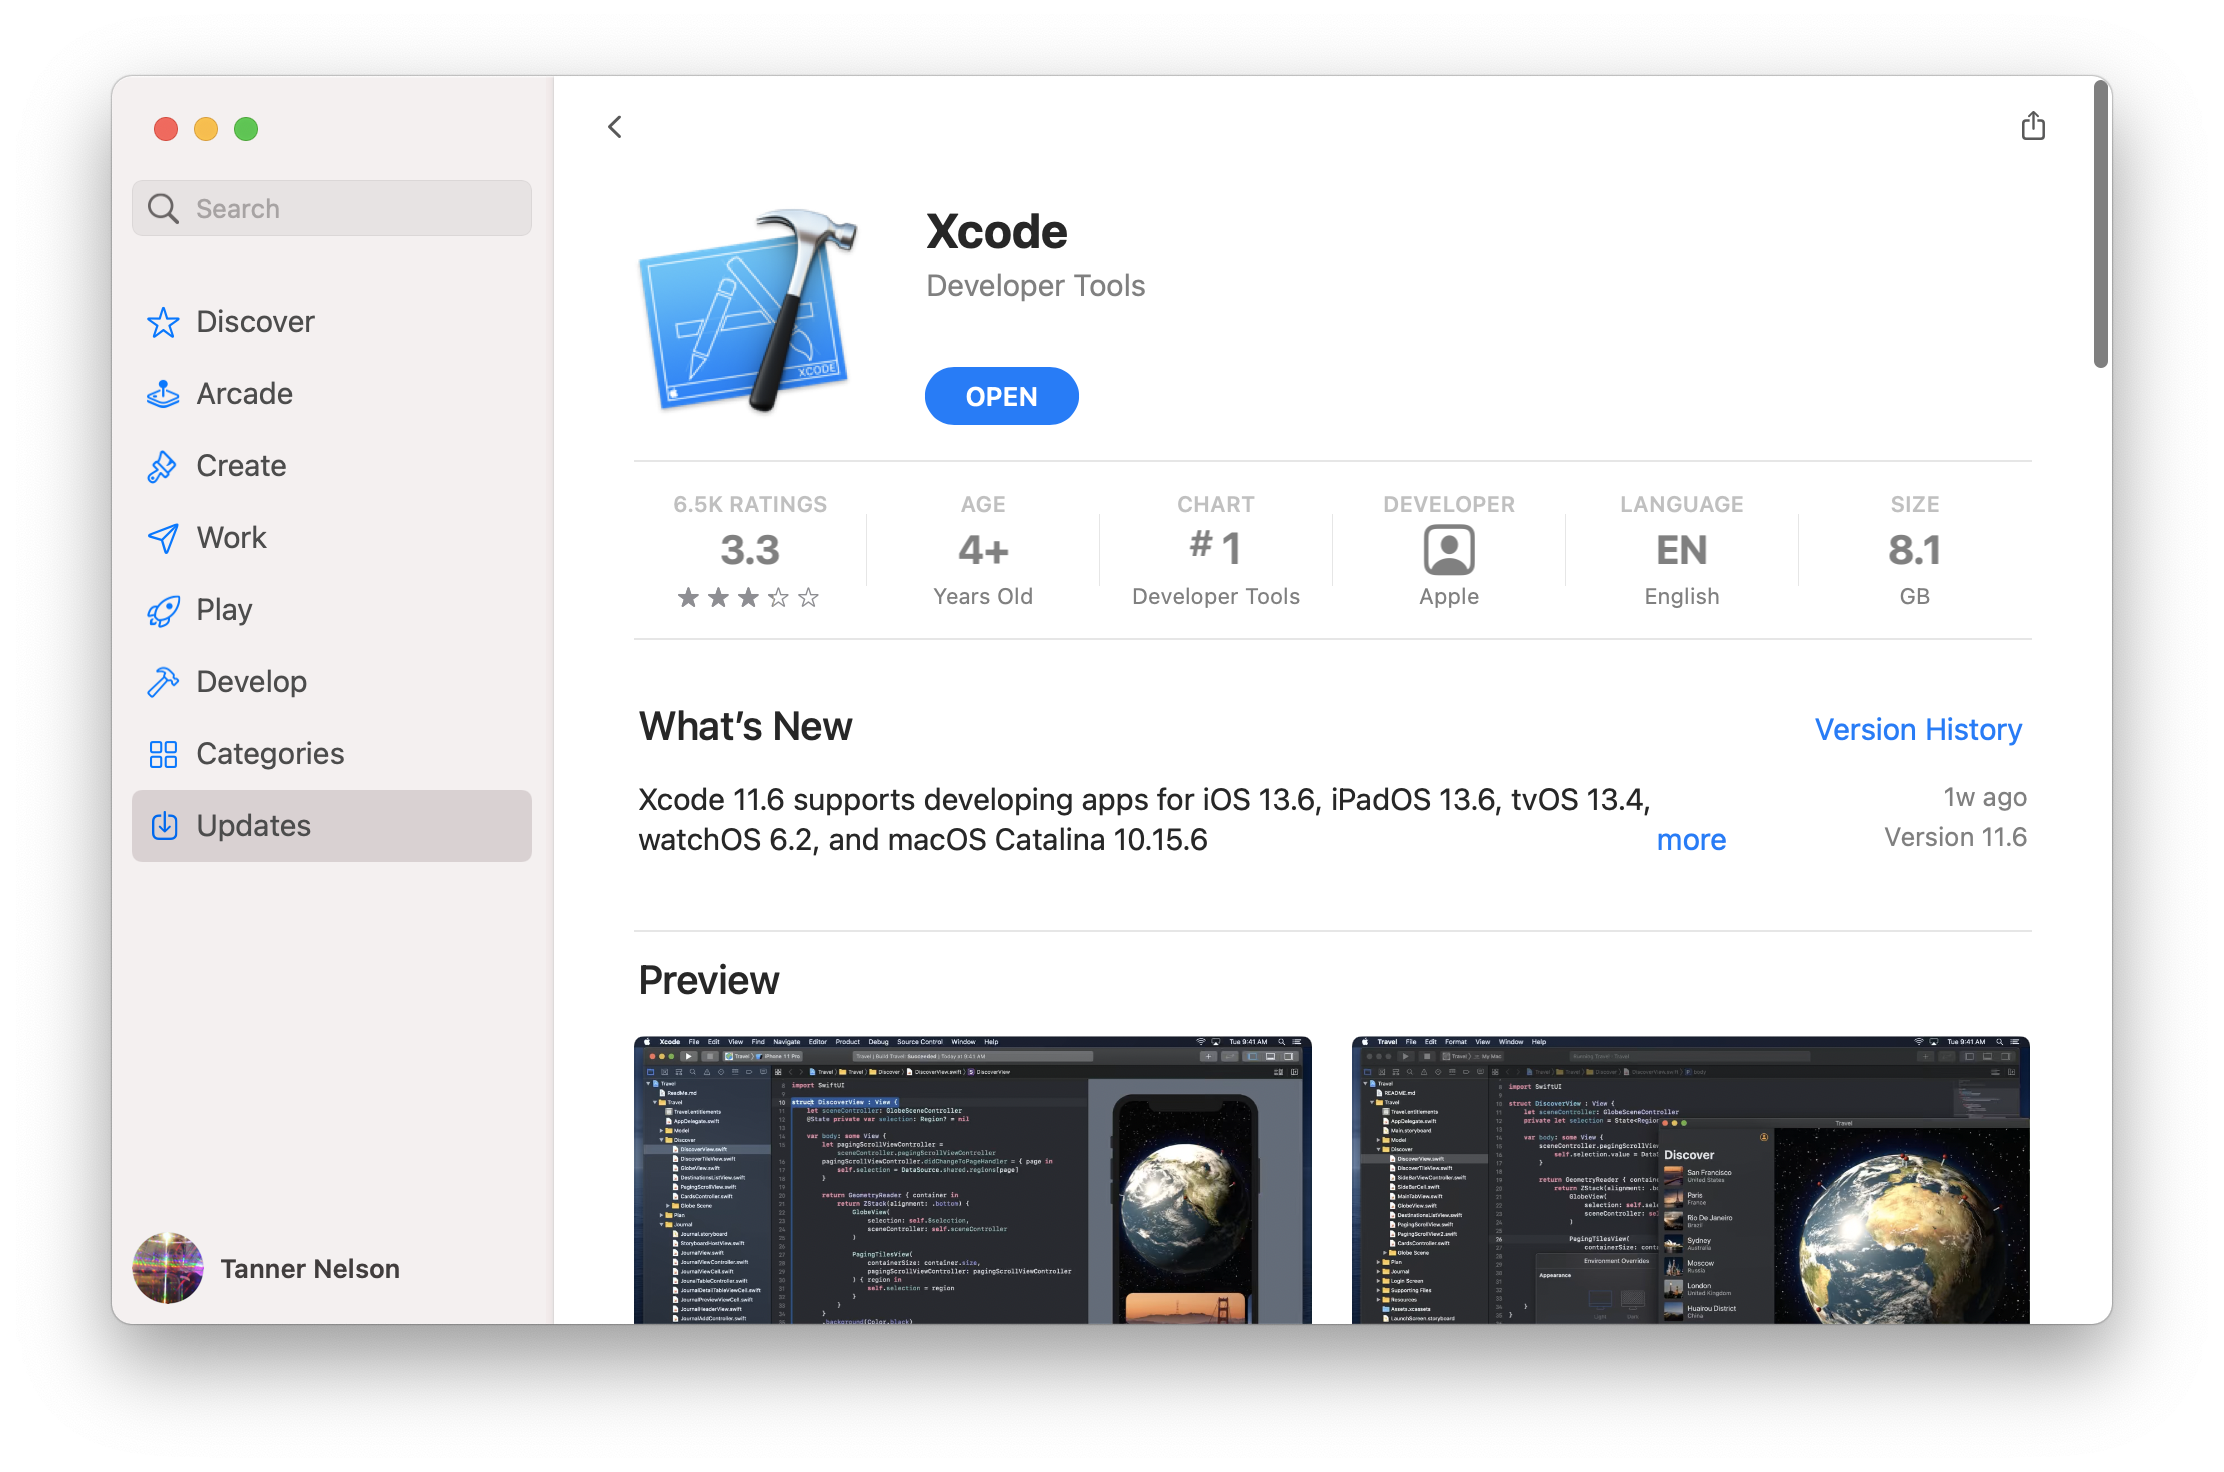
After Xcode has been downloaded, you must open it to complete the installation. This may take a while.
Double check to ensure that the installation was successful by opening the Terminal and printing the Swift's version.
```sh
swift --version
```
You should see Swift's version information printed.
```sh
swift-driver version: 1.75.2 Apple Swift version 5.8 (swiftlang-5.8.0.124.2 clang-1403.0.22.11.100)
Target: arm64-apple-macosx13.0
```
Vapor 4 requires Swift 5.9 or greater.
## Install Toolbox
Now that you have Swift installed, let's install the [Vapor Toolbox](https://github.com/vapor/toolbox). This CLI tool is not required to use Vapor, but it helps to create new Vapor projects.
### Homebrew
The Toolbox is distributed via Homebrew. If you do not have Homebrew yet, visit brew.sh for install instructions.
```sh
brew install vapor
```
Double check to ensure that the installation was successful by printing help.
```sh
vapor --help
```
You should see a list of available commands.
### Makefile
If you want, you can also build the Toolbox from source. View the Toolbox's releases on GitHub to find the latest version.
```sh
git clone https://github.com/vapor/toolbox.git
cd toolbox
git checkout
make install
```
Double check the installation was successful by printing help.
```sh
vapor --help
```
You should see a list of available commands.
## Next
Now that you have installed Swift and Vapor Toolbox, create your first app in [Getting Started → Hello, world](../getting-started/hello-world.md).
# Install on Linux
To use Vapor, you will need Swift 5.9 or greater. This can be installed using the CLI tool [Swiftly](https://swiftlang.github.io/swiftly/) provided by the Swift Server Workgroup (recommended), or the toolchains available on [Swift.org](https://swift.org/download/).
## Supported Distributions and Versions
Vapor supports the same versions of Linux distributions that Swift 5.9 or newer versions supports. Please refer to the [official support page](https://www.swift.org/platform-support/) in order to find updated information about which operating systems are officially supported.
Linux distributions not officially supported may also run Swift by compiling the source code, but Vapor cannot prove stability. Learn more about compiling Swift from the [Swift repo](https://github.com/apple/swift#getting-started).
## Install Swift
### Automated installation using Swiftly CLI tool (recommended)
Visit the [Swiflty website](https://swiftlang.github.io/swiftly/) for instructions on how to install Swiftly and Swift on Linux. After that, install Swift with the following command:
#### Basic usage
```sh
$ swiftly install latest
Fetching the latest stable Swift release...
Installing Swift 5.9.1
Downloaded 488.5 MiB of 488.5 MiB
Extracting toolchain...
Swift 5.9.1 installed successfully!
$ swift --version
Swift version 5.9.1 (swift-5.9.1-RELEASE)
Target: x86_64-unknown-linux-gnu
```
### Manual installation with the toolchain
Visit Swift.org's [Using Downloads](https://swift.org/download/#using-downloads) guide for instructions on how to install Swift on Linux.
### Fedora
Fedora users can simply use the following command to install Swift:
```sh
sudo dnf install swift-lang
```
If you're using Fedora 35, you'll need to add EPEL 8 to get Swift 5.9 or newer versions.
## Docker
You can also use Swift's official Docker images which come with the compiler preinstalled. Learn more at [Swift's Docker Hub](https://hub.docker.com/_/swift).
## Install Toolbox
Now that you have Swift installed, let's install the [Vapor Toolbox](https://github.com/vapor/toolbox). This CLI tool is not required to use Vapor, but it helps to create new Vapor projects.
### Homebrew
The Toolbox is distributed via Homebrew. If you do not have Homebrew yet, visit brew.sh for install instructions.
```sh
brew install vapor
```
Double check to ensure that the installation was successful by printing help.
```sh
vapor --help
```
You should see a list of available commands.
### Makefile
If you want, you can also build the Toolbox from source. View the Toolbox's releases on GitHub to find the latest version.
```sh
git clone https://github.com/vapor/toolbox.git
cd toolbox
git checkout
make install
```
Double check the installation was successful by printing help.
```sh
vapor --help
```
You should see a list of available commands.
## Next
Now that you have installed Swift and the Vapor Toolbox, create your first app in [Getting Started → Hello, world](../getting-started/hello-world.md).
# Hello, world
This guide will take you step by step through creating a new Vapor project, building it, and running the server.
If you have not yet installed Swift or Vapor Toolbox, check out the install section.
- [Install → macOS](../install/macos.md)
- [Install → Linux](../install/linux.md)
!!! tip
The template used by the Vapor Toolbox requires Swift 6.0 or later
## New Project
The first step is to create a new Vapor project on your computer. Open up your terminal and use Toolbox's new project command. This will create a new folder in the current directory containing the project.
```sh
vapor new hello -n
```
!!! tip
The `-n` flag gives you a bare bones template by automatically answering no to all questions.
!!! tip
You can also get the latest template from GitHub without Vapor Toolbox by cloning the [template respository](https://github.com/vapor/template-bare)
!!! tip
Vapor and the template now uses `async`/`await` by default.
If you cannot update to macOS 12 and/or need to continue to use `EventLoopFuture`s,
use flag `--branch macos10-15`.
Once the command finishes, change into the newly created folder:
```sh
cd hello
```
## Build & Run
### Xcode
First, open the project in Xcode:
```sh
open Package.swift
```
It will automatically begin downloading Swift Package Manager dependencies. This can take some time the first time you open a project. When dependency resolution is complete Xcode will populate the available schemes.
At the top of the window, to the right of the Play and Stop buttons, click on your project name to select the project's Scheme, and select an appropriate run target—most likely, "My Mac". Click the play button to build and run your project.
You should see the Console pop up at the bottom of the Xcode window.
```sh
[ INFO ] Server starting on http://127.0.0.1:8080
```
### Linux
On Linux and other OSes (and even on macOS if you don't want to use Xcode) you can edit the project in your favorite editor of choice, such as Vim or VSCode. See the [Swift Server Guides](https://github.com/swift-server/guides/blob/main/docs/setup-and-ide-alternatives.md) for up to date details on setting up other IDEs.
!!! tip
If you're using VSCode as your code editor, we recommend installing the official Vapor extension: [Vapor for VS Code](https://marketplace.visualstudio.com/items?itemName=Vapor.vapor-vscode).
To build and run your project, in Terminal run:
```sh
swift run
```
That will build and run the project. The first time you run this it will take some time to fetch and resolve the dependencies. Once running you should see the following in your console:
```sh
[ INFO ] Server starting on http://127.0.0.1:8080
```
## Visit Localhost
Open your web browser, and visit localhost:8080/hello or http://127.0.0.1:8080
You should see the following page.
```html
Hello, world!
```
Congratulations on creating, building, and running your first Vapor app! 🎉
# Folder Structure
Now that you've created, built, and run your first Vapor app, let's take a moment to familiarize you with Vapor's folder structure. The structure is based on [SPM](spm.md)'s folder structure, so if you've worked with SPM before it should be familiar.
```
.
├── Public
├── Sources
│ ├── App
│ │ ├── Controllers
│ │ ├── Migrations
│ │ ├── Models
│ │ ├── configure.swift
│ │ ├── entrypoint.swift
│ │ └── routes.swift
│
├── Tests
│ └── AppTests
└── Package.swift
```
The sections below explain each part of the folder structure in more detail.
## Public
This folder contains any public files that will be served by your app if `FileMiddleware` is enabled. This is usually images, style sheets, and browser scripts. For example, a request to `localhost:8080/favicon.ico` will check to see if `Public/favicon.ico` exists and return it.
You will need to enable `FileMiddleware` in your `configure.swift` file before Vapor can serve public files.
```swift
// Serves files from `Public/` directory
let fileMiddleware = FileMiddleware(
publicDirectory: app.directory.publicDirectory
)
app.middleware.use(fileMiddleware)
```
## Sources
This folder contains all of the Swift source files for your project.
The top level folder, `App`, reflect your package's module,
as declared in the [SwiftPM](spm.md) manifest.
### App
This is where all of your application logic goes.
#### Controllers
Controllers are a great way of grouping together application logic. Most controllers have many functions that accept a request and return some sort of response.
#### Migrations
The migrations folder is where your database migrations go if you are using Fluent.
#### Models
The models folder is a great place to store your `Content` structs or Fluent `Model`s.
#### configure.swift
This file contains the `configure(_:)` function. This method is called by `entrypoint.swift` to configure the newly created `Application`. This is where you should register services like routes, databases, providers, and more.
#### entrypoint.swift
This file contains the `@main` entry point for the application that sets up, configures and runs your Vapor application.
#### routes.swift
This file contains the `routes(_:)` function. This method is called near the end of `configure(_:)` to register routes to your `Application`.
## Tests
Each non-executable module in your `Sources` folder can have a corresponding folder in `Tests`. This contains code built on the `XCTest` module for testing your package. Tests can be run using `swift test` on the command line or pressing ⌘+U in Xcode.
### AppTests
This folder contains the unit tests for code in your `App` module.
## Package.swift
Finally is [SPM](spm.md)'s package manifest.
# Swift Package Manager
The [Swift Package Manager](https://swift.org/package-manager/) (SPM) is used for building your project's source code and dependencies. Since Vapor relies heavily on SPM, it's a good idea to understand the basics of how it works.
SPM is similar to Cocoapods, Ruby gems, and NPM. You can use SPM from the command line with commands like `swift build` and `swift test` or with compatible IDEs. However, unlike some other package managers, there is no central package index for SPM packages. SPM instead leverages URLs to Git repositories and versions dependencies using [Git tags](https://git-scm.com/book/en/v2/Git-Basics-Tagging).
## Package Manifest
The first place SPM looks in your project is the package manifest. This should always be located in the root directory of your project and named `Package.swift`.
Take a look at this example Package manifest.
```swift
// swift-tools-version:5.8
import PackageDescription
let package = Package(
name: "MyApp",
platforms: [
.macOS(.v12)
],
dependencies: [
.package(url: "https://github.com/vapor/vapor.git", from: "4.76.0"),
],
targets: [
.executableTarget(
name: "App",
dependencies: [
.product(name: "Vapor", package: "vapor")
]
),
.testTarget(name: "AppTests", dependencies: [
.target(name: "App"),
.product(name: "XCTVapor", package: "vapor"),
])
]
)
```
Each part of the manifest is explained in the following sections.
### Tools Version
The very first line of a package manifest indicates the Swift tools version required. This specifies the minimum version of Swift that the package supports. The Package description API may also change between Swift versions, so this line ensures Swift will know how to parse your manifest.
### Package Name
The first argument to `Package` is the package's name. If the package is public, you should use the last segment of the Git repo's URL as the name.
### Platforms
The `platforms` array specifies which platforms this package supports. By specifying `.macOS(.v12)` this package requires macOS 12 or later. When Xcode loads this project, it will automatically set the minimum deployment version to macOS 12 so that you can use all available APIs.
### Dependencies
Dependencies are other SPM packages that your package relies on. All Vapor applications rely on the Vapor package, but you can add as many other dependencies as you want.
In the above example, you can see [vapor/vapor](https://github.com/vapor/vapor) version 4.76.0 or later is a dependency of this package. When you add a dependency to your package, you must next signal which [targets](#targets) depend on
the newly available modules.
### Targets
Targets are all of the modules, executables, and tests that your package contains. Most Vapor apps will have two targets, although you can add as many as you like to organize your code. Each target declares which modules it depends on. You must add module names here in order to import them in your code. A target can depend on other targets in your project or any modules exposed by packages you've added to
the [main dependencies](#dependencies) array.
## Folder Structure
Below is the typical folder structure for an SPM package.
```
.
├── Sources
│ └── App
│ └── (Source code)
├── Tests
│ └── AppTests
└── Package.swift
```
Each `.target` or `.executableTarget` corresponds to a folder in the `Sources` folder.
Each `.testTarget` corresponds to a folder in the `Tests` folder.
## Package.resolved
The first time you build your project, SPM will create a `Package.resolved` file that stores the version of each dependency. The next time you build your project, these same versions will be used even if newer versions are available.
To update your dependencies, run `swift package update`.
## Xcode
If you are using Xcode 11 or greater, changes to dependencies, targets, products, etc will happen automatically whenever the `Package.swift` file is modified.
If you want to update to the latest dependencies, use File → Swift Packages → Update To Latest Swift Package Versions.
You may also want to add the `.swiftpm` file to your `.gitignore`. This is where Xcode will store your Xcode project configuration.
# Xcode
This page goes over some tips and tricks for using Xcode. If you use a different development environment, you can skip this.
## Custom Working Directory
By default Xcode will run your project from the _DerivedData_ folder. This folder is not the same as your project's root folder (where your _Package.swift_ file is). This means that Vapor will not be able to find files and folders like _.env_ or _Public_.
You can tell this is happening if you see the following warning when running your app.
```fish
[ WARNING ] No custom working directory set for this scheme, using /path/to/DerivedData/project-abcdef/Build/
```
To fix this, set a custom working directory in the Xcode scheme for your project.
First, edit your project's scheme by clicking on the scheme selector by the play and stop buttons.

Select _Edit Scheme..._ from the dropdown.

In the scheme editor, choose the _App_ action and the _Options_ tab. Check _Use custom working directory_ and enter the path to your project's root folder.
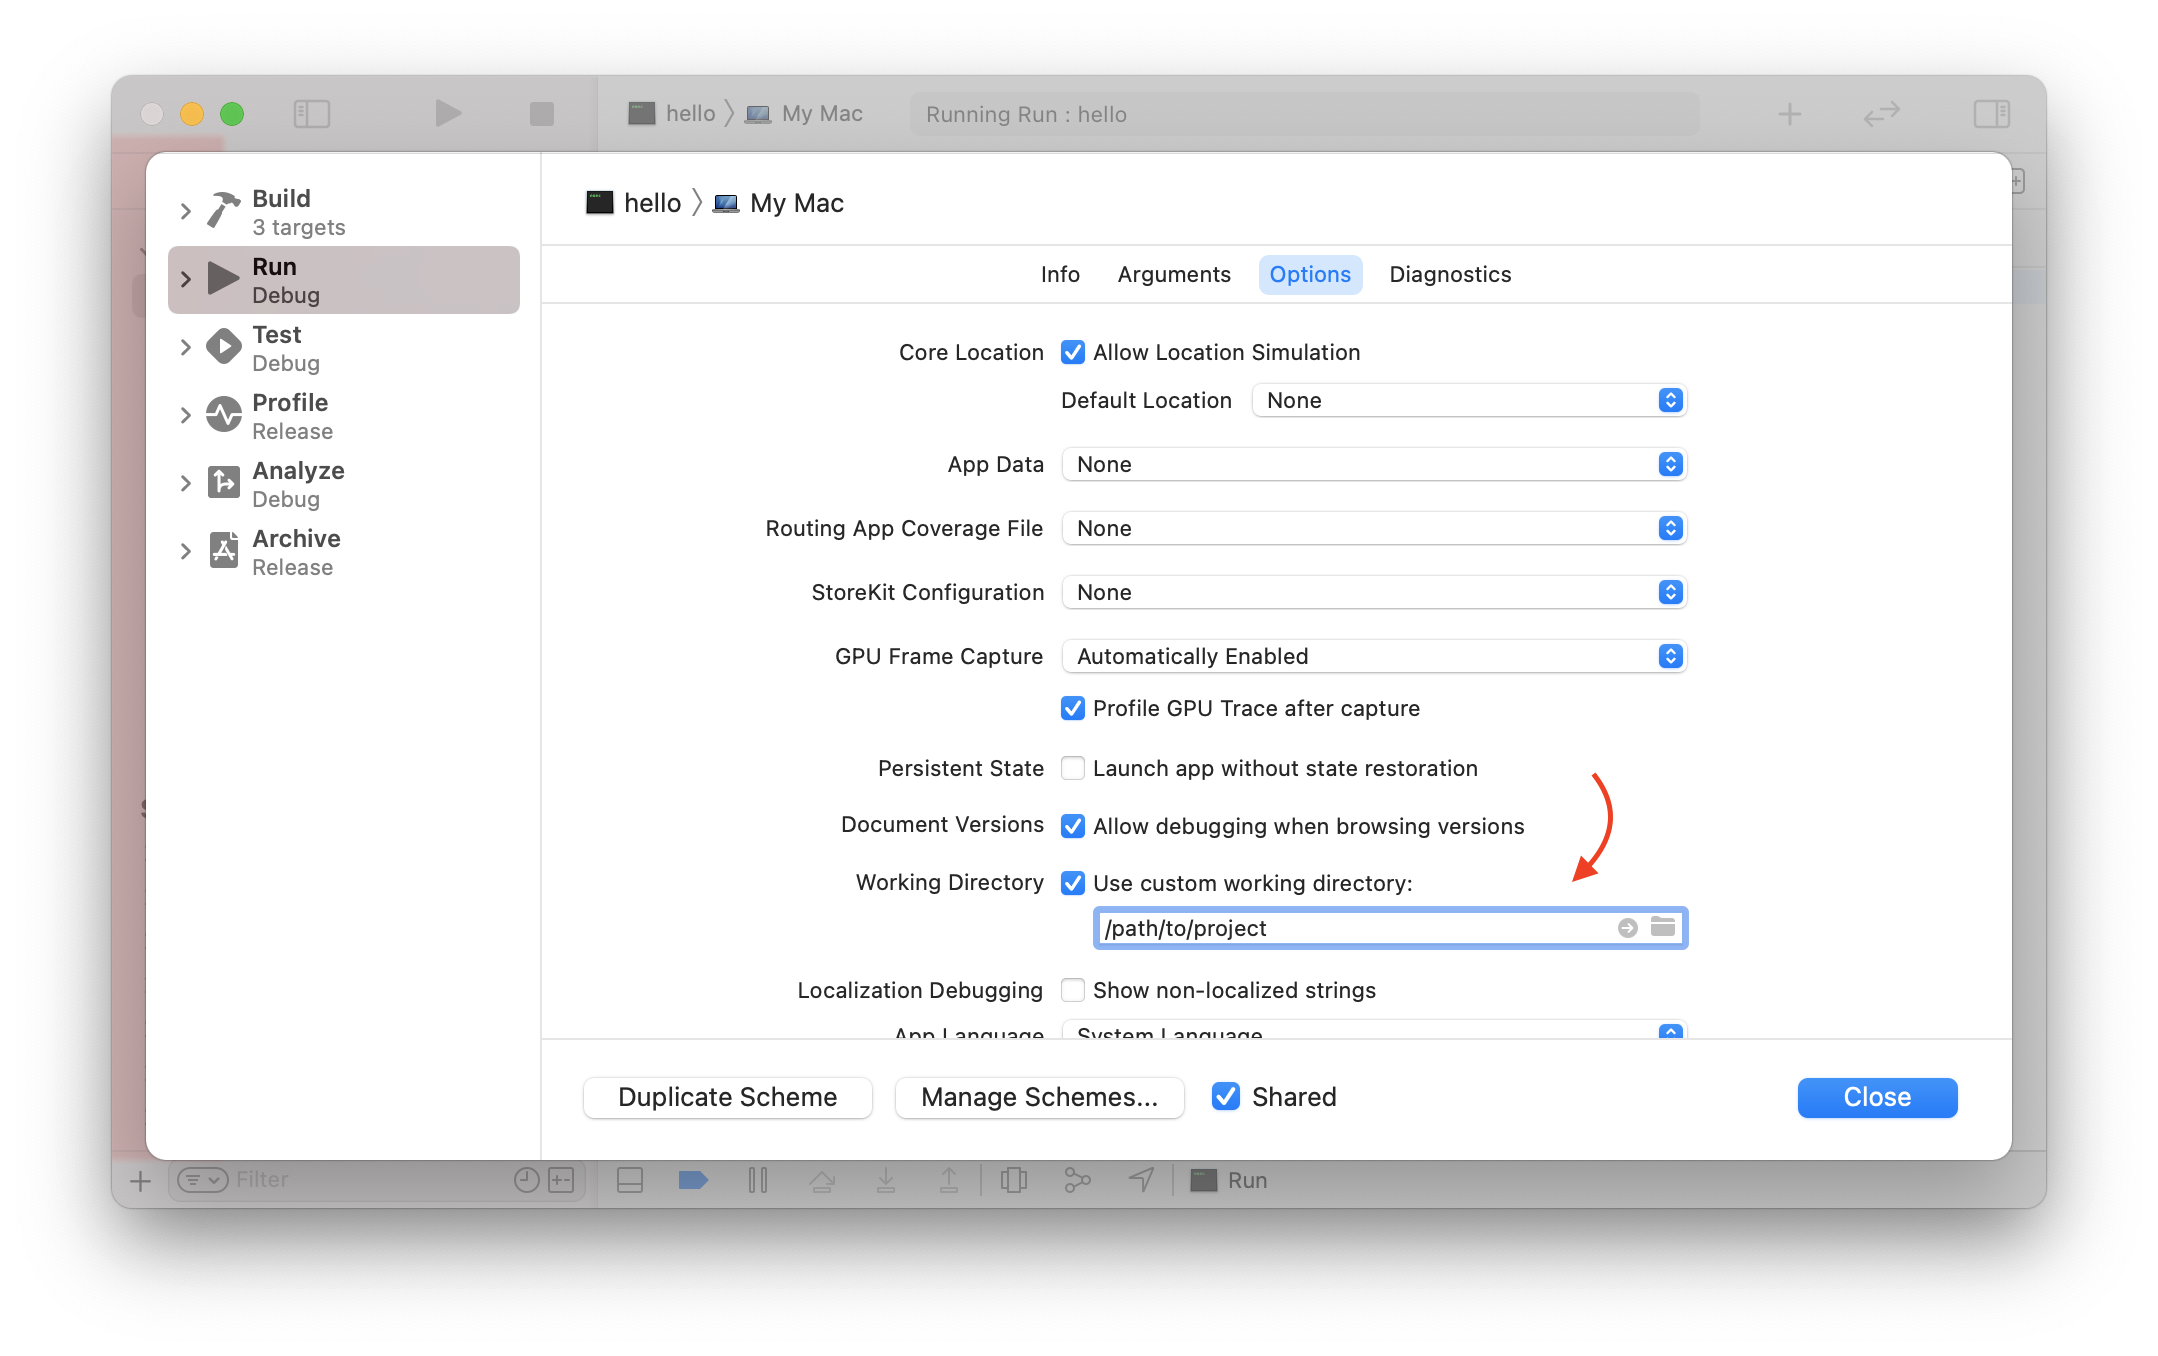
You can get the full path to your project's root by running `pwd` from a terminal window open there.
```sh
# get path to this folder
pwd
```
You should see output similar to the following.
```
/path/to/project
```
# Routing
Routing is the process of finding the appropriate request handler for an incoming request. At the core of Vapor's routing is a high-performance, trie-node router from [RoutingKit](https://github.com/vapor/routing-kit).
## Overview
To understand how routing works in Vapor, you should first understand a few basics about HTTP requests. Take a look at the following example request.
```http
GET /hello/vapor HTTP/1.1
host: vapor.codes
content-length: 0
```
This is a simple `GET` HTTP request to the URL `/hello/vapor`. This is the kind of HTTP request your browser would make if you pointed it to the following URL.
```
http://vapor.codes/hello/vapor
```
### HTTP Method
The first part of the request is the HTTP method. `GET` is the most common HTTP method, but there are several you will use often. These HTTP methods are often associated with [CRUD](https://en.wikipedia.org/wiki/Create,_read,_update_and_delete) semantics.
|Method|CRUD|
|-|-|
|`GET`|Read|
|`POST`|Create|
|`PUT`|Replace|
|`PATCH`|Update|
|`DELETE`|Delete|
### Request Path
Right after the HTTP method is the request's URI. This consists of a path starting with `/` and an optional query string after `?`. The HTTP method and path are what Vapor uses to route requests.
After the URI is the HTTP version followed by zero or more headers and finally a body. Since this is a `GET` request, it does not have a body.
### Router Methods
Let's take a look at how this request could be handled in Vapor.
```swift
app.get("hello", "vapor") { req in
return "Hello, vapor!"
}
```
All of the common HTTP methods are available as methods on `Application`. They accept one or more string arguments that represent the request's path separated by `/`.
Note that you could also write this using `on` followed by the method.
```swift
app.on(.GET, "hello", "vapor") { ... }
```
With this route registered, the example HTTP request from above will result in the following HTTP response.
```http
HTTP/1.1 200 OK
content-length: 13
content-type: text/plain; charset=utf-8
Hello, vapor!
```
### Route Parameters
Now that we've successfully routed a request based on the HTTP method and path, let's try making the path dynamic. Notice that the name "vapor" is hardcoded in both the path and the response. Let's make this dynamic so that you can visit `/hello/` and get a response.
```swift
app.get("hello", ":name") { req -> String in
let name = req.parameters.get("name")!
return "Hello, \(name)!"
}
```
By using a path component prefixed with `:`, we indicate to the router that this is a dynamic component. Any string supplied here will now match this route. We can then use `req.parameters` to access the value of the string.
If you run the example request again, you'll still get a response that says hello to vapor. However, you can now include any name after `/hello/` and see it included in the response. Let's try `/hello/swift`.
```http
GET /hello/swift HTTP/1.1
content-length: 0
```
```http
HTTP/1.1 200 OK
content-length: 13
content-type: text/plain; charset=utf-8
Hello, swift!
```
Now that you understand the basics, check out each section to learn more about parameters, groups, and more.
## Routes
A route specifies a request handler for a given HTTP method and URI path. It can also store additional metadata.
### Methods
Routes can be registered directly to your `Application` using various HTTP method helpers.
```swift
// responds to GET /foo/bar/baz
app.get("foo", "bar", "baz") { req in
...
}
```
Route handlers support returning anything that is `ResponseEncodable`. This includes `Content`, an `async` closure, and any `EventLoopFuture`s where the future value is `ResponseEncodable`.
You can specify the return type of a route using `-> T` before `in`. This can be useful in situations where the compiler cannot determine the return type.
```swift
app.get("foo") { req -> String in
return "bar"
}
```
These are the supported route helper methods:
- `get`
- `post`
- `patch`
- `put`
- `delete`
In addition to the HTTP method helpers, there is an `on` function that accepts HTTP method as an input parameter.
```swift
// responds to OPTIONS /foo/bar/baz
app.on(.OPTIONS, "foo", "bar", "baz") { req in
...
}
```
### Path Component
Each route registration method accepts a variadic list of `PathComponent`. This type is expressible by string literal and has four cases:
- Constant (`foo`)
- Parameter (`:foo`)
- Anything (`*`)
- Catchall (`**`)
#### Constant
This is a static route component. Only requests with an exactly matching string at this position will be permitted.
```swift
// responds to GET /foo/bar/baz
app.get("foo", "bar", "baz") { req in
...
}
```
#### Parameter
This is a dynamic route component. Any string at this position will be allowed. A parameter path component is specified with a `:` prefix. The string following the `:` will be used as the parameter's name. You can use the name to later fetch the parameters value from the request.
```swift
// responds to GET /foo/bar/baz
// responds to GET /foo/qux/baz
// ...
app.get("foo", ":bar", "baz") { req in
...
}
```
#### Anything
This is very similar to parameter except the value is discarded. This path component is specified as just `*`.
```swift
// responds to GET /foo/bar/baz
// responds to GET /foo/qux/baz
// ...
app.get("foo", "*", "baz") { req in
...
}
```
#### Catchall
This is a dynamic route component that matches one or more components. It is specified using just `**`. Any string at this position or later positions will be matched in the request.
```swift
// responds to GET /foo/bar
// responds to GET /foo/bar/baz
// ...
app.get("foo", "**") { req in
...
}
```
### Parameters
When using a parameter path component (prefixed with `:`), the value of the URI at that position will be stored in `req.parameters`. You can use the name of the path component to access the value.
```swift
// responds to GET /hello/foo
// responds to GET /hello/bar
// ...
app.get("hello", ":name") { req -> String in
let name = req.parameters.get("name")!
return "Hello, \(name)!"
}
```
!!! tip
We can be sure that `req.parameters.get` will never return `nil` here since our route path includes `:name`. However, if you are accessing route parameters in middleware or in code triggered by multiple routes, you will want to handle the possibility of `nil`.
!!! tip
If you want to retrieve URL query params, e.g. `/hello/?name=foo` you need to use Vapor's Content APIs to handle URL encoded data in the URL's query string. See [`Content` reference](content.md) for more details.
`req.parameters.get` also supports casting the parameter to `LosslessStringConvertible` types automatically.
```swift
// responds to GET /number/42
// responds to GET /number/1337
// ...
app.get("number", ":x") { req -> String in
guard let int = req.parameters.get("x", as: Int.self) else {
throw Abort(.badRequest)
}
return "\(int) is a great number"
}
```
The values of the URI matched by Catchall (`**`) will be stored in `req.parameters` as `[String]`. You can use `req.parameters.getCatchall` to access those components.
```swift
// responds to GET /hello/foo
// responds to GET /hello/foo/bar
// ...
app.get("hello", "**") { req -> String in
let name = req.parameters.getCatchall().joined(separator: " ")
return "Hello, \(name)!"
}
```
### Body Streaming
When registering a route using the `on` method, you can specify how the request body should be handled. By default, request bodies are collected into memory before calling your handler. This is useful since it allows for request content decoding to be synchronous even though your application reads incoming requests asynchronously.
By default, Vapor will limit streaming body collection to 16KB in size. You can configure this using `app.routes`.
```swift
// Increases the streaming body collection limit to 500kb
app.routes.defaultMaxBodySize = "500kb"
```
If a streaming body being collected exceeds the configured limit, a `413 Payload Too Large` error will be thrown.
To configure request body collection strategy for an individual route, use the `body` parameter.
```swift
// Collects streaming bodies (up to 1mb in size) before calling this route.
app.on(.POST, "listings", body: .collect(maxSize: "1mb")) { req in
// Handle request.
}
```
If a `maxSize` is passed to `collect`, it will override the application's default for that route. To use the application's default, omit the `maxSize` argument.
For large requests, like file uploads, collecting the request body in a buffer can potentially strain your system memory. To prevent the request body from being collected, use the `stream` strategy.
```swift
// Request body will not be collected into a buffer.
app.on(.POST, "upload", body: .stream) { req in
...
}
```
When the request body is streamed, `req.body.data` will be `nil`. You must use `req.body.drain` to handle each chunk as it is sent to your route.
### Case Insensitive Routing
Default behavior for routing is both case-sensitive and case-preserving. `Constant` path components can alternately be handled in a case-insensitive and case-preserving manner for the purposes of routing; to enable this behavior, configure prior to application startup:
```swift
app.routes.caseInsensitive = true
```
No changes are made to the originating request; route handlers will receive the request path components without modification.
### Viewing Routes
You can access your application's routes by making the `Routes` service or using `app.routes`.
```swift
print(app.routes.all) // [Route]
```
Vapor also ships with a `routes` command that prints all available routes in an ASCII formatted table.
```sh
$ swift run App routes
+--------+----------------+
| GET | / |
+--------+----------------+
| GET | /hello |
+--------+----------------+
| GET | /todos |
+--------+----------------+
| POST | /todos |
+--------+----------------+
| DELETE | /todos/:todoID |
+--------+----------------+
```
### Metadata
All route registration methods return the created `Route`. This allows you to add metadata to the route's `userInfo` dictionary. There are some default methods available, like adding a description.
```swift
app.get("hello", ":name") { req in
...
}.description("says hello")
```
## Route Groups
Route grouping allows you to create a set of routes with a path prefix or specific middleware. Grouping supports a builder and closure based syntax.
All grouping methods return a `RouteBuilder` meaning you can infinitely mix, match, and nest your groups with other route building methods.
### Path Prefix
Path prefixing route groups allow you to prepend one or more path components to a group of routes.
```swift
let users = app.grouped("users")
// GET /users
users.get { req in
...
}
// POST /users
users.post { req in
...
}
// GET /users/:id
users.get(":id") { req in
let id = req.parameters.get("id")!
...
}
```
Any path component you can pass into methods like `get` or `post` can be passed into `grouped`. There is an alternative, closure-based syntax as well.
```swift
app.group("users") { users in
// GET /users
users.get { req in
...
}
// POST /users
users.post { req in
...
}
// GET /users/:id
users.get(":id") { req in
let id = req.parameters.get("id")!
...
}
}
```
Nesting path prefixing route groups allows you to concisely define CRUD APIs.
```swift
app.group("users") { users in
// GET /users
users.get { ... }
// POST /users
users.post { ... }
users.group(":id") { user in
// GET /users/:id
user.get { ... }
// PATCH /users/:id
user.patch { ... }
// PUT /users/:id
user.put { ... }
}
}
```
### Middleware
In addition to prefixing path components, you can also add middleware to route groups.
```swift
app.get("fast-thing") { req in
...
}
app.group(RateLimitMiddleware(requestsPerMinute: 5)) { rateLimited in
rateLimited.get("slow-thing") { req in
...
}
}
```
This is especially useful for protecting subsets of your routes with different authentication middleware.
```swift
app.post("login") { ... }
let auth = app.grouped(AuthMiddleware())
auth.get("dashboard") { ... }
auth.get("logout") { ... }
```
## Redirections
Redirects are useful in a number of scenarios, such as forwarding old locations to new ones for SEO, redirecting an unauthenticated user to the login page or maintain backwards compatibility with the new version of your API.
To redirect a request, use:
```swift
req.redirect(to: "/some/new/path")
```
You can also specify the type of redirect, for example to redirect a page permanently (so that your SEO is updated correctly) use:
```swift
req.redirect(to: "/some/new/path", redirectType: .permanent)
```
The different `Redirect`s are:
* `.permanent` - returns a **301 Permanent** redirect
* `.normal` - returns a **303 see other** redirect. This is the default by Vapor and tells the client to follow the redirect with a **GET** request.
* `.temporary` - returns a **307 Temporary** redirect. This tells the client to preserve the HTTP method used in the request.
> To choose the proper redirection status code check out [the full list](https://en.wikipedia.org/wiki/List_of_HTTP_status_codes#3xx_redirection)
# Controllers
Controllers are a great way to organize your code. They are collections of methods that accept a request and return a response.
A good place to put your controllers is in the [Controllers](../getting-started/folder-structure.md#controllers) folder.
## Overview
Let's take a look at an example controller.
```swift
import Vapor
struct TodosController: RouteCollection {
func boot(routes: RoutesBuilder) throws {
let todos = routes.grouped("todos")
todos.get(use: index)
todos.post(use: create)
todos.group(":id") { todo in
todo.get(use: show)
todo.put(use: update)
todo.delete(use: delete)
}
}
func index(req: Request) async throws -> [Todo] {
try await Todo.query(on: req.db).all()
}
func create(req: Request) async throws -> Todo {
let todo = try req.content.decode(Todo.self)
try await todo.save(on: req.db)
return todo
}
func show(req: Request) async throws -> Todo {
guard let todo = try await Todo.find(req.parameters.get("id"), on: req.db) else {
throw Abort(.notFound)
}
return todo
}
func update(req: Request) async throws -> Todo {
guard let todo = try await Todo.find(req.parameters.get("id"), on: req.db) else {
throw Abort(.notFound)
}
let updatedTodo = try req.content.decode(Todo.self)
todo.title = updatedTodo.title
try await todo.save(on: req.db)
return todo
}
func delete(req: Request) async throws -> HTTPStatus {
guard let todo = try await Todo.find(req.parameters.get("id"), on: req.db) else {
throw Abort(.notFound)
}
try await todo.delete(on: req.db)
return .ok
}
}
```
Controller methods should always accept a `Request` and return something `ResponseEncodable`. This method can be asynchronous or synchronous.
Finally you need to register the controller in `routes.swift`:
```swift
try app.register(collection: TodosController())
```
# Content
Vapor's content API allows you to easily encode / decode Codable structs to / from HTTP messages. [JSON](https://tools.ietf.org/html/rfc7159) encoding is used by default with out-of-the-box support for [URL-Encoded Form](https://en.wikipedia.org/wiki/Percent-encoding#The_application/x-www-form-urlencoded_type) and [Multipart](https://tools.ietf.org/html/rfc2388). The API is also configurable, allowing for you to add, modify, or replace encoding strategies for certain HTTP content types.
## Overview
To understand how Vapor's content API works, you should first understand a few basics about HTTP messages. Take a look at the following example request.
```http
POST /greeting HTTP/1.1
content-type: application/json
content-length: 18
{"hello": "world"}
```
This request indicates that it contains JSON-encoded data using the `content-type` header and `application/json` media type. As promised, some JSON data follows after the headers in the body.
### Content Struct
The first step to decoding this HTTP message is creating a Codable type that matches the expected structure.
```swift
struct Greeting: Content {
var hello: String
}
```
Conforming the type to `Content` will automatically add conformance to `Codable` alongside additional utilities for working with the content API.
Once you have the content structure, you can decode it from the incoming request using `req.content`.
```swift
app.post("greeting") { req in
let greeting = try req.content.decode(Greeting.self)
print(greeting.hello) // "world"
return HTTPStatus.ok
}
```
The decode method uses the request's content type to find an appropriate decoder. If there is no decoder found, or the request does not contain the content type header, a `415` error will be thrown.
That means that this route automatically accepts all of the other supported content types, such as url-encoded form:
```http
POST /greeting HTTP/1.1
content-type: application/x-www-form-urlencoded
content-length: 11
hello=world
```
In the case of file uploads, your content property must be of type `Data`
```swift
struct Profile: Content {
var name: String
var email: String
var image: Data
}
```
### Supported Media Types
Below are the media types the content API supports by default.
|name|header value|media type|
|-|-|-|
|JSON|application/json|`.json`|
|Multipart|multipart/form-data|`.formData`|
|URL-Encoded Form|application/x-www-form-urlencoded|`.urlEncodedForm`|
|Plaintext|text/plain|`.plainText`|
|HTML|text/html|`.html`|
Not all media types support all `Codable` features. For example, JSON does not support top-level fragments and Plaintext does not support nested data.
## Query
Vapor's Content APIs support handling URL encoded data in the URL's query string.
### Decoding
To understand how decoding a URL query string works, take a look at the following example request.
```http
GET /hello?name=Vapor HTTP/1.1
content-length: 0
```
Just like the APIs for handling HTTP message body content, the first step for parsing URL query strings is to create a `struct` that matches the expected structure.
```swift
struct Hello: Content {
var name: String?
}
```
Note that `name` is an optional `String` since URL query strings should always be optional. If you want to require a parameter, use a route parameter instead.
Now that you have a `Content` struct for this route's expected query string, you can decode it.
```swift
app.get("hello") { req -> String in
let hello = try req.query.decode(Hello.self)
return "Hello, \(hello.name ?? "Anonymous")"
}
```
This route would result in the following response given the example request from above:
```http
HTTP/1.1 200 OK
content-length: 12
Hello, Vapor
```
If the query string were omitted, like in the following request, the name "Anonymous" would be used instead.
```http
GET /hello HTTP/1.1
content-length: 0
```
### Single Value
In addition to decoding to a `Content` struct, Vapor also supports fetching single values from the query string using subscripts.
```swift
let name: String? = req.query["name"]
```
## Hooks
Vapor will automatically call `beforeEncode` and `afterDecode` on a `Content` type. Default implementations are provided which do nothing, but you can use these methods to run custom logic.
```swift
// Runs after this Content is decoded. `mutating` is only required for structs, not classes.
mutating func afterDecode() throws {
// Name may not be passed in, but if it is, then it can't be an empty string.
self.name = self.name?.trimmingCharacters(in: .whitespacesAndNewlines)
if let name = self.name, name.isEmpty {
throw Abort(.badRequest, reason: "Name must not be empty.")
}
}
// Runs before this Content is encoded. `mutating` is only required for structs, not classes.
mutating func beforeEncode() throws {
// Have to *always* pass a name back, and it can't be an empty string.
guard
let name = self.name?.trimmingCharacters(in: .whitespacesAndNewlines),
!name.isEmpty
else {
throw Abort(.badRequest, reason: "Name must not be empty.")
}
self.name = name
}
```
## Override Defaults
The default encoders and decoders used by Vapor's Content APIs can be configured.
### Global
`ContentConfiguration.global` lets you change the encoders and decoders Vapor uses by default. This is useful for changing how your entire application parses and serializes data.
```swift
// create a new JSON encoder that uses unix-timestamp dates
let encoder = JSONEncoder()
encoder.dateEncodingStrategy = .secondsSince1970
// override the global encoder used for the `.json` media type
ContentConfiguration.global.use(encoder: encoder, for: .json)
```
Mutating `ContentConfiguration` is usually done in `configure.swift`.
### One-Off
Calls to encoding and decoding methods like `req.content.decode` support passing in custom coders for one-off usages.
```swift
// create a new JSON decoder that uses unix-timestamp dates
let decoder = JSONDecoder()
decoder.dateDecodingStrategy = .secondsSince1970
// decodes Hello struct using custom decoder
let hello = try req.content.decode(Hello.self, using: decoder)
```
## Custom Coders
Applications and third-party packages can add support for media types that Vapor does not support by default by creating custom coders.
### Content
Vapor specifies two protocols for coders capable of handling content in HTTP message bodies: `ContentDecoder` and `ContentEncoder`.
```swift
public protocol ContentEncoder {
func encode(_ encodable: E, to body: inout ByteBuffer, headers: inout HTTPHeaders) throws
where E: Encodable
}
public protocol ContentDecoder {
func decode(_ decodable: D.Type, from body: ByteBuffer, headers: HTTPHeaders) throws -> D
where D: Decodable
}
```
Conforming to these protocols allows your custom coders to be registered to `ContentConfiguration` as specified above.
### URL Query
Vapor specifies two protocols for coders capable of handling content in URL query strings: `URLQueryDecoder` and `URLQueryEncoder`.
```swift
public protocol URLQueryDecoder {
func decode(_ decodable: D.Type, from url: URI) throws -> D
where D: Decodable
}
public protocol URLQueryEncoder {
func encode(_ encodable: E, to url: inout URI) throws
where E: Encodable
}
```
Conforming to these protocols allows your custom coders to be registered to `ContentConfiguration` for handling URL query strings using the `use(urlEncoder:)` and `use(urlDecoder:)` methods.
### Custom `ResponseEncodable`
Another approach involves implementing `ResponseEncodable` on your types. Consider this trivial `HTML` wrapper type:
```swift
struct HTML {
let value: String
}
```
Then its `ResponseEncodable` implementation would look like this:
```swift
extension HTML: ResponseEncodable {
public func encodeResponse(for request: Request) -> EventLoopFuture {
var headers = HTTPHeaders()
headers.add(name: .contentType, value: "text/html")
return request.eventLoop.makeSucceededFuture(.init(
status: .ok, headers: headers, body: .init(string: value)
))
}
}
```
If you're using `async`/`await` you can use `AsyncResponseEncodable`:
```swift
extension HTML: AsyncResponseEncodable {
public func encodeResponse(for request: Request) async throws -> Response {
var headers = HTTPHeaders()
headers.add(name: .contentType, value: "text/html")
return .init(status: .ok, headers: headers, body: .init(string: value))
}
}
```
Note that this allows customizing the `Content-Type` header. See [`HTTPHeaders` reference](https://api.vapor.codes/vapor/response/headers) for more details.
You can then use `HTML` as a response type in your routes:
```swift
app.get { _ in
HTML(value: """
Hello, World!
""")
}
```
# Client
Vapor's client API allows you to make HTTP calls to external resources. It is built on [async-http-client](https://github.com/swift-server/async-http-client) and integrates with the [content](content.md) API.
## Overview
You can get access to the default client via `Application` or in a route handler via `Request`.
```swift
app.client // Client
app.get("test") { req in
req.client // Client
}
```
The application's client is useful for making HTTP requests during configuration time. If you are making HTTP requests in a route handler, always use the request's client.
### Methods
To make a `GET` request, pass the desired URL to the `get` convenience method.
```swift
let response = try await req.client.get("https://httpbin.org/status/200")
```
There are methods for each of the HTTP verbs like `get`, `post`, and `delete`. The client's response is returned as a future and contains the HTTP status, headers, and body.
### Content
Vapor's [content](content.md) API is available for handling data in client requests and responses. To encode content, query parameters or add headers to the request, use the `beforeSend` closure.
```swift
let response = try await req.client.post("https://httpbin.org/status/200") { req in
// Encode query string to the request URL.
try req.query.encode(["q": "test"])
// Encode JSON to the request body.
try req.content.encode(["hello": "world"])
// Add auth header to the request
let auth = BasicAuthorization(username: "something", password: "somethingelse")
req.headers.basicAuthorization = auth
}
// Handle the response.
```
You can also decode the response body using `Content` in a similar way:
```swift
let response = try await req.client.get("https://httpbin.org/json")
let json = try response.content.decode(MyJSONResponse.self)
```
If you're using futures you can use `flatMapThrowing`:
```swift
return req.client.get("https://httpbin.org/json").flatMapThrowing { res in
try res.content.decode(MyJSONResponse.self)
}.flatMap { json in
// Use JSON here
}
```
## Configuration
You can configure the underlying HTTP client via the application.
```swift
// Disable automatic redirect following.
app.http.client.configuration.redirectConfiguration = .disallow
```
Note that you must configure the default client _before_ using it for the first time.
# Validation
Vapor's Validation API helps you validate the body and query parameters of an incoming request before using the [Content](content.md) API to decode data.
## Introduction
Vapor's deep integration of Swift's type-safe `Codable` protocol means you don't need to worry about data validation as much compared to dynamically typed languages. However, there are still a few reasons why you might want to opt-in to explicit validation using the Validation API.
### Human-Readable Errors
Decoding structs using the [Content](content.md) API will yield errors if any of the data is not valid. However, these error messages can sometimes lack human-readability. For example, take the following string-backed enum:
```swift
enum Color: String, Codable {
case red, blue, green
}
```
If a user tries to pass the string `"purple"` to a property of type `Color`, they will get an error similar to the following:
```
Cannot initialize Color from invalid String value purple for key favoriteColor
```
While this error is technically correct and successfully protected the endpoint from an invalid value, it could do better informing the user about the mistake and which options are available. By using the Validation API, you can generate errors like the following:
```
favoriteColor is not red, blue, or green
```
Furthermore, `Codable` will stop attempting to decode a type as soon as the first error is hit. This means that even if there are many invalid properties in the request, the user will only see the first error. The Validation API will report all validation failures in a single request.
### Specific Validation
`Codable` handles type validation well, but sometimes you want more than that. For example, validating the contents of a string or validating the size of an integer. The Validation API has validators for helping to validate data like emails, character sets, integer ranges, and more.
## Validatable
To validate a request, you will need to generate a `Validations` collection. This is most commonly done by conforming an existing type to `Validatable`.
Let's take a look at how you could add validation to this simple `POST /users` endpoint. This guide assumes you are already familiar with the [Content](content.md) API.
```swift
enum Color: String, Codable {
case red, blue, green
}
struct CreateUser: Content {
var name: String
var username: String
var age: Int
var email: String
var favoriteColor: Color?
}
app.post("users") { req -> CreateUser in
let user = try req.content.decode(CreateUser.self)
// Do something with user.
return user
}
```
### Adding Validations
The first step is to conform the type you are decoding, in this case `CreateUser`, to `Validatable`. This can be done in an extension.
```swift
extension CreateUser: Validatable {
static func validations(_ validations: inout Validations) {
// Validations go here.
}
}
```
The static method `validations(_:)` will be called when `CreateUser` is validated. Any validations you want to perform should be added to the supplied `Validations` collection. Let's take a look at adding a simple validation to require that the user's email is valid.
```swift
validations.add("email", as: String.self, is: .email)
```
The first parameter is the value's expected key, in this case `"email"`. This should match the property name on the type being validated. The second parameter, `as`, is the expected type, in this case `String`. The type usually matches the property's type, but not always. Finally, one or more validators can be added after the third parameter, `is`. In this case, we are adding a single validator that checks if the value is an email address.
### Validating Request Content
Once you've conformed your type to `Validatable`, the static `validate(content:)` function can be used to validate request content. Add the following line before `req.content.decode(CreateUser.self)` in the route handler.
```swift
try CreateUser.validate(content: req)
```
Now, try sending the following request containing an invalid email:
```http
POST /users HTTP/1.1
Content-Length: 67
Content-Type: application/json
{
"age": 4,
"email": "foo",
"favoriteColor": "green",
"name": "Foo",
"username": "foo"
}
```
You should see the following error returned:
```
email is not a valid email address
```
### Validating Request Query
Types conforming to `Validatable` also have `validate(query:)` which can be used to validate a request's query string. Add the following lines to the route handler.
```swift
try CreateUser.validate(query: req)
req.query.decode(CreateUser.self)
```
Now, try sending the following request containing an invalid email in the query string.
```http
GET /users?age=4&email=foo&favoriteColor=green&name=Foo&username=foo HTTP/1.1
```
You should see the following error returned:
```
email is not a valid email address
```
### Integer Validation
Great, now let's try adding a validation for `age`.
```swift
validations.add("age", as: Int.self, is: .range(13...))
```
The age validation requires that the age is greater than or equal to `13`. If you try the same request from above, you should see a new error now:
```
age is less than minimum of 13, email is not a valid email address
```
### String Validation
Next, let's add validations for `name` and `username`.
```swift
validations.add("name", as: String.self, is: !.empty)
validations.add("username", as: String.self, is: .count(3...) && .alphanumeric)
```
The name validation uses the `!` operator to invert the `.empty` validation. This will require that the string is not empty.
The username validation combines two validators using `&&`. This will require that the string is at least 3 characters long _and_ contains only alphanumeric characters.
### Enum Validation
Finally, let's take a look at a slightly more advanced validation to check that the supplied `favoriteColor` is valid.
```swift
validations.add(
"favoriteColor", as: String.self,
is: .in("red", "blue", "green"),
required: false
)
```
Since it's not possible to decode a `Color` from an invalid value, this validation uses `String` as the base type. It uses the `.in` validator to verify that the value is a valid option: red, blue, or green. Since this value is optional, `required` is set to false to signal that validation should not fail if this key is missing from the request data.
Note that while the favorite color validation will pass if the key is missing, it will not pass if `null` is supplied. If you want to support `null`, change the validation type to `String?` and use the `.nil ||` (read as: "is nil or ...") convenience.
```swift
validations.add(
"favoriteColor", as: String?.self,
is: .nil || .in("red", "blue", "green"),
required: false
)
```
### Custom Errors
You might want to add custom human-readable errors to your `Validations` or `Validator`. To do so simply provide the additional `customFailureDescription` parameter which will override the default error.
```swift
validations.add(
"name",
as: String.self,
is: !.empty,
customFailureDescription: "Provided name is empty!"
)
validations.add(
"username",
as: String.self,
is: .count(3...) && .alphanumeric,
customFailureDescription: "Provided username is invalid!"
)
```
## Validators
Below is a list of the currently supported validators and a brief explanation of what they do.
|Validation|Description|
|-|-|
|`.ascii`|Contains only ASCII characters.|
|`.alphanumeric`|Contains only alphanumeric characters.|
|`.characterSet(_:)`|Contains only characters from supplied `CharacterSet`.|
|`.count(_:)`|Collection's count is within supplied bounds.|
|`.email`|Contains a valid email.|
|`.empty`|Collection is empty.|
|`.in(_:)`|Value is in supplied `Collection`.|
|`.nil`|Value is `null`.|
|`.range(_:)`|Value is within supplied `Range`.|
|`.url`|Contains a valid URL.|
|`.custom(_:, validationClosure: (value) -> Bool)`|Custom, once-off validation.|
Validators can also be combined to build complex validations using operators. More information on `.custom` validator at [Custom Validators](#custom-validators).
|Operator|Position|Description|
|-|-|-|
|`!`|prefix|Inverts a validator, requiring the opposite.|
|`&&`|infix|Combines two validators, requires both.|
|`\|\|`|infix|Combines two validators, requires one.|
## Custom Validators
There are two ways to create custom validators.
### Extending Validation API
Extending the Validation API is best suited for cases where you plan on using the custom validator in more than one `Content` object. In this section, we'll walk you through the steps to create a custom validator for validating zip codes.
First create a new type to represent the `ZipCode` validation results. This struct will be responsible for reporting whether a given string is a valid zip code.
```swift
extension ValidatorResults {
/// Represents the result of a validator that checks if a string is a valid zip code.
public struct ZipCode {
/// Indicates whether the input is a valid zip code.
public let isValidZipCode: Bool
}
}
```
Next, conform the new type to `ValidatorResult`, which defines the behavior expected from a custom validator.
```swift
extension ValidatorResults.ZipCode: ValidatorResult {
public var isFailure: Bool {
!self.isValidZipCode
}
public var successDescription: String? {
"is a valid zip code"
}
public var failureDescription: String? {
"is not a valid zip code"
}
}
```
Finally, implement the validation logic for zip codes. Use a regular expression to check whether the input string matches the format of a USA zip code.
```swift
private let zipCodeRegex: String = "^\\d{5}(?:[-\\s]\\d{4})?$"
extension Validator where T == String {
/// Validates whether a `String` is a valid zip code.
public static var zipCode: Validator {
.init { input in
guard let range = input.range(of: zipCodeRegex, options: [.regularExpression]),
range.lowerBound == input.startIndex && range.upperBound == input.endIndex
else {
return ValidatorResults.ZipCode(isValidZipCode: false)
}
return ValidatorResults.ZipCode(isValidZipCode: true)
}
}
}
```
Now that you've defined the custom `zipCode` validator, you can use it to validate zip codes in your application. Simply add the following line to your validation code:
```swift
validations.add("zipCode", as: String.self, is: .zipCode)
```
### `Custom` Validator
The `Custom` validator is best suited for cases where you want to validate a property in only one `Content` object. This implementation has the following two advantages compared to extending the Validation API:
- Simpler to implement custom validation logic.
- Shorter syntax.
In this section, we'll walk you through the steps to create a custom validator for checking whether an employee is part of our company by looking at the `nameAndSurname` property.
```swift
let allCompanyEmployees: [String] = [
"Everett Erickson",
"Sabrina Manning",
"Seth Gates",
"Melina Hobbs",
"Brendan Wade",
"Evie Richardson",
]
struct Employee: Content {
var nameAndSurname: String
var email: String
var age: Int
var role: String
static func validations(_ validations: inout Validations) {
validations.add(
"nameAndSurname",
as: String.self,
is: .custom("Validates whether employee is part of XYZ company by looking at name and surname.") { nameAndSurname in
for employee in allCompanyEmployees {
if employee == nameAndSurname {
return true
}
}
return false
}
)
}
}
```
# Async
## Async Await
Swift 5.5 introduced concurrency to the language in the form of `async`/`await`. This provides a first-class way of handling asynchronous code in Swift and Vapor applications.
Vapor is built on top of [SwiftNIO](https://github.com/apple/swift-nio.git), which provides primitive types for low-level asynchronous programming. These were (and still are) used throughout Vapor before `async`/`await` arrived. However, most app code can now be written using `async`/`await` instead of using `EventLoopFuture`s. This will simplify your code and make it much easier to reason about.
Most of Vapor's APIs now offer both `EventLoopFuture` and `async`/`await` versions for you to choose which is best. In general, you should only use one programming model per route handler and not mix and match in your code. For applications that need explicit control over event loops, or very high performance applications, you should continue to use `EventLoopFuture`s until custom executors are implemented. For everyone else, you should use `async`/`await` as the benefits or readability and maintainability far outweigh any small performance penalty.
### Migrating to async/await
There are a few steps needed to migrate to async/await. To start with, if using macOS you must be on macOS 12 Monterey or greater and Xcode 13.1 or greater. For other platforms you need to be running Swift 5.5 or greater. Next, make sure you've updated all your dependencies.
In your Package.swift, set the tools version to 5.5 at the top of the file:
```swift
// swift-tools-version:5.5
import PackageDescription
// ...
```
Next, set the platform version to macOS 12:
```swift
platforms: [
.macOS(.v12)
],
```
Finally update the `Run` target to mark it as an executable target:
```swift
.executableTarget(name: "Run", dependencies: [.target(name: "App")]),
```
Note: if you are deploying on Linux make sure you update the version of Swift there as well, e.g. on Heroku or in your Dockerfile. For example your Dockerfile would change to:
```diff
-FROM swift:5.2-focal as build
+FROM swift:5.5-focal as build
...
-FROM swift:5.2-focal-slim
+FROM swift:5.5-focal-slim
```
Now you can migrate existing code. Generally functions that return `EventLoopFuture`s are now `async`. For example:
```swift
routes.get("firstUser") { req -> EventLoopFuture in
User.query(on: req.db).first().unwrap(or: Abort(.notFound)).flatMap { user in
user.lastAccessed = Date()
return user.update(on: req.db).map {
return user.name
}
}
}
```
Now becomes:
```swift
routes.get("firstUser") { req async throws -> String in
guard let user = try await User.query(on: req.db).first() else {
throw Abort(.notFound)
}
user.lastAccessed = Date()
try await user.update(on: req.db)
return user.name
}
```
### Working with old and new APIs
If you encounter APIs that don't yet offer an `async`/`await` version, you can call `.get()` on a function that returns an `EventLoopFuture` to convert it.
E.g.
```swift
return someMethodCallThatReturnsAFuture().flatMap { futureResult in
// use futureResult
}
```
Can become
```swift
let futureResult = try await someMethodThatReturnsAFuture().get()
```
If you need to go the other way around you can convert
```swift
let myString = try await someAsyncFunctionThatGetsAString()
```
to
```swift
let promise = request.eventLoop.makePromise(of: String.self)
promise.completeWithTask {
try await someAsyncFunctionThatGetsAString()
}
let futureString: EventLoopFuture = promise.futureResult
```
## `EventLoopFuture`s
You may have noticed some APIs in Vapor expect or return a generic `EventLoopFuture` type. If this is your first time hearing about futures, they might seem a little confusing at first. But don't worry, this guide will show you how to take advantage of their powerful APIs.
Promises and futures are related, but distinct, types. Promises are used to _create_ futures. Most of the time, you will be working with futures returned by Vapor's APIs and you will not need to worry about creating promises.
|type|description|mutability|
|-|-|-|
|`EventLoopFuture`|Reference to a value that may not be available yet.|read-only|
|`EventLoopPromise`|A promise to provide some value asynchronously.|read/write|
Futures are an alternative to callback-based asynchronous APIs. Futures can be chained and transformed in ways that simple closures cannot.
## Transforming
Just like optionals and arrays in Swift, futures can be mapped and flat-mapped. These are the most common operations you will perform on futures.
|method|argument|description|
|-|-|-|
|[`map`](#map)|`(T) -> U`|Maps a future value to a different value.|
|[`flatMapThrowing`](#flatmapthrowing)|`(T) throws -> U`|Maps a future value to a different value or an error.|
|[`flatMap`](#flatmap)|`(T) -> EventLoopFuture`|Maps a future value to different _future_ value.|
|[`transform`](#transform)|`U`|Maps a future to an already available value.|
If you look at the method signatures for `map` and `flatMap` on `Optional` and `Array`, you will see that they are very similar to the methods available on `EventLoopFuture`.
### map
The `map` method allows you to transform the future's value to another value. Because the future's value may not be available yet (it may be the result of an asynchronous task) we must provide a closure to accept the value.
```swift
/// Assume we get a future string back from some API
let futureString: EventLoopFuture = ...
/// Map the future string to an integer
let futureInt = futureString.map { string in
print(string) // The actual String
return Int(string) ?? 0
}
/// We now have a future integer
print(futureInt) // EventLoopFuture
```
### flatMapThrowing
The `flatMapThrowing` method allows you to transform the future's value to another value _or_ throw an error.
!!! info "Info"
Because throwing an error must create a new future internally, this method is prefixed `flatMap` even though the closure does not accept a future return.
```swift
/// Assume we get a future string back from some API
let futureString: EventLoopFuture = ...
/// Map the future string to an integer
let futureInt = futureString.flatMapThrowing { string in
print(string) // The actual String
// Convert the string to an integer or throw an error
guard let int = Int(string) else {
throw Abort(...)
}
return int
}
/// We now have a future integer
print(futureInt) // EventLoopFuture
```
### flatMap
The `flatMap` method allows you to transform the future's value to another future value. It gets the name "flat" map because it is what allows you to avoid creating nested futures (e.g., `EventLoopFuture>`). In other words, it helps you keep your generics flat.
```swift
/// Assume we get a future string back from some API
let futureString: EventLoopFuture = ...
/// Assume we have created an HTTP client
let client: Client = ...
/// flatMap the future string to a future response
let futureResponse = futureString.flatMap { string in
client.get(string) // EventLoopFuture
}
/// We now have a future response
print(futureResponse) // EventLoopFuture
```
!!! info "Info"
If we instead used `map` in the above example, we would have ended up with: `EventLoopFuture>`.
To call a throwing method inside of a `flatMap`, use Swift's `do` / `catch` keywords and create a [completed future](#makefuture).
```swift
/// Assume future string and client from previous example.
let futureResponse = futureString.flatMap { string in
let url: URL
do {
// Some synchronous throwing method.
url = try convertToURL(string)
} catch {
// Use event loop to make pre-completed future.
return eventLoop.makeFailedFuture(error)
}
return client.get(url) // EventLoopFuture
}
```
### transform
The `transform` method allows you to modify a future's value, ignoring the existing value. This is especially useful for transforming the results of `EventLoopFuture` where the actual value of the future is not important.
!!! tip "Tip"
`EventLoopFuture`, sometimes called a signal, is a future whose sole purpose is to notify you of completion or failure of some async operation.
```swift
/// Assume we get a void future back from some API
let userDidSave: EventLoopFuture = ...
/// Transform the void future to an HTTP status
let futureStatus = userDidSave.transform(to: HTTPStatus.ok)
print(futureStatus) // EventLoopFuture
```
Even though we have supplied an already-available value to `transform`, this is still a _transformation_. The future will not complete until all previous futures have completed (or failed).
### Chaining
The great part about transformations on futures is that they can be chained. This allows you to express many conversions and subtasks easily.
Let's modify the examples from above to see how we can take advantage of chaining.
```swift
/// Assume we get a future string back from some API
let futureString: EventLoopFuture = ...
/// Assume we have created an HTTP client
let client: Client = ...
/// Transform the string to a url, then to a response
let futureResponse = futureString.flatMapThrowing { string in
guard let url = URL(string: string) else {
throw Abort(.badRequest, reason: "Invalid URL string: \(string)")
}
return url
}.flatMap { url in
client.get(url)
}
print(futureResponse) // EventLoopFuture
```
After the initial call to map, there is a temporary `EventLoopFuture` created. This future is then immediately flat-mapped to a `EventLoopFuture`
## Future
Let's take a look at some other methods for using `EventLoopFuture`.
### makeFuture
You can use an event loop to create pre-completed future with either the value or an error.
```swift
// Create a pre-succeeded future.
let futureString: EventLoopFuture = eventLoop.makeSucceededFuture("hello")
// Create a pre-failed future.
let futureString: EventLoopFuture = eventLoop.makeFailedFuture(error)
```
### whenComplete
You can use `whenComplete` to add a callback that will be executed when the future succeeds or fails.
```swift
/// Assume we get a future string back from some API
let futureString: EventLoopFuture = ...
futureString.whenComplete { result in
switch result {
case .success(let string):
print(string) // The actual String
case .failure(let error):
print(error) // A Swift Error
}
}
```
!!! note "Note"
You can add as many callbacks to a future as you want.
### Get
In case there is no concurrency-based alternative to an API, you can await for the future's value using `try await future.get()`.
```swift
/// Assume we get a future string back from some API
let futureString: EventLoopFuture = ...
/// Wait for the string to be ready
let string: String = try await futureString.get()
print(string) /// String
```
### Wait
!!! warning "Warning"
The `wait()` function is obsolete, see [`Get`](#get) for the recommended approach.
You can use `.wait()` to synchronously wait for the future to be completed. Since a future may fail, this call is throwing.
```swift
/// Assume we get a future string back from some API
let futureString: EventLoopFuture = ...
/// Block until the string is ready
let string = try futureString.wait()
print(string) /// String
```
`wait()` can only be used on a background thread or the main thread, i.e., in `configure.swift`. It can _not_ be used on an event loop thread, i.e., in route closures.
!!! warning "Warning"
Attempting to call `wait()` on an event loop thread will cause an assertion failure.
## Promise
Most of the time, you will be transforming futures returned by calls to Vapor's APIs. However, at some point you may need to create a promise of your own.
To create a promise, you will need access to an `EventLoop`. You can get access to an event loop from `Application` or `Request` depending on context.
```swift
let eventLoop: EventLoop
// Create a new promise for some string.
let promiseString = eventLoop.makePromise(of: String.self)
print(promiseString) // EventLoopPromise
print(promiseString.futureResult) // EventLoopFuture
// Completes the associated future.
promiseString.succeed("Hello")
// Fails the associated future.
promiseString.fail(...)
```
!!! info "Info"
A promise can only be completed once. Any subsequent completions will be ignored.
Promises can be completed (`succeed` / `fail`) from any thread. This is why promises require an event loop to be initialized. Promises ensure that the completion action gets returned to its event loop for execution.
## Event Loop
When your application boots, it will usually create one event loop for each core in the CPU it is running on. Each event loop has exactly one thread. If you are familiar with event loops from Node.js, the ones in Vapor are similar. The main difference is that Vapor can run multiple event loops in one process since Swift supports multi-threading.
Each time a client connects to your server, it will be assigned to one of the event loops. From that point on, all communication between the server and that client will happen on that same event loop (and by association, that event loop's thread).
The event loop is responsible for keeping track of each connected client's state. If there is a request from the client waiting to be read, the event loop triggers a read notification, causing the data to be read. Once the entire request is read, any futures waiting for that request's data will be completed.
In route closures, you can access the current event loop via `Request`.
```swift
req.eventLoop.makePromise(of: ...)
```
!!! warning "Warning"
Vapor expects that route closures will stay on `req.eventLoop`. If you hop threads, you must ensure access to `Request` and the final response future all happen on the request's event loop.
Outside of route closures, you can get one of the available event loops via `Application`.
```swift
app.eventLoopGroup.next().makePromise(of: ...)
```
### hop
You can change a future's event loop using `hop`.
```swift
futureString.hop(to: otherEventLoop)
```
## Blocking
Calling blocking code on an event loop thread can prevent your application from responding to incoming requests in a timely manner. An example of a blocking call would be something like `libc.sleep(_:)`.
```swift
app.get("hello") { req in
/// Puts the event loop's thread to sleep.
sleep(5)
/// Returns a simple string once the thread re-awakens.
return "Hello, world!"
}
```
`sleep(_:)` is a command that blocks the current thread for the number of seconds supplied. If you do blocking work like this directly on an event loop, the event loop will be unable to respond to any other clients assigned to it for the duration of the blocking work. In other words, if you do `sleep(5)` on an event loop, all of the other clients connected to that event loop (possibly hundreds or thousands) will be delayed for at least 5 seconds.
Make sure to run any blocking work in the background. Use promises to notify the event loop when this work is done in a non-blocking way.
```swift
app.get("hello") { req -> EventLoopFuture in
/// Dispatch some work to happen on a background thread
return req.application.threadPool.runIfActive(eventLoop: req.eventLoop) {
/// Puts the background thread to sleep
/// This will not affect any of the event loops
sleep(5)
/// When the "blocking work" has completed,
/// return the result.
return "Hello world!"
}
}
```
Not all blocking calls will be as obvious as `sleep(_:)`. If you are suspicious that a call you are using may be blocking, research the method itself or ask someone. The sections below go over how methods can block in more detail.
### I/O Bound
I/O bound blocking means waiting on a slow resource like a network or hard disk which can be orders of magnitude slower than the CPU. Blocking the CPU while you wait for these resources results in wasted time.
!!! danger "Danger"
Never make blocking I/O bound calls directly on an event loop.
All of Vapor's packages are built on SwiftNIO and use non-blocking I/O. However, there are many Swift packages and C libraries in the wild that use blocking I/O. Chances are if a function is doing disk or network IO and uses a synchronous API (no callbacks or futures) it is blocking.
### CPU Bound
Most of the time during a request is spent waiting for external resources like database queries and network requests to load. Because Vapor and SwiftNIO are non-blocking, this downtime can be used for fulfilling other incoming requests. However, some routes in your application may need to do heavy CPU bound work as the result of a request.
While an event loop is processing CPU bound work, it will be unable to respond to other incoming requests. This is normally fine since CPUs are fast and most CPU work web applications do is lightweight. But this can become a problem if routes with long running CPU work are preventing requests to faster routes from being responded to quickly.
Identifying long running CPU work in your app and moving it to background threads can help improve the reliability and responsiveness of your service. CPU bound work is more of a gray area than I/O bound work, and it is ultimately up to you to determine where you want to draw the line.
A common example of heavy CPU bound work is Bcrypt hashing during user signup and login. Bcrypt is deliberately very slow and CPU intensive for security reasons. This may be the most CPU intensive work a simple web application actually does. Moving hashing to a background thread can allow the CPU to interleave event loop work while calculating hashes which results in higher concurrency.
# Logging
Vapor's logging API is built on top of [SwiftLog](https://github.com/apple/swift-log). This means Vapor is compatible with all of SwiftLog's [backend implementations](https://github.com/apple/swift-log#backends).
## Logger
Instances of `Logger` are used for outputting log messages. Vapor provides a few easy ways to get access to a logger.
### Request
Each incoming `Request` has a unique logger that you should use for any logs specific to that request.
```swift
app.get("hello") { req -> String in
req.logger.info("Hello, logs!")
return "Hello, world!"
}
```
The request logger includes a unique UUID identifying the incoming request to make tracking logs easier.
```
[ INFO ] Hello, logs! [request-id: C637065A-8CB0-4502-91DC-9B8615C5D315] (App/routes.swift:10)
```
!!! info
Logger metadata will only be shown in debug log level or lower.
### Application
For log messages during app boot and configuration, use `Application`'s logger.
```swift
app.logger.info("Setting up migrations...")
app.migrations.use(...)
```
### Custom Logger
In situations where you don't have access to `Application` or `Request`, you can initialize a new `Logger`.
```swift
let logger = Logger(label: "dev.logger.my")
logger.info(...)
```
While custom loggers will still output to your configured logging backend, they will not have important metadata attached like request UUID. Use the request or application specific loggers wherever possible.
## Level
SwiftLog supports several different logging levels.
|name|description|
|-|-|
|trace|Appropriate for messages that contain information normally of use only when tracing the execution of a program.|
|debug|Appropriate for messages that contain information normally of use only when debugging a program.|
|info|Appropriate for informational messages.|
|notice|Appropriate for conditions that are not error conditions, but that may require special handling.|
|warning|Appropriate for messages that are not error conditions, but more severe than notice.|
|error|Appropriate for error conditions.|
|critical|Appropriate for critical error conditions that usually require immediate attention.|
When a `critical` message is logged, the logging backend is free to perform more heavy-weight operations to capture system state (such as capturing stack traces) to facilitate debugging.
By default, Vapor will use `info` level logging. When run with the `production` environment, `notice` will be used to improve performance.
### Changing Log Level
Regardless of environment mode, you can override the logging level to increase or decrease the amount of logs produced.
The first method is to pass the optional `--log` flag when booting your application.
```sh
swift run App serve --log debug
```
The second method is to set the `LOG_LEVEL` environment variable.
```sh
export LOG_LEVEL=debug
swift run App serve
```
Both of these can be done in Xcode by editing the `App` scheme.
## Configuration
SwiftLog is configured by bootstrapping the `LoggingSystem` once per process. Vapor projects typically do this in `entrypoint.swift`.
```swift
var env = try Environment.detect()
try LoggingSystem.bootstrap(from: &env)
```
`bootstrap(from:)` is a helper method provided by Vapor that will configure the default log handler based on command-line arguments and environment variables. The default log handler supports outputting messages to the terminal with ANSI color support.
### Custom Handler
You can override Vapor's default log handler and register your own.
```swift
import Logging
LoggingSystem.bootstrap { label in
StreamLogHandler.standardOutput(label: label)
}
```
All of SwiftLog's supported backends will work with Vapor. However, changing the log level with command-line arguments and environment variables is only compatible with Vapor's default log handler.
# Environment
Vapor's Environment API helps you configure your app dynamically. By default, your app will use the `development` environment. You can define other useful environments like `production` or `staging` and change how your app is configured in each case. You can also load in variables from the process's environment or `.env` (dotenv) files depending on your needs.
To access the current environment, use `app.environment`. You can switch on this property in `configure(_:)` to execute different configuration logic.
```swift
switch app.environment {
case .production:
app.databases.use(....)
default:
app.databases.use(...)
}
```
## Changing Environment
By default, your app will run in the `development` environment. You can change this by passing the `--env` (`-e`) flag during app boot.
```swift
swift run App serve --env production
```
Vapor includes the following environments:
|name|short|description|
|-|-|-|
|production|prod|Deployed to your users.|
|development|dev|Local development.|
|testing|test|For unit testing.|
!!! info
The `production` environment will default to `notice` level logging unless otherwise specified. All other environments default to `info`.
You can pass either the full or short name to the `--env` (`-e`) flag.
```swift
swift run App serve -e prod
```
## Process Variables
`Environment` offers a simple, string-based API for accessing the process's environment variables.
```swift
let foo = Environment.get("FOO")
print(foo) // String?
```
In addition to `get`, `Environment` offers a dynamic member lookup API via `process`.
```swift
let foo = Environment.process.FOO
print(foo) // String?
```
When running your app in the terminal, you can set environment variables using `export`.
```sh
export FOO=BAR
swift run App serve
```
When running your app in Xcode, you can set environment variables by editing the `App` scheme.
## .env (dotenv)
Dotenv files contain a list of key-value pairs to be automatically loaded into the environment. These files make it easy to configure environment variables without needing to set them manually.
Vapor will look for dotenv files in the current working directory. If you're using Xcode, make sure to set the working directory by editing the `App` scheme.
Assume the following `.env` file placed in your projects root folder:
```sh
FOO=BAR
```
When your application boots, you will be able to access the contents of this file like other process environment variables.
```swift
let foo = Environment.get("FOO")
print(foo) // String?
```
!!! info
Variables specified in `.env` files will not overwrite variables that already exist in the process environment.
Alongside `.env`, Vapor will also attempt to load a dotenv file for the current environment. For example, when in the `development` environment, Vapor will load `.env.development`. Any values in the specific environment file will take precedence over the general `.env` file.
A typical pattern is for projects to include a `.env` file as a template with default values. Specific environment files are ignored with the following pattern in `.gitignore`:
```gitignore
.env.*
```
When the project is cloned to a new computer, the template `.env` file can be copied and have the correct values inserted.
```sh
cp .env .env.development
vim .env.development
```
!!! warning
Dotenv files with sensitive information such as passwords should not be committed to version control.
If you're having difficulty getting dotenv files to load, try enabling debug logging with `--log debug` for more information.
## Custom Environments
To define a custom environment name, extend `Environment`.
```swift
extension Environment {
static var staging: Environment {
.custom(name: "staging")
}
}
```
The application's environment is usually set in `entrypoint.swift` using `Environment.detect()`.
```swift
@main
enum Entrypoint {
static func main() async throws {
var env = try Environment.detect()
try LoggingSystem.bootstrap(from: &env)
let app = Application(env)
defer { app.shutdown() }
try await configure(app)
try await app.runFromAsyncMainEntrypoint()
}
}
```
The `detect` method uses the process's command line arguments and parses the `--env` flag automatically. You can override this behavior by initializing a custom `Environment` struct.
```swift
let env = Environment(name: "testing", arguments: ["vapor"])
```
The arguments array must contain at least one argument which represents the executable name. Further arguments can be supplied to simulate passing arguments via the command line. This is especially useful for testing.
# Errors
Vapor builds on Swift's `Error` protocol for error handling. Route handlers can either `throw` an error or return a failed `EventLoopFuture`. Throwing or returning a Swift `Error` will result in a `500` status response and the error will be logged. `AbortError` and `DebuggableError` can be used to change the resulting response and logging respectively. The handling of errors is done by `ErrorMiddleware`. This middleware is added to the application by default and can be replaced with custom logic if desired.
## Abort
Vapor provides a default error struct named `Abort`. This struct conforms to both `AbortError` and `DebuggableError`. You can initialize it with an HTTP status and optional failure reason.
```swift
// 404 error, default "Not Found" reason used.
throw Abort(.notFound)
// 401 error, custom reason used.
throw Abort(.unauthorized, reason: "Invalid Credentials")
```
In old asynchronous situations where throwing is not supported and you must return an `EventLoopFuture`, like in a `flatMap` closure, you can return a failed future.
```swift
guard let user = user else {
req.eventLoop.makeFailedFuture(Abort(.notFound))
}
return user.save()
```
Vapor includes a helper extension for unwrapping futures with optional values: `unwrap(or:)`.
```swift
User.find(id, on: db)
.unwrap(or: Abort(.notFound))
.flatMap
{ user in
// Non-optional User supplied to closure.
}
```
If `User.find` returns `nil`, the future will be failed with the supplied error. Otherwise, the `flatMap` will be supplied with a non-optional value. If using `async`/`await` then you can handle optionals as normal:
```swift
guard let user = try await User.find(id, on: db) {
throw Abort(.notFound)
}
```
## Abort Error
By default, any Swift `Error` thrown or returned by a route closure will result in a `500 Internal Server Error` response. When built in debug mode, `ErrorMiddleware` will include a description of the error. This is stripped out for security reasons when the project is built in release mode.
To configure the resulting HTTP response status or reason for a particular error, conform it to `AbortError`.
```swift
import Vapor
enum MyError {
case userNotLoggedIn
case invalidEmail(String)
}
extension MyError: AbortError {
var reason: String {
switch self {
case .userNotLoggedIn:
return "User is not logged in."
case .invalidEmail(let email):
return "Email address is not valid: \(email)."
}
}
var status: HTTPStatus {
switch self {
case .userNotLoggedIn:
return .unauthorized
case .invalidEmail:
return .badRequest
}
}
}
```
## Debuggable Error
`ErrorMiddleware` uses the `Logger.report(error:)` method for logging errors thrown by your routes. This method will check for conformance to protocols like `CustomStringConvertible` and `LocalizedError` to log readable messages.
To customize error logging, you can conform your errors to `DebuggableError`. This protocol includes a number of helpful properties like a unique identifier, source location, and stack trace. Most of these properties are optional which makes adopting the conformance easy.
To best conform to `DebuggableError`, your error should be a struct so that it can store source and stack trace information if needed. Below is an example of the aforementioned `MyError` enum updated to use a `struct` and capture error source information.
```swift
import Vapor
struct MyError: DebuggableError {
enum Value {
case userNotLoggedIn
case invalidEmail(String)
}
var identifier: String {
switch self.value {
case .userNotLoggedIn:
return "userNotLoggedIn"
case .invalidEmail:
return "invalidEmail"
}
}
var reason: String {
switch self.value {
case .userNotLoggedIn:
return "User is not logged in."
case .invalidEmail(let email):
return "Email address is not valid: \(email)."
}
}
var value: Value
var source: ErrorSource?
init(
_ value: Value,
file: String = #file,
function: String = #function,
line: UInt = #line,
column: UInt = #column
) {
self.value = value
self.source = .init(
file: file,
function: function,
line: line,
column: column
)
}
}
```
`DebuggableError` has several other properties like `possibleCauses` and `suggestedFixes` that you can use to improve the debuggability of your errors. Take a look at the protocol itself for more information.
## Error Middleware
`ErrorMiddleware` is one of the only two middlewares added to your application by default. This middleware converts Swift errors that have been thrown or returned by your route handlers into HTTP responses. Without this middleware, errors thrown will result in the connection being closed without a response.
To customize error handling beyond what `AbortError` and `DebuggableError` provide, you can replace `ErrorMiddleware` with your own error handling logic. To do this, first remove the default error middleware by manually initializing `app.middleware`. Then, add your own error handling middleware as the first middleware to your application.
```swift
// Clear all default middleware (then, add back route logging)
app.middleware = .init()
app.middleware.use(RouteLoggingMiddleware(logLevel: .info))
// Add custom error handling middleware first.
app.middleware.use(MyErrorMiddleware())
```
Very few middleware should go _before_ the error handling middleware. A notable exception to this rule is `CORSMiddleware`.
# Fluent
Fluent is an [ORM](https://en.wikipedia.org/wiki/Object-relational_mapping) framework for Swift. It takes advantage of Swift's strong type system to provide an easy-to-use interface for your database. Using Fluent centers around the creation of model types which represent data structures in your database. These models are then used to perform create, read, update, and delete operations instead of writing raw queries.
## Configuration
When creating a project using `vapor new`, answer "yes" to including Fluent and choose which database driver you want to use. This will automatically add the dependencies to your new project as well as example configuration code.
### Existing Project
If you have an existing project that you want to add Fluent to, you will need to add two dependencies to your [package](../getting-started/spm.md):
- [vapor/fluent](https://github.com/vapor/fluent)@4.0.0
- One (or more) Fluent driver(s) of your choice
```swift
.package(url: "https://github.com/vapor/fluent.git", from: "4.0.0"),
.package(url: "https://github.com/vapor/fluent--driver.git", from: ),
```
```swift
.target(name: "App", dependencies: [
.product(name: "Fluent", package: "fluent"),
.product(name: "FluentDriver", package: "fluent--driver"),
.product(name: "Vapor", package: "vapor"),
]),
```
Once the packages are added as dependencies, you can configure your databases using `app.databases` in `configure.swift`.
```swift
import Fluent
import FluentDriver
app.databases.use(, as: )
```
Each of the Fluent drivers below has more specific instructions for configuration.
### Drivers
Fluent currently has four officially supported drivers. You can search GitHub for the tag [`fluent-driver`](https://github.com/topics/fluent-driver) for a full list of official and third-party Fluent database drivers.
#### PostgreSQL
PostgreSQL is an open source, standards compliant SQL database. It is easily configurable on most cloud hosting providers. This is Fluent's **recommended** database driver.
To use PostgreSQL, add the following dependencies to your package.
```swift
.package(url: "https://github.com/vapor/fluent-postgres-driver.git", from: "2.0.0")
```
```swift
.product(name: "FluentPostgresDriver", package: "fluent-postgres-driver")
```
Once the dependencies are added, configure the database's credentials with Fluent using `app.databases.use` in `configure.swift`.
```swift
import Fluent
import FluentPostgresDriver
app.databases.use(
.postgres(
configuration: .init(
hostname: "localhost",
username: "vapor",
password: "vapor",
database: "vapor",
tls: .disable
)
),
as: .psql
)
```
You can also parse the credentials from a database connection string.
```swift
try app.databases.use(.postgres(url: ""), as: .psql)
```
#### SQLite
SQLite is an open source, embedded SQL database. Its simplistic nature makes it a great candidate for prototyping and testing.
To use SQLite, add the following dependencies to your package.
```swift
.package(url: "https://github.com/vapor/fluent-sqlite-driver.git", from: "4.0.0")
```
```swift
.product(name: "FluentSQLiteDriver", package: "fluent-sqlite-driver")
```
Once the dependencies are added, configure the database with Fluent using `app.databases.use` in `configure.swift`.
```swift
import Fluent
import FluentSQLiteDriver
app.databases.use(.sqlite(.file("db.sqlite")), as: .sqlite)
```
You can also configure SQLite to store the database ephemerally in memory.
```swift
app.databases.use(.sqlite(.memory), as: .sqlite)
```
If you use an in-memory database, make sure to set Fluent to migrate automatically using `--auto-migrate` or run `app.autoMigrate()` after adding migrations.
```swift
app.migrations.add(CreateTodo())
try app.autoMigrate().wait()
// or
try await app.autoMigrate()
```
!!! tip
The SQLite configuration automatically enables foreign key constraints on all created connections, but does not alter foreign key configurations in the database itself. Deleting records in a database directly, might violate foreign key constraints and triggers.
#### MySQL
MySQL is a popular open source SQL database. It is available on many cloud hosting providers. This driver also supports MariaDB.
To use MySQL, add the following dependencies to your package.
```swift
.package(url: "https://github.com/vapor/fluent-mysql-driver.git", from: "4.0.0")
```
```swift
.product(name: "FluentMySQLDriver", package: "fluent-mysql-driver")
```
Once the dependencies are added, configure the database's credentials with Fluent using `app.databases.use` in `configure.swift`.
```swift
import Fluent
import FluentMySQLDriver
app.databases.use(.mysql(hostname: "localhost", username: "vapor", password: "vapor", database: "vapor"), as: .mysql)
```
You can also parse the credentials from a database connection string.
```swift
try app.databases.use(.mysql(url: ""), as: .mysql)
```
To configure a local connection without SSL certificate involved, you should disable certificate verification. You might need to do this for example if connecting to a MySQL 8 database in Docker.
```swift
var tls = TLSConfiguration.makeClientConfiguration()
tls.certificateVerification = .none
app.databases.use(.mysql(
hostname: "localhost",
username: "vapor",
password: "vapor",
database: "vapor",
tlsConfiguration: tls
), as: .mysql)
```
!!! warning
Do not disable certificate verification in production. You should provide a certificate to the `TLSConfiguration` to verify against.
#### MongoDB
MongoDB is a popular schemaless NoSQL database designed for programmers. The driver supports all cloud hosting providers and self-hosted installations from version 3.4 and up.
!!! note
This driver is powered by a community created and maintained MongoDB client called [MongoKitten](https://github.com/OpenKitten/MongoKitten). MongoDB maintains an official client, [mongo-swift-driver](https://github.com/mongodb/mongo-swift-driver), along with a Vapor integration, [mongodb-vapor](https://github.com/mongodb/mongodb-vapor).
To use MongoDB, add the following dependencies to your package.
```swift
.package(url: "https://github.com/vapor/fluent-mongo-driver.git", from: "1.0.0"),
```
```swift
.product(name: "FluentMongoDriver", package: "fluent-mongo-driver")
```
Once the dependencies are added, configure the database's credentials with Fluent using `app.databases.use` in `configure.swift`.
To connect, pass a connection string in the standard MongoDB [connection URI format](https://www.mongodb.com/docs/manual/reference/connection-string/).
```swift
import Fluent
import FluentMongoDriver
try app.databases.use(.mongo(connectionString: ""), as: .mongo)
```
## Models
Models represent fixed data structures in your database, like tables or collections. Models have one or more fields that store codable values. All models also have a unique identifier. Property wrappers are used to denote identifiers and fields as well as more complex mappings mentioned later. Take a look at the following model which represents a galaxy.
```swift
final class Galaxy: Model {
// Name of the table or collection.
static let schema = "galaxies"
// Unique identifier for this Galaxy.
@ID(key: .id)
var id: UUID?
// The Galaxy's name.
@Field(key: "name")
var name: String
// Creates a new, empty Galaxy.
init() { }
// Creates a new Galaxy with all properties set.
init(id: UUID? = nil, name: String) {
self.id = id
self.name = name
}
}
```
To create a new model, create a new class conforming to `Model`.
!!! tip
It's recommended to mark model classes `final` to improve performance and simplify conformance requirements.
The `Model` protocol's first requirement is the static string `schema`.
```swift
static let schema = "galaxies"
```
This property tells Fluent which table or collection the model corresponds to. This can be a table that already exists in the database or one that you will create with a [migration](#migrations). The schema is usually `snake_case` and plural.
### Identifier
The next requirement is an identifier field named `id`.
```swift
@ID(key: .id)
var id: UUID?
```
This field must use the `@ID` property wrapper. Fluent recommends using `UUID` and the special `.id` field key since this is compatible with all of Fluent's drivers.
If you want to use a custom ID key or type, use the [`@ID(custom:)`](model.md#custom-identifier) overload.
### Fields
After the identifier is added, you can add however many fields you'd like to store additional information. In this example, the only additional field is the galaxy's name.
```swift
@Field(key: "name")
var name: String
```
For simple fields, the `@Field` property wrapper is used. Like `@ID`, the `key` parameter specifies the field's name in the database. This is especially useful for cases where database field naming convention may be different than in Swift, e.g., using `snake_case` instead of `camelCase`.
Next, all models require an empty init. This allows Fluent to create new instances of the model.
```swift
init() { }
```
Finally, you can add a convenience init for your model that sets all of its properties.
```swift
init(id: UUID? = nil, name: String) {
self.id = id
self.name = name
}
```
Using convenience inits is especially helpful if you add new properties to your model as you can get compile-time errors if the init method changes.
## Migrations
If your database uses pre-defined schemas, like SQL databases, you will need a migration to prepare the database for your model. Migrations are also useful for seeding databases with data. To create a migration, define a new type conforming to the `Migration` or `AsyncMigration` protocol. Take a look at the following migration for the previously defined `Galaxy` model.
```swift
struct CreateGalaxy: AsyncMigration {
// Prepares the database for storing Galaxy models.
func prepare(on database: Database) async throws {
try await database.schema("galaxies")
.id()
.field("name", .string)
.create()
}
// Optionally reverts the changes made in the prepare method.
func revert(on database: Database) async throws {
try await database.schema("galaxies").delete()
}
}
```
The `prepare` method is used for preparing the database to store `Galaxy` models.
### Schema
In this method, `database.schema(_:)` is used to create a new `SchemaBuilder`. One or more `field`s are then added to the builder before calling `create()` to create the schema.
Each field added to the builder has a name, type, and optional constraints.
```swift
field(, , )
```
There is a convenience `id()` method for adding `@ID` properties using Fluent's recommended defaults.
Reverting the migration undoes any changes made in the prepare method. In this case, that means deleting the Galaxy's schema.
Once the migration is defined, you must tell Fluent about it by adding it to `app.migrations` in `configure.swift`.
```swift
app.migrations.add(CreateGalaxy())
```
### Migrate
To run migrations, call `swift run App migrate` from the command line or add `migrate` as an argument to Xcode's App scheme.
```
$ swift run App migrate
Migrate Command: Prepare
The following migration(s) will be prepared:
+ CreateGalaxy on default
Would you like to continue?
y/n> y
Migration successful
```
## Querying
Now that you've successfully created a model and migrated your database, you're ready to make your first query.
### All
Take a look at the following route which will return an array of all the galaxies in the database.
```swift
app.get("galaxies") { req async throws in
try await Galaxy.query(on: req.db).all()
}
```
In order to return a Galaxy directly in a route closure, add conformance to `Content`.
```swift
final class Galaxy: Model, Content {
...
}
```
`Galaxy.query` is used to create a new query builder for the model. `req.db` is a reference to the default database for your application. Finally, `all()` returns all of the models stored in the database.
If you compile and run the project and request `GET /galaxies`, you should see an empty array returned. Let's add a route for creating a new galaxy.
### Create
Following RESTful convention, use the `POST /galaxies` endpoint for creating a new galaxy. Since models are codable, you can decode a galaxy directly from the request body.
```swift
app.post("galaxies") { req -> EventLoopFuture in
let galaxy = try req.content.decode(Galaxy.self)
return galaxy.create(on: req.db)
.map { galaxy }
}
```
!!! seealso
See [Content → Overview](../basics/content.md) for more information about decoding request bodies.
Once you have an instance of the model, calling `create(on:)` saves the model to the database. This returns an `EventLoopFuture` which signals that the save has completed. Once the save completes, return the newly created model using `map`.
If you're using `async`/`await` you can write your code as so:
```swift
app.post("galaxies") { req async throws -> Galaxy in
let galaxy = try req.content.decode(Galaxy.self)
try await galaxy.create(on: req.db)
return galaxy
}
```
In this case, the async version doesn't return anything, but will return once the save has completed.
Build and run the project and send the following request.
```http
POST /galaxies HTTP/1.1
content-length: 21
content-type: application/json
{
"name": "Milky Way"
}
```
You should get the created model back with an identifier as the response.
```json
{
"id": ...,
"name": "Milky Way"
}
```
Now, if you query `GET /galaxies` again, you should see the newly created galaxy returned in the array.
## Relations
What are galaxies without stars! Let's take a quick look at Fluent's powerful relational features by adding a one-to-many relation between `Galaxy` and a new `Star` model.
```swift
final class Star: Model, Content {
// Name of the table or collection.
static let schema = "stars"
// Unique identifier for this Star.
@ID(key: .id)
var id: UUID?
// The Star's name.
@Field(key: "name")
var name: String
// Reference to the Galaxy this Star is in.
@Parent(key: "galaxy_id")
var galaxy: Galaxy
// Creates a new, empty Star.
init() { }
// Creates a new Star with all properties set.
init(id: UUID? = nil, name: String, galaxyID: UUID) {
self.id = id
self.name = name
self.$galaxy.id = galaxyID
}
}
```
### Parent
The new `Star` model is very similar to `Galaxy` except for a new field type: `@Parent`.
```swift
@Parent(key: "galaxy_id")
var galaxy: Galaxy
```
The parent property is a field that stores another model's identifier. The model holding the reference is called the "child" and the referenced model is called the "parent". This type of relation is also known as "one-to-many". The `key` parameter to the property specifies the field name that should be used to store the parent's key in the database.
In the init method, the parent identifier is set using `$galaxy`.
```swift
self.$galaxy.id = galaxyID
```
By prefixing the parent property's name with `$`, you access the underlying property wrapper. This is required for getting access to the internal `@Field` that stores the actual identifier value.
!!! seealso
Check out the Swift Evolution proposal for property wrappers for more information: [[SE-0258] Property Wrappers](https://github.com/swiftlang/swift-evolution/blob/main/proposals/0258-property-wrappers.md)
Next, create a migration to prepare the database for handling `Star`.
```swift
struct CreateStar: AsyncMigration {
// Prepares the database for storing Star models.
func prepare(on database: Database) async throws {
try await database.schema("stars")
.id()
.field("name", .string)
.field("galaxy_id", .uuid, .references("galaxies", "id"))
.create()
}
// Optionally reverts the changes made in the prepare method.
func revert(on database: Database) async throws {
try await database.schema("stars").delete()
}
}
```
This is mostly the same as galaxy's migration except for the additional field to store the parent galaxy's identifier.
```swift
field("galaxy_id", .uuid, .references("galaxies", "id"))
```
This field specifies an optional constraint telling the database that the field's value references the field "id" in the "galaxies" schema. This is also known as a foreign key and helps ensure data integrity.
Once the migration is created, add it to `app.migrations` after the `CreateGalaxy` migration.
```swift
app.migrations.add(CreateGalaxy())
app.migrations.add(CreateStar())
```
Since migrations run in order, and `CreateStar` references the galaxies schema, ordering is important. Finally, [run the migrations](#migrate) to prepare the database.
Add a route for creating new stars.
```swift
app.post("stars") { req async throws -> Star in
let star = try req.content.decode(Star.self)
try await star.create(on: req.db)
return star
}
```
Create a new star referencing the previously created galaxy using the following HTTP request.
```http
POST /stars HTTP/1.1
content-length: 36
content-type: application/json
{
"name": "Sun",
"galaxy": {
"id": ...
}
}
```
You should see the newly created star returned with a unique identifier.
```json
{
"id": ...,
"name": "Sun",
"galaxy": {
"id": ...
}
}
```
### Children
Now let's take a look at how you can utilize Fluent's eager-loading feature to automatically return a galaxy's stars in the `GET /galaxies` route. Add the following property to the `Galaxy` model.
```swift
// All the Stars in this Galaxy.
@Children(for: \.$galaxy)
var stars: [Star]
```
The `@Children` property wrapper is the inverse of `@Parent`. It takes a key-path to the child's `@Parent` field as the `for` argument. Its value is an array of children since zero or more child models may exist. No changes to the galaxy's migration are needed since all the information needed for this relation is stored on `Star`.
### Eager Load
Now that the relation is complete, you can use the `with` method on the query builder to automatically fetch and serialize the galaxy-star relation.
```swift
app.get("galaxies") { req in
try await Galaxy.query(on: req.db).with(\.$stars).all()
}
```
A key-path to the `@Children` relation is passed to `with` to tell Fluent to automatically load this relation in all of the resulting models. Build and run and send another request to `GET /galaxies`. You should now see the stars automatically included in the response.
```json
[
{
"id": ...,
"name": "Milky Way",
"stars": [
{
"id": ...,
"name": "Sun",
"galaxy": {
"id": ...
}
}
]
}
]
```
## Query Logging
The Fluent drivers log the generated SQL at the debug log level. Some drivers, like FluentPostgreSQL, allow this to be configured when you configure the database.
To set the log level, in **configure.swift** (or where you set up your application) add:
```swift
app.logger.logLevel = .debug
```
This sets the log level to debug. When you next build and run your app, the SQL statements generated by Fluent will be logged to the console.
## Next steps
Congratulations on creating your first models and migrations and performing basic create and read operations. For more in-depth information on all of these features, check out their respective sections in the Fluent guide.
# Models
Models represent data stored in tables or collections in your database. Models have one or more fields that store codable values. All models have a unique identifier. Property wrappers are used to denote identifiers, fields, and relations.
Below is an example of a simple model with one field. Note that models do not describe the entire database schema, such as constraints, indexes, and foreign keys. Schemas are defined in [migrations](migration.md). Models are focused on representing the data stored in your database schemas.
```swift
final class Planet: Model {
// Name of the table or collection.
static let schema = "planets"
// Unique identifier for this Planet.
@ID(key: .id)
var id: UUID?
// The Planet's name.
@Field(key: "name")
var name: String
// Creates a new, empty Planet.
init() { }
// Creates a new Planet with all properties set.
init(id: UUID? = nil, name: String) {
self.id = id
self.name = name
}
}
```
## Schema
All models require a static, get-only `schema` property. This string references the name of the table or collection this model represents.
```swift
final class Planet: Model {
// Name of the table or collection.
static let schema = "planets"
}
```
When querying this model, data will be fetched from and stored to the schema named `"planets"`.
!!! tip
The schema name is typically the class name pluralized and lowercased.
## Identifier
All models must have an `id` property defined using the `@ID` property wrapper. This field uniquely identifies instances of your model.
```swift
final class Planet: Model {
// Unique identifier for this Planet.
@ID(key: .id)
var id: UUID?
}
```
By default, the `@ID` property should use the special `.id` key which resolves to an appropriate key for the underlying database driver. For SQL this is `"id"` and for NoSQL it is `"_id"`.
The `@ID` should also be of type `UUID`. This is the only identifier value currently supported by all database drivers. Fluent will automatically generate new UUID identifiers when models are created.
`@ID` has an optional value since unsaved models may not have an identifier yet. To get the identifier or throw an error, use `requireID`.
```swift
let id = try planet.requireID()
```
### Exists
`@ID` has an `exists` property that represents whether the model exists in the database or not. When you initialize a model, the value is `false`. After you save a model or when you fetch a model from the database, the value is `true`. This property is mutable.
```swift
if planet.$id.exists {
// This model exists in database.
}
```
### Custom Identifier
Fluent supports custom identifier keys and types using the `@ID(custom:)` overload.
```swift
final class Planet: Model {
// Unique identifier for this Planet.
@ID(custom: "foo")
var id: Int?
}
```
The above example uses an `@ID` with custom key `"foo"` and identifier type `Int`. This is compatible with SQL databases using auto-incrementing primary keys, but is not compatible with NoSQL.
Custom `@ID`s allow the user to specify how the identifier should be generated using the `generatedBy` parameter.
```swift
@ID(custom: "foo", generatedBy: .user)
```
The `generatedBy` parameter supports these cases:
|Generated By|Description|
|-|-|
|`.user`|`@ID` property is expected to be set before saving a new model.|
|`.random`|`@ID` value type must conform to `RandomGeneratable`.|
|`.database`|Database is expected to generate a value upon save.|
If the `generatedBy` parameter is omitted, Fluent will attempt to infer an appropriate case based on the `@ID` value type. For example, `Int` will default to `.database` generation unless otherwise specified.
## Initializer
Models must have an empty initializer method.
```swift
final class Planet: Model {
// Creates a new, empty Planet.
init() { }
}
```
Fluent requires this method internally to initialize models returned by queries. It is also used for reflection.
You may want to add a convenience initializer to your model that accepts all properties.
```swift
final class Planet: Model {
// Creates a new Planet with all properties set.
init(id: UUID? = nil, name: String) {
self.id = id
self.name = name
}
}
```
Using convenience initializers makes it easier to add new properties to the model in the future.
## Field
Models can have zero or more `@Field` properties for storing data.
```swift
final class Planet: Model {
// The Planet's name.
@Field(key: "name")
var name: String
}
```
Fields require the database key to be explicitly defined. This is not required to be the same as the property name.
!!! tip
Fluent recommends using `snake_case` for database keys and `camelCase` for property names.
Field values can be any type that conforms to `Codable`. Storing nested structures and arrays in `@Field` is supported, but filtering operations are limited. See [`@Group`](#group) for an alternative.
For fields that contain an optional value, use `@OptionalField`.
```swift
@OptionalField(key: "tag")
var tag: String?
```
!!! warning
A non-optional field that has a `willSet` property observer that references its current value or a `didSet` property observer that references its `oldValue` will result in a fatal error.
## Relations
Models can have zero or more relation properties referencing other models like `@Parent`, `@Children`, and `@Siblings`. Learn more about relations in the [relations](relations.md) section.
## Timestamp
`@Timestamp` is a special type of `@Field` that stores a `Foundation.Date`. Timestamps are set automatically by Fluent according to the chosen trigger.
```swift
final class Planet: Model {
// When this Planet was created.
@Timestamp(key: "created_at", on: .create)
var createdAt: Date?
// When this Planet was last updated.
@Timestamp(key: "updated_at", on: .update)
var updatedAt: Date?
}
```
`@Timestamp` supports the following triggers.
|Trigger|Description|
|-|-|
|`.create`|Set when a new model instance is saved to the database.|
|`.update`|Set when an existing model instance is saved to the database.|
|`.delete`|Set when a model is deleted from the database. See [soft delete](#soft-delete).|
`@Timestamp`'s date value is optional and should be set to `nil` when initializing a new model.
### Timestamp Format
By default, `@Timestamp` will use an efficient `datetime` encoding based on your database driver. You can customize how the timestamp is stored in the database using the `format` parameter.
```swift
// Stores an ISO 8601 formatted timestamp representing
// when this model was last updated.
@Timestamp(key: "updated_at", on: .update, format: .iso8601)
var updatedAt: Date?
```
Note that the associated migration for this `.iso8601` example would require storage in `.string` format.
```swift
.field("updated_at", .string)
```
Available timestamp formats are listed below.
|Format|Description|Type|
|-|-|-|
|`.default`|Uses efficient `datetime` encoding for specific database.|Date|
|`.iso8601`|[ISO 8601](https://en.wikipedia.org/wiki/ISO_8601) string. Supports `withMilliseconds` parameter.|String|
|`.unix`|Seconds since Unix epoch including fraction.|Double|
You can access the raw timestamp value directly using the `timestamp` property.
```swift
// Manually set the timestamp value on this ISO 8601
// formatted @Timestamp.
model.$updatedAt.timestamp = "2020-06-03T16:20:14+00:00"
```
### Soft Delete
Adding a `@Timestamp` that uses the `.delete` trigger to your model will enable soft-deletion.
```swift
final class Planet: Model {
// When this Planet was deleted.
@Timestamp(key: "deleted_at", on: .delete)
var deletedAt: Date?
}
```
Soft-deleted models still exist in the database after deletion, but will not be returned in queries.
!!! tip
You can manually set an on delete timestamp to a date in the future. This can be used as an expiration date.
To force a soft-deletable model to be removed from the database, use the `force` parameter in `delete`.
```swift
// Deletes from the database even if the model
// is soft deletable.
model.delete(force: true, on: database)
```
To restore a soft-deleted model, use the `restore` method.
```swift
// Clears the on delete timestamp allowing this
// model to be returned in queries.
model.restore(on: database)
```
To include soft-deleted models in a query, use `withDeleted`.
```swift
// Fetches all planets including soft deleted.
Planet.query(on: database).withDeleted().all()
```
## Enum
`@Enum` is a special type of `@Field` for storing string representable types as native database enums. Native database enums provide an added layer of type safety to your database and may be more performant than raw enums.
```swift
// String representable, Codable enum for animal types.
enum Animal: String, Codable {
case dog, cat
}
final class Pet: Model {
// Stores type of animal as a native database enum.
@Enum(key: "type")
var type: Animal
}
```
Only types conforming to `RawRepresentable` where `RawValue` is `String` are compatible with `@Enum`. `String` backed enums meet this requirement by default.
To store an optional enum, use `@OptionalEnum`.
The database must be prepared to handle enums via a migration. See [enum](schema.md#enum) for more information.
### Raw Enums
Any enum backed by a `Codable` type, like `String` or `Int`, can be stored in `@Field`. It will be stored in the database as the raw value.
## Group
`@Group` allows you to store a nested group of fields as a single property on your model. Unlike Codable structs stored in a `@Field`, the fields in a `@Group` are queryable. Fluent achieves this by storing `@Group` as a flat structure in the database.
To use a `@Group`, first define the nested structure you would like to store using the `Fields` protocol. This is very similar to `Model` except no identifier or schema name is required. You can store many properties here that `Model` supports like `@Field`, `@Enum`, or even another `@Group`.
```swift
// A pet with name and animal type.
final class Pet: Fields {
// The pet's name.
@Field(key: "name")
var name: String
// The type of pet.
@Field(key: "type")
var type: String
// Creates a new, empty Pet.
init() { }
}
```
After you've created the fields definition, you can use it as the value of a `@Group` property.
```swift
final class User: Model {
// The user's nested pet.
@Group(key: "pet")
var pet: Pet
}
```
A `@Group`'s fields are accessible via dot-syntax.
```swift
let user: User = ...
print(user.pet.name) // String
```
You can query nested fields like normal using dot-syntax on the property wrappers.
```swift
User.query(on: database).filter(\.$pet.$name == "Zizek").all()
```
In the database, `@Group` is stored as a flat structure with keys joined by `_`. Below is an example of how `User` would look in the database.
|id|name|pet_name|pet_type|
|-|-|-|-|
|1|Tanner|Zizek|Cat|
|2|Logan|Runa|Dog|
## Codable
Models conform to `Codable` by default. This means you can use your models with Vapor's [content API](../basics/content.md) by adding conformance to the `Content` protocol.
```swift
extension Planet: Content { }
app.get("planets") { req async throws in
// Return an array of all planets.
try await Planet.query(on: req.db).all()
}
```
When serializing to / from `Codable`, model properties will use their variable names instead of keys. Relations will serialize as nested structures and any eager loaded data will be included.
!!! info
We recommend that for almost all cases you use a DTO instead of a model for your API responses and request bodies. See [Data Transfer Object](#data-transfer-object) for more information.
### Data Transfer Object
Model's default `Codable` conformance can make simple usage and prototyping easier. However, it exposes the underlying database information to the API. This is usually not desirable from both a security standpoint - returning sensitive fields such as a user's password hash is a bad idea - and a usability point of view. It makes it difficult to change the database schema without breaking the API, accept or return data in a different format, or to add or remove fields from the API.
For most cases you shoud use a DTO, or data transfer object instead of a model (this is also known as a domain transfer object). A DTO is a separate `Codable` type representing the data structure you would like to encode or decode. These decouple your API from your database schema and allow you to make changes to your models without breaking your app's public API, have different versions and make your API nicer to use for your clients.
Assume the following `User` model in the upcoming examples.
```swift
// Abridged user model for reference.
final class User: Model {
@ID(key: .id)
var id: UUID?
@Field(key: "first_name")
var firstName: String
@Field(key: "last_name")
var lastName: String
}
```
One common use case for DTOs is in implementing `PATCH` requests. These requests only include values for fields that should be updated. Attempting to decode a `Model` directly from such a request would fail if any of the required fields were missing. In the example below, you can see a DTO being used to decode request data and update a model.
```swift
// Structure of PATCH /users/:id request.
struct PatchUser: Decodable {
var firstName: String?
var lastName: String?
}
app.patch("users", ":id") { req async throws -> User in
// Decode the request data.
let patch = try req.content.decode(PatchUser.self)
// Fetch the desired user from the database.
guard let user = try await User.find(req.parameters.get("id"), on: req.db) else {
throw Abort(.notFound)
}
// If first name was supplied, update it.
if let firstName = patch.firstName {
user.firstName = firstName
}
// If new last name was supplied, update it.
if let lastName = patch.lastName {
user.lastName = lastName
}
// Save the user and return it.
try await user.save(on: req.db)
return user
}
```
Another common use case for DTOs is customizing the format of your API responses. The example below shows how a DTO can be used to add a computed field to a response.
```swift
// Structure of GET /users response.
struct GetUser: Content {
var id: UUID
var name: String
}
app.get("users") { req async throws -> [GetUser] in
// Fetch all users from the database.
let users = try await User.query(on: req.db).all()
return try users.map { user in
// Convert each user to GET return type.
try GetUser(
id: user.requireID(),
name: "\(user.firstName) \(user.lastName)"
)
}
}
```
Another common use case is when dealing with relations, such as parent relations or children relations. See [the Parent documentation](relations.md#encoding-and-decoding-of-parents) for an example of how to use a DTO to make it easy to decode a model with a `@Parent` relation.
Even if the DTO's structure is identical to model's `Codable` conformance, having it as a separate type can help keep large projects tidy. If you ever need to make a change to your models properties, you don't have to worry about breaking your app's public API. You may also consider putting your DTOs in a separate package that can be shared with consumers of your API and adding `Content` conformance in your Vapor app.
## Alias
The `ModelAlias` protocol lets you uniquely identify a model being joined multiple times in a query. For more information, see [joins](query.md#join).
## Save
To save a model to the database, use the `save(on:)` method.
```swift
planet.save(on: database)
```
This method will call `create` or `update` internally depending on whether the model already exists in the database.
### Create
You can call the `create` method to save a new model to the database.
```swift
let planet = Planet(name: "Earth")
planet.create(on: database)
```
`create` is also available on an array of models. This saves all of the models to the database in a single batch / query.
```swift
// Example of batch create.
[earth, mars].create(on: database)
```
!!! warning
Models using [`@ID(custom:)`](#custom-identifier) with the `.database` generator (usually autoincrementing `Int`s) will not have their newly created identifiers accessible after batch create. For situations where you need to access the identifiers, call `create` on each model.
To create an array of models separately, use `map` + `flatten`.
```swift
[earth, mars].map { $0.create(on: database) }
.flatten(on: database.eventLoop)
```
If using `async`/`await` you can use:
```swift
await withThrowingTaskGroup(of: Void.self) { taskGroup in
[earth, mars].forEach { model in
taskGroup.addTask { try await model.create(on: database) }
}
}
```
### Update
You can call the `update` method to save a model that was fetched from the database.
```swift
guard let planet = try await Planet.find(..., on: database) else {
throw Abort(.notFound)
}
planet.name = "Earth"
try await planet.update(on: database)
```
To update an array of models, use `map` + `flatten`.
```swift
[earth, mars].map { $0.update(on: database) }
.flatten(on: database.eventLoop)
// TOOD
```
## Query
Models expose a static method `query(on:)` that returns a query builder.
```swift
Planet.query(on: database).all()
```
Learn more about querying in the [query](query.md) section.
## Find
Models have a static `find(_:on:)` method for looking up a model instance by identifier.
```swift
Planet.find(req.parameters.get("id"), on: database)
```
This method returns `nil` if no model with that identifier was found.
## Lifecycle
Model middleware allow you to hook into your model's lifecycle events. The following lifecycle events are supported.
|Method|Description|
|-|-|
|`create`|Runs before a model is created.|
|`update`|Runs before a model is updated.|
|`delete(force:)`|Runs before a model is deleted.|
|`softDelete`|Runs before a model is soft deleted.|
|`restore`|Runs before a model is restored (opposite of soft delete).|
Model middleware are declared using the `ModelMiddleware` or `AsyncModelMiddleware` protocol. All lifecycle methods have a default implementation, so you only need to implement the methods you require. Each method accepts the model in question, a reference to the database, and the next action in the chain. The middleware can choose to return early, return a failed future, or call the next action to continue normally.
Using these methods you can perform actions both before and after the specific event completes. Performing actions after the event completes can be done by mapping the future returned from the next responder.
```swift
// Example middleware that capitalizes names.
struct PlanetMiddleware: ModelMiddleware {
func create(model: Planet, on db: Database, next: AnyModelResponder) -> EventLoopFuture {
// The model can be altered here before it is created.
model.name = model.name.capitalized()
return next.create(model, on: db).map {
// Once the planet has been created, the code
// here will be executed.
print ("Planet \(model.name) was created")
}
}
}
```
or if using `async`/`await`:
```swift
struct PlanetMiddleware: AsyncModelMiddleware {
func create(model: Planet, on db: Database, next: AnyAsyncModelResponder) async throws {
// The model can be altered here before it is created.
model.name = model.name.capitalized()
try await next.create(model, on: db)
// Once the planet has been created, the code
// here will be executed.
print ("Planet \(model.name) was created")
}
}
```
Once you have created your middleware, you can enable it using `app.databases.middleware`.
```swift
// Example of configuring model middleware.
app.databases.middleware.use(PlanetMiddleware(), on: .psql)
```
## Database Space
Fluent supports the setting of a space for a Model, which allows the partitioning of individual Fluent models between PostgreSQL schemas, MySQL databases, and multiple attached SQLite databases. MongoDB does not support spaces at the time of this writing. To place a model in a space other than the default, add a new static property to the model:
```swift
public static let schema = "planets"
public static let space: String? = "mirror_universe"
// ...
```
Fluent will use this when building all database queries.
# Relations
Fluent's [model API](model.md) helps you create and maintain references between your models through relations. Three types of relations are supported:
- [Parent](#parent) / [Child](#optional-child) (One-to-one)
- [Parent](#parent) / [Children](#children) (One-to-many)
- [Siblings](#siblings) (Many-to-many)
## Parent
The `@Parent` relation stores a reference to another model's `@ID` property.
```swift
final class Planet: Model {
// Example of a parent relation.
@Parent(key: "star_id")
var star: Star
}
```
`@Parent` contains a `@Field` named `id` which is used for setting and updating the relation.
```swift
// Set parent relation id
earth.$star.id = sun.id
```
For instance, the `Planet` initializer would look like:
```swift
init(name: String, starID: Star.IDValue) {
self.name = name
// ...
self.$star.id = starID
}
```
The `key` parameter defines the field key to use for storing the parent's identifier. Assuming `Star` has a `UUID` identifier, this `@Parent` relation is compatible with the following [field definition](schema.md#field).
```swift
.field("star_id", .uuid, .required, .references("star", "id"))
```
Note that the [`.references`](schema.md#field-constraint) constraint is optional. See [schema](schema.md) for more information.
### Optional Parent
The `@OptionalParent` relation stores an optional reference to another model's `@ID` property. It works similarly to `@Parent` but allows for the relation to be `nil`.
```swift
final class Planet: Model {
// Example of an optional parent relation.
@OptionalParent(key: "star_id")
var star: Star?
}
```
The field definition is similar to `@Parent`'s except that the `.required` constraint should be omitted.
```swift
.field("star_id", .uuid, .references("star", "id"))
```
### Encoding and Decoding of Parents
One thing to watch out for when working with `@Parent` relations is the way that you send and receive them. For example, in JSON, a `@Parent` for a `Planet` model might look like this:
```json
{
"id": "A616B398-A963-4EC7-9D1D-B1AA8A6F1107",
"star": {
"id": "A1B2C3D4-1234-5678-90AB-CDEF12345678"
}
}
```
Note how the `star` property is an object rather than the ID that you might expect. When sending the model as an HTTP body, it needs to match this for decoding to work. For this reason, we strongly recommend using a DTO to represent the model when sending it over the network. For example:
```swift
struct PlanetDTO: Content {
var id: UUID?
var name: String
var star: Star.IDValue
}
```
Then you can decode the DTO and convert it into a model:
```swift
let planetData = try req.content.decode(PlanetDTO.self)
let planet = Planet(id: planetData.id, name: planetData.name, starID: planetData.star)
try await planet.create(on: req.db)
```
The same applies when returning the model to clients. Your clients either need to be able to handle the nested structure, or you need to convert the model into a DTO before returning it. For more information about DTOs, see the [Model documentation](model.md#data-transfer-object)
## Optional Child
The `@OptionalChild` property creates a one-to-one relation between the two models. It does not store any values on the root model.
```swift
final class Planet: Model {
// Example of an optional child relation.
@OptionalChild(for: \.$planet)
var governor: Governor?
}
```
The `for` parameter accepts a key path to a `@Parent` or `@OptionalParent` relation referencing the root model.
A new model can be added to this relation using the `create` method.
```swift
// Example of adding a new model to a relation.
let jane = Governor(name: "Jane Doe")
try await mars.$governor.create(jane, on: database)
```
This will set the parent id on the child model automatically.
Since this relation does not store any values, no database schema entry is required for the root model.
The one-to-one nature of the relation should be enforced in the child model's schema using a `.unique` constraint on the column referencing the parent model.
```swift
try await database.schema(Governor.schema)
.id()
.field("name", .string, .required)
.field("planet_id", .uuid, .required, .references("planets", "id"))
// Example of unique constraint
.unique(on: "planet_id")
.create()
```
!!! warning
Omitting the unique constraint on the parent ID field from the client's schema can lead to unpredictable results.
If there is no uniqueness constraint, the child table may wind up containing more than one child row for any given parent; in this case, an `@OptionalChild` property will still only be able to access one child at a time, with no way of controlling which child is loaded. If you may need to store multiple child rows for any given parent, use `@Children` instead.
## Children
The `@Children` property creates a one-to-many relation between two models. It does not store any values on the root model.
```swift
final class Star: Model {
// Example of a children relation.
@Children(for: \.$star)
var planets: [Planet]
}
```
The `for` parameter accepts a key path to a `@Parent` or `@OptionalParent` relation referencing the root model. In this case, we are referencing the `@Parent` relation from the previous [example](#parent).
New models can be added to this relation using the `create` method.
```swift
// Example of adding a new model to a relation.
let earth = Planet(name: "Earth")
try await sun.$planets.create(earth, on: database)
```
This will set the parent id on the child model automatically.
Since this relation does not store any values, no database schema entry is required.
## Siblings
The `@Siblings` property creates a many-to-many relation between two models. It does this through a tertiary model called a pivot.
Let's take a look at an example of a many-to-many relation between a `Planet` and a `Tag`.
```swift
enum PlanetTagStatus: String, Codable { case accepted, pending }
// Example of a pivot model.
final class PlanetTag: Model {
static let schema = "planet+tag"
@ID(key: .id)
var id: UUID?
@Parent(key: "planet_id")
var planet: Planet
@Parent(key: "tag_id")
var tag: Tag
@OptionalField(key: "comments")
var comments: String?
@OptionalEnum(key: "status")
var status: PlanetTagStatus?
init() { }
init(id: UUID? = nil, planet: Planet, tag: Tag, comments: String?, status: PlanetTagStatus?) throws {
self.id = id
self.$planet.id = try planet.requireID()
self.$tag.id = try tag.requireID()
self.comments = comments
self.status = status
}
}
```
Any model which includes at least two `@Parent` relations, one for each model to be related, can be used as a pivot. The model may contain additional properties, such as its ID, and may even contain other `@Parent` relations.
Adding a [unique](schema.md#unique) constraint to the pivot model can help prevent redundant entries. See [schema](schema.md) for more information.
```swift
// Disallows duplicate relations.
.unique(on: "planet_id", "tag_id")
```
Once the pivot is created, use the `@Siblings` property to create the relation.
```swift
final class Planet: Model {
// Example of a siblings relation.
@Siblings(through: PlanetTag.self, from: \.$planet, to: \.$tag)
public var tags: [Tag]
}
```
The `@Siblings` property requires three parameters:
- `through`: The pivot model's type.
- `from`: Key path from the pivot to the parent relation referencing the root model.
- `to`: Key path from the pivot to the parent relation referencing the related model.
The inverse `@Siblings` property on the related model completes the relation.
```swift
final class Tag: Model {
// Example of a siblings relation.
@Siblings(through: PlanetTag.self, from: \.$tag, to: \.$planet)
public var planets: [Planet]
}
```
### Siblings Attach
The `@Siblings` property has methods for adding and removing models from the relation.
Use the `attach()` method to add a single model or an array of models to the relation. Pivot models are created and saved automatically as needed. A callback closure may be specified to populate additional properties of each pivot created:
```swift
let earth: Planet = ...
let inhabited: Tag = ...
// Adds the model to the relation.
try await earth.$tags.attach(inhabited, on: database)
// Populate pivot attributes when establishing the relation.
try await earth.$tags.attach(inhabited, on: database) { pivot in
pivot.comments = "This is a life-bearing planet."
pivot.status = .accepted
}
// Add multiple models with attributes to the relation.
let volcanic: Tag = ..., oceanic: Tag = ...
try await earth.$tags.attach([volcanic, oceanic], on: database) { pivot in
pivot.comments = "This planet has a tag named \(pivot.$tag.name)."
pivot.status = .pending
}
```
When attaching a single model, you can use the `method` parameter to choose whether or not the relation should be checked before saving.
```swift
// Only attaches if the relation doesn't already exist.
try await earth.$tags.attach(inhabited, method: .ifNotExists, on: database)
```
Use the `detach` method to remove a model from the relation. This deletes the corresponding pivot model.
```swift
// Removes the model from the relation.
try await earth.$tags.detach(inhabited, on: database)
```
You can check if a model is related or not using the `isAttached` method.
```swift
// Checks if the models are related.
earth.$tags.isAttached(to: inhabited)
```
## Get
Use the `get(on:)` method to fetch a relation's value.
```swift
// Fetches all of the sun's planets.
sun.$planets.get(on: database).map { planets in
print(planets)
}
// Or
let planets = try await sun.$planets.get(on: database)
print(planets)
```
Use the `reload` parameter to choose whether or not the relation should be re-fetched from the database if it has already been already loaded.
```swift
try await sun.$planets.get(reload: true, on: database)
```
## Query
Use the `query(on:)` method on a relation to create a query builder for the related models.
```swift
// Fetch all of the sun's planets that have a naming starting with M.
try await sun.$planets.query(on: database).filter(\.$name =~ "M").all()
```
See [query](query.md) for more information.
## Eager Loading
Fluent's query builder allows you to preload a model's relations when it is fetched from the database. This is called eager loading and allows you to access relations synchronously without needing to call [`get`](#get) first.
To eager load a relation, pass a key path to the relation to the `with` method on query builder.
```swift
// Example of eager loading.
Planet.query(on: database).with(\.$star).all().map { planets in
for planet in planets {
// `star` is accessible synchronously here
// since it has been eager loaded.
print(planet.star.name)
}
}
// Or
let planets = try await Planet.query(on: database).with(\.$star).all()
for planet in planets {
// `star` is accessible synchronously here
// since it has been eager loaded.
print(planet.star.name)
}
```
In the above example, a key path to the [`@Parent`](#parent) relation named `star` is passed to `with`. This causes the query builder to do an additional query after all of the planets are loaded to fetch all of their related stars. The stars are then accessible synchronously via the `@Parent` property.
Each relation eager loaded requires only one additional query, no matter how many models are returned. Eager loading is only possible with the `all` and `first` methods of query builder.
### Nested Eager Load
The query builder's `with` method allows you to eager load relations on the model being queried. However, you can also eager load relations on related models.
```swift
let planets = try await Planet.query(on: database).with(\.$star) { star in
star.with(\.$galaxy)
}.all()
for planet in planets {
// `star.galaxy` is accessible synchronously here
// since it has been eager loaded.
print(planet.star.galaxy.name)
}
```
The `with` method accepts an optional closure as a second parameter. This closure accepts an eager load builder for the chosen relation. There is no limit to how deeply eager loading can be nested.
## Lazy Eager Loading
In case that you have already retrieved the parent model and you want to load one of it's relations, you can use the `get(reload:on:)` method for that purpose. This will fetch the related model from the database (or cache, if available) and allows it to be accessed as a local property.
```swift
planet.$star.get(on: database).map {
print(planet.star.name)
}
// Or
try await planet.$star.get(on: database)
print(planet.star.name)
```
In case you want to ensure that the data you receive is not pulled from cache, use the `reload:` parameter.
```swift
try await planet.$star.get(reload: true, on: database)
print(planet.star.name)
```
To check whether or not a relation has been loaded, use the `value` property.
```swift
if planet.$star.value != nil {
// Relation has been loaded.
print(planet.star.name)
} else {
// Relation has not been loaded.
// Attempting to access planet.star will fail.
}
```
If you already have the related model in a variable, you can set the relation manually using the `value` property mentioned above.
```swift
planet.$star.value = star
```
This will attach the related model to the parent as if it was eager loaded or lazy loaded without an extra database query.
# Migrations
Migrations are like a version control system for your database. Each migration defines a change to the database and how to undo it. By modifying your database through migrations, you create a consistent, testable, and shareable way to evolve your databases over time.
```swift
// An example migration.
struct MyMigration: Migration {
func prepare(on database: any Database) -> EventLoopFuture {
// Make a change to the database.
}
func revert(on database: any Database) -> EventLoopFuture {
// Undo the change made in `prepare`, if possible.
}
}
```
If you're using `async`/`await` you should implement the `AsyncMigration` protocol:
```swift
struct MyMigration: AsyncMigration {
func prepare(on database: any Database) async throws {
// Make a change to the database.
}
func revert(on database: any Database) async throws {
// Undo the change made in `prepare`, if possible.
}
}
```
The `prepare` method is where you make changes to the supplied `Database`. These could be changes to the database schema like adding or removing a table or collection, field, or constraint. They could also modify the database content, like creating new model instances, updating field values, or doing cleanup.
The `revert` method is where you undo these changes, if possible. Being able to undo migrations can make prototyping and testing easier. They also give you a backup plan if a deploy to production doesn't go as planned.
## Register
Migrations are registered to your application using `app.migrations`.
```swift
import Fluent
import Vapor
app.migrations.add(MyMigration())
```
You can add a migration to a specific database using the `to` parameter, otherwise the default database will be used.
```swift
app.migrations.add(MyMigration(), to: .myDatabase)
```
Migrations should be listed in order of dependency. For example, if `MigrationB` depends on `MigrationA`, it should be added to `app.migrations` second.
## Migrate
To migrate your database, run the `migrate` command.
```sh
swift run App migrate
```
You can also run this [command through Xcode](../advanced/commands.md#xcode). The migrate command will check the database to see if any new migrations have been registered since it was last run. If there are new migrations, it will ask for a confirmation before running them.
### Revert
To undo a migration on your database, run `migrate` with the `--revert` flag.
```sh
swift run App migrate --revert
```
The command will check the database to see which batch of migrations was last run and ask for a confirmation before reverting them.
### Auto Migrate
If you would like migrations to run automatically before running other commands, you can pass the `--auto-migrate` flag.
```sh
swift run App serve --auto-migrate
```
You can also do this programatically.
```swift
try app.autoMigrate().wait()
// or
try await app.autoMigrate()
```
Both of these options exist for reverting as well: `--auto-revert` and `app.autoRevert()`.
## Next Steps
Take a look at the [schema builder](schema.md) and [query builder](query.md) guides for more information about what to put inside your migrations.
# Query
Fluent's query API allows you to create, read, update, and delete models from the database. It supports filtering results, joins, chunking, aggregates, and more.
```swift
// An example of Fluent's query API.
let planets = try await Planet.query(on: database)
.filter(\.$type == .gasGiant)
.sort(\.$name)
.with(\.$star)
.all()
```
Query builders are tied to a single model type and can be created using the static [`query`](model.md#query) method. They can also be created by passing the model type to the `query` method on a database object.
```swift
// Also creates a query builder.
database.query(Planet.self)
```
!!! note
You must `import Fluent` in the file with your queries so that the compiler can see Fluent's helper functions.
## All
The `all()` method returns an array of models.
```swift
// Fetches all planets.
let planets = try await Planet.query(on: database).all()
```
The `all` method also supports fetching only a single field from the result set.
```swift
// Fetches all planet names.
let names = try await Planet.query(on: database).all(\.$name)
```
### First
The `first()` method returns a single, optional model. If the query results in more than one model, only the first is returned. If the query has no results, `nil` is returned.
```swift
// Fetches the first planet named Earth.
let earth = try await Planet.query(on: database)
.filter(\.$name == "Earth")
.first()
```
!!! tip
If using `EventLoopFuture`s, this method can be combined with [`unwrap(or:)`](../basics/errors.md#abort) to return a non-optional model or throw an error.
## Filter
The `filter` method allows you to constrain the models included in the result set. There are several overloads for this method.
### Value Filter
The most commonly used `filter` method accept an operator expression with a value.
```swift
// An example of field value filtering.
Planet.query(on: database).filter(\.$type == .gasGiant)
```
These operator expressions accept a field key path on the left hand side and a value on the right. The supplied value must match the field's expected value type and is bound to the resulting query. Filter expressions are strongly typed allowing for leading-dot syntax to be used.
Below is a list of all supported value operators.
|Operator|Description|
|-|-|
|`==`|Equal to.|
|`!=`|Not equal to.|
|`>=`|Greater than or equal to.|
|`>`|Greater than.|
|`<`|Less than.|
|`<=`|Less than or equal to.|
### Field Filter
The `filter` method supports comparing two fields.
```swift
// All users with same first and last name.
User.query(on: database)
.filter(\.$firstName == \.$lastName)
```
Field filters support the same operators as [value filters](#value-filter).
### Subset Filter
The `filter` method supports checking whether a field's value exists in a given set of values.
```swift
// All planets with either gas giant or small rocky type.
Planet.query(on: database)
.filter(\.$type ~~ [.gasGiant, .smallRocky])
```
The supplied set of values can be any Swift `Collection` whose `Element` type matches the field's value type.
Below is a list of all supported subset operators.
|Operator|Description|
|-|-|
|`~~`|Value in set.|
|`!~`|Value not in set.|
### Contains Filter
The `filter` method supports checking whether a string field's value contains a given substring.
```swift
// All planets whose name starts with the letter M
Planet.query(on: database)
.filter(\.$name =~ "M")
```
These operators are only available on fields with string values.
Below is a list of all supported contains operators.
|Operator|Description|
|-|-|
|`~~`|Contains substring.|
|`!~`|Does not contain substring.|
|`=~`|Matches prefix.|
|`!=~`|Does not match prefix.|
|`~=`|Matches suffix.|
|`!~=`|Does not match suffix.|
### Group
By default, all filters added to a query will be required to match. Query builder supports creating a group of filters where only one filter must match.
```swift
// All planets whose name is either Earth or Mars
Planet.query(on: database).group(.or) { group in
group.filter(\.$name == "Earth").filter(\.$name == "Mars")
}.all()
```
The `group` method supports combining filters by `and` or `or` logic. These groups can be nested indefinitely. Top-level filters can be thought of as being in an `and` group.
## Aggregate
Query builder supports several methods for performing calculations on a set of values like counting or averaging.
```swift
// Number of planets in database.
Planet.query(on: database).count()
```
All aggregate methods besides `count` require a key path to a field to be passed.
```swift
// Lowest name sorted alphabetically.
Planet.query(on: database).min(\.$name)
```
Below is a list of all available aggregate methods.
|Aggregate|Description|
|-|-|
|`count`|Number of results.|
|`sum`|Sum of result values.|
|`average`|Average of result values.|
|`min`|Minimum result value.|
|`max`|Maximum result value.|
All aggregate methods except `count` return the field's value type as a result. `count` always returns an integer.
## Chunk
Query builder supports returning a result set as separate chunks. This helps you to control memory usage when handling large database reads.
```swift
// Fetches all planets in chunks of at most 64 at a time.
Planet.query(on: self.database).chunk(max: 64) { planets in
// Handle chunk of planets.
}
```
The supplied closure will be called zero or more times depending on the total number of results. Each item returned is a `Result` containing either the model or an error returned attempting to decode the database entry.
## Field
By default, all of a model's fields will be read from the database by a query. You can choose to select only a subset of a model's fields using the `field` method.
```swift
// Select only the planet's id and name field
Planet.query(on: database)
.field(\.$id).field(\.$name)
.all()
```
Any model fields not selected during a query will be in an unitialized state. Attempting to access uninitialized fields directly will result in a fatal error. To check if a model's field value is set, use the `value` property.
```swift
if let name = planet.$name.value {
// Name was fetched.
} else {
// Name was not fetched.
// Accessing `planet.name` will fail.
}
```
## Unique
Query builder's `unique` method causes only distinct results (no duplicates) to be returned.
```swift
// Returns all unique user first names.
User.query(on: database).unique().all(\.$firstName)
```
`unique` is especially useful when fetching a single field with `all`. However, you can also select multiple fields using the [`field`](#field) method. Since model identifiers are always unique, you should avoid selecting them when using `unique`.
## Range
Query builder's `range` methods allow you to choose a subset of the results using Swift ranges.
```swift
// Fetch the first 5 planets.
Planet.query(on: self.database)
.range(..<5)
```
Range values are unsigned integers starting at zero. Learn more about [Swift ranges](https://developer.apple.com/documentation/swift/range).
```swift
// Skip the first 2 results.
.range(2...)
```
## Join
Query builder's `join` method allows you to include another model's fields in your result set. More than one model can be joined to your query.
```swift
// Fetches all planets with a star named Sun.
Planet.query(on: database)
.join(Star.self, on: \Planet.$star.$id == \Star.$id)
.filter(Star.self, \.$name == "Sun")
.all()
```
The `on` parameter accepts an equality expression between two fields. One of the fields must already exist in the current result set. The other field must exist on the model being joined. These fields must have the same value type.
Most query builder methods, like `filter` and `sort`, support joined models. If a method supports joined models, it will accept the joined model type as the first parameter.
```swift
// Sort by joined field "name" on Star model.
.sort(Star.self, \.$name)
```
Queries that use joins will still return an array of the base model. To access the joined model, use the `joined` method.
```swift
// Accessing joined model from query result.
let planet: Planet = ...
let star = try planet.joined(Star.self)
```
### Model Alias
Model aliases allow you to join the same model to a query multiple times. To declare a model alias, create one or more types conforming to `ModelAlias`.
```swift
// Example of model aliases.
final class HomeTeam: ModelAlias {
static let name = "home_teams"
let model = Team()
}
final class AwayTeam: ModelAlias {
static let name = "away_teams"
let model = Team()
}
```
These types reference the model being aliased via the `model` property. Once created, you can use model aliases like normal models in a query builder.
```swift
// Fetch all matches where the home team's name is Vapor
// and sort by the away team's name.
let matches = try await Match.query(on: self.database)
.join(HomeTeam.self, on: \Match.$homeTeam.$id == \HomeTeam.$id)
.join(AwayTeam.self, on: \Match.$awayTeam.$id == \AwayTeam.$id)
.filter(HomeTeam.self, \.$name == "Vapor")
.sort(AwayTeam.self, \.$name)
.all()
```
All model fields are accessible through the model alias type via `@dynamicMemberLookup`.
```swift
// Access joined model from result.
let home = try match.joined(HomeTeam.self)
print(home.name)
```
## Update
Query builder supports updating more than one model at a time using the `update` method.
```swift
// Update all planets named "Pluto"
Planet.query(on: database)
.set(\.$type, to: .dwarf)
.filter(\.$name == "Pluto")
.update()
```
`update` supports the `set`, `filter`, and `range` methods.
## Delete
Query builder supports deleting more than one model at a time using the `delete` method.
```swift
// Delete all planets named "Vulcan"
Planet.query(on: database)
.filter(\.$name == "Vulcan")
.delete()
```
`delete` supports the `filter` method.
## Paginate
Fluent's query API supports automatic result pagination using the `paginate` method.
```swift
// Example of request-based pagination.
app.get("planets") { req in
try await Planet.query(on: req.db).paginate(for: req)
}
```
The `paginate(for:)` method will use the `page` and `per` parameters available in the request URI to return the desired set of results. Metadata about current page and total number of results is included in the `metadata` key.
```http
GET /planets?page=2&per=5 HTTP/1.1
```
The above request would yield a response structured like the following.
```json
{
"items": [...],
"metadata": {
"page": 2,
"per": 5,
"total": 8
}
}
```
Page numbers start at `1`. You can also make a manual page request.
```swift
// Example of manual pagination.
.paginate(PageRequest(page: 1, per: 2))
```
## Sort
Query results can be sorted by field values using `sort` method.
```swift
// Fetch planets sorted by name.
Planet.query(on: database).sort(\.$name)
```
Additional sorts may be added as fallbacks in case of a tie. Fallbacks will be used in the order they were added to the query builder.
```swift
// Fetch users sorted by name. If two users have the same name, sort them by age.
User.query(on: database).sort(\.$name).sort(\.$age)
```
# Transactions
Transactions allow you to ensure multiple operations complete successfully before saving data to your database.
Once a transaction is started, you may run Fluent queries normally. However, no data will be saved to the database until the transaction completes.
If an error is thrown at any point during the transaction (by you or the database), none of the changes will take effect.
To perform a transaction, you need access to something that can connect to the database. This is usually an incoming HTTP request. For this, use `req.db.transaction(_ :)`:
```swift
req.db.transaction { database in
// use database
}
```
Once inside the transaction closure, you must use the database supplied in the closure parameter (named `database` in the example) to perform queries.
Once this closure returns successfully, the transaction will be committed.
```swift
var sun: Star = ...
var sirius: Star = ...
return req.db.transaction { database in
return sun.save(on: database).flatMap { _ in
return sirius.save(on: database)
}
}
```
The above example will save `sun` and *then* `sirius` before completing the transaction. If either star fails to save, neither will save.
Once the transaction completes, the result can be transformed into a different future, for example into a HTTP status to indicate completion as shown below:
```swift
return req.db.transaction { database in
// use database and perform transaction
}.transform(to: HTTPStatus.ok)
```
## `async`/`await`
If using `async`/`await` you can refactor the code to the following:
```swift
try await req.db.transaction { transaction in
try await sun.save(on: transaction)
try await sirius.save(on: transaction)
}
return .ok
```
# Schema
Fluent's schema API allows you to create and update your database schema programatically. It is often used in conjunction with [migrations](migration.md) to prepare the database for use with [models](model.md).
```swift
// An example of Fluent's schema API
try await database.schema("planets")
.id()
.field("name", .string, .required)
.field("star_id", .uuid, .required, .references("stars", "id"))
.create()
```
To create a `SchemaBuilder`, use the `schema` method on database. Pass in the name of the table or collection you want to affect. If you are editing the schema for a model, make sure this name matches the model's [`schema`](model.md#schema).
## Actions
The schema API supports creating, updating, and deleting schemas. Each action supports a subset of the API's available methods.
### Create
Calling `create()` creates a new table or collection in the database. All methods for defining new fields and constraints are supported. Methods for updates or deletes are ignored.
```swift
// An example schema creation.
try await database.schema("planets")
.id()
.field("name", .string, .required)
.create()
```
If a table or collection with the chosen name already exists, an error will be thrown. To ignore this, use `.ignoreExisting()`.
### Update
Calling `update()` updates an existing table or collection in the database. All methods for creating, updating, and deleting fields and constraints are supported.
```swift
// An example schema update.
try await database.schema("planets")
.unique(on: "name")
.deleteField("star_id")
.update()
```
### Delete
Calling `delete()` deletes an existing table or collection from the database. No additional methods are supported.
```swift
// An example schema deletion.
database.schema("planets").delete()
```
## Field
Fields can be added when creating or updating a schema.
```swift
// Adds a new field
.field("name", .string, .required)
```
The first parameter is the name of the field. This should match the key used on the associated model property. The second parameter is the field's [data type](#data-type). Finally, zero or more [constraints](#field-constraint) can be added.
### Data Type
Supported field data types are listed below.
|DataType|Swift Type|
|-|-|
|`.string`|`String`|
|`.int{8,16,32,64}`|`Int{8,16,32,64}`|
|`.uint{8,16,32,64}`|`UInt{8,16,32,64}`|
|`.bool`|`Bool`|
|`.datetime`|`Date` (recommended)|
|`.date`|`Date` (omitting time of day)|
|`.float`|`Float`|
|`.double`|`Double`|
|`.data`|`Data`|
|`.uuid`|`UUID`|
|`.dictionary`|See [dictionary](#dictionary)|
|`.array`|See [array](#array)|
|`.enum`|See [enum](#enum)|
### Field Constraint
Supported field constraints are listed below.
|FieldConstraint|Description|
|-|-|
|`.required`|Disallows `nil` values.|
|`.references`|Requires that this field's value match a value in the referenced schema. See [foreign key](#foreign-key).|
|`.identifier`|Denotes the primary key. See [identifier](#identifier).|
|`.sql(SQLColumnConstraintAlgorithm)`|Defines any constraint that is not supported (e.g. `default`). See [SQL](#sql) and [SQLColumnConstraintAlgorithm](https://api.vapor.codes/sqlkit/sqlcolumnconstraintalgorithm/).|
### Identifier
If your model uses a standard `@ID` property, you can use the `id()` helper to create its field. This uses the special `.id` field key and `UUID` value type.
```swift
// Adds field for default identifier.
.id()
```
For custom identifier types, you will need to specify the field manually.
```swift
// Adds field for custom identifier.
.field("id", .int, .identifier(auto: true))
```
The `identifier` constraint may be used on a single field and denotes the primary key. The `auto` flag determines whether or not the database should generate this value automatically.
### Update Field
You can update a field's data type using `updateField`.
```swift
// Updates the field to `double` data type.
.updateField("age", .double)
```
See [advanced](advanced.md#sql) for more information on advanced schema updates.
### Delete Field
You can remove a field from a schema using `deleteField`.
```swift
// Deletes the field "age".
.deleteField("age")
```
## Constraint
Constraints can be added when creating or updating a schema. Unlike [field constraints](#field-constraint), top-level constraints can affect multiple fields.
### Unique
A unique constraint requires that there are no duplicate values in one or more fields.
```swift
// Disallow duplicate email addresses.
.unique(on: "email")
```
If multiple field are constrained, the specific combination of each field's value must be unique.
```swift
// Disallow users with the same full name.
.unique(on: "first_name", "last_name")
```
To delete a unique constraint, use `deleteUnique`.
```swift
// Removes duplicate email constraint.
.deleteUnique(on: "email")
```
### Constraint Name
Fluent will generate unique constraint names by default. However, you may want to pass a custom constraint name. You can do this using the `name` parameter.
```swift
// Disallow duplicate email addresses.
.unique(on: "email", name: "no_duplicate_emails")
```
To delete a named constraint, you must use `deleteConstraint(name:)`.
```swift
// Removes duplicate email constraint.
.deleteConstraint(name: "no_duplicate_emails")
```
## Foreign Key
Foreign key constraints require that a field's value match ones of the values in the referenced field. This is useful for preventing invalid data from being saved. Foreign key constraints can be added as either a field or top-level constraint.
To add a foreign key constraint to a field, use `.references`.
```swift
// Example of adding a field foreign key constraint.
.field("star_id", .uuid, .required, .references("stars", "id"))
```
The above constraint requires that all values in the "star_id" field must match one of the values in Star's "id" field.
This same constraint could be added as a top-level constraint using `foreignKey`.
```swift
// Example of adding a top-level foreign key constraint.
.foreignKey("star_id", references: "stars", "id")
```
Unlike field constraints, top-level constraints can be added in a schema update. They can also be [named](#constraint-name).
Foreign key constraints support optional `onDelete` and `onUpdate` actions.
|ForeignKeyAction|Description|
|-|-|
|`.noAction`|Prevents foreign key violations (default).|
|`.restrict`|Same as `.noAction`.|
|`.cascade`|Propagates deletes through foreign keys.|
|`.setNull`|Sets field to null if reference is broken.|
|`.setDefault`|Sets field to default if reference is broken.|
Below is an example using foreign key actions.
```swift
// Example of adding a top-level foreign key constraint.
.foreignKey("star_id", references: "stars", "id", onDelete: .cascade)
```
!!! warning
Foreign key actions happen solely in the database, bypassing Fluent.
This means things like model middleware and soft-delete may not work correctly.
## SQL
The `.sql` parameter allows you to add arbitrary SQL to your schema. This is useful for adding specific constraints or data types.
A common use case is defining a default value for a field:
```swift
.field("active", .bool, .required, .sql(.default(true)))
```
or even a default value for a timestamp:
```swift
.field("created_at", .datetime, .required, .sql(.default(SQLFunction("now"))))
```
## Dictionary
The dictionary data type is capable of storing nested dictionary values. This includes structs that conform to `Codable` and Swift dictionaries with a `Codable` value.
!!! note
Fluent's SQL database drivers store nested dictionaries in JSON columns.
Take the following `Codable` struct.
```swift
struct Pet: Codable {
var name: String
var age: Int
}
```
Since this `Pet` struct is `Codable`, it can be stored in a `@Field`.
```swift
@Field(key: "pet")
var pet: Pet
```
This field can be stored using the `.dictionary(of:)` data type.
```swift
.field("pet", .dictionary, .required)
```
Since `Codable` types are heterogenous dictionaries, we do not specify the `of` parameter.
If the dictionary values were homogenous, for example `[String: Int]`, the `of` parameter would specify the value type.
```swift
.field("numbers", .dictionary(of: .int), .required)
```
Dictionary keys must always be strings.
## Array
The array data type is capable of storing nested arrays. This includes Swift arrays that contain `Codable` values and `Codable` types that use an unkeyed container.
Take the following `@Field` that stores an array of strings.
```swift
@Field(key: "tags")
var tags: [String]
```
This field can be stored using the `.array(of:)` data type.
```swift
.field("tags", .array(of: .string), .required)
```
Since the array is homogenous, we specify the `of` parameter.
Codable Swift `Array`s will always have a homogenous value type. Custom `Codable` types that serialize heterogenous values to unkeyed containers are the exception and should use the `.array` data type.
## Enum
The enum data type is capable of storing string backed Swift enums natively. Native database enums provide an added layer of type safety to your database and may be more performant than raw enums.
To define a native database enum, use the `enum` method on `Database`. Use `case` to define each case of the enum.
```swift
// An example of enum creation.
database.enum("planet_type")
.case("smallRocky")
.case("gasGiant")
.case("dwarf")
.create()
```
Once an enum has been created, you can use the `read()` method to generate a data type for your schema field.
```swift
// An example of reading an enum and using it to define a new field.
database.enum("planet_type").read().flatMap { planetType in
database.schema("planets")
.field("type", planetType, .required)
.update()
}
// Or
let planetType = try await database.enum("planet_type").read()
try await database.schema("planets")
.field("type", planetType, .required)
.update()
```
To update an enum, call `update()`. Cases can be deleted from existing enums.
```swift
// An example of enum update.
database.enum("planet_type")
.deleteCase("gasGiant")
.update()
```
To delete an enum, call `delete()`.
```swift
// An example of enum deletion.
database.enum("planet_type").delete()
```
## Model Coupling
Schema building is purposefully decoupled from models. Unlike query building, schema building does not make use of key paths and is completely stringly typed. This is important since schema definitions, especially those written for migrations, may need to reference model properties that no longer exist.
To better understand this, take a look at the following example migration.
```swift
struct UserMigration: AsyncMigration {
func prepare(on database: Database) async throws {
try await database.schema("users")
.field("id", .uuid, .identifier(auto: false))
.field("name", .string, .required)
.create()
}
func revert(on database: Database) async throws {
try await database.schema("users").delete()
}
}
```
Let's assume that this migration has been has already been pushed to production. Now let's assume we need to make the following change to the User model.
```diff
- @Field(key: "name")
- var name: String
+ @Field(key: "first_name")
+ var firstName: String
+
+ @Field(key: "last_name")
+ var lastName: String
```
We can make the necessary database schema adjustments with the following migration.
```swift
struct UserNameMigration: AsyncMigration {
func prepare(on database: Database) async throws {
try await database.schema("users")
.field("first_name", .string, .required)
.field("last_name", .string, .required)
.update()
// It is not currently possible to express this update without using custom SQL.
// This also doesn't try to deal with splitting the name into first and last,
// as that requires database-specific syntax.
try await User.query(on: database)
.set(["first_name": .sql(embed: "name")])
.run()
try await database.schema("users")
.deleteField("name")
.update()
}
func revert(on database: Database) async throws {
try await database.schema("users")
.field("name", .string, .required)
.update()
try await User.query(on: database)
.set(["name": .sql(embed: "concat(first_name, ' ', last_name)")])
.run()
try await database.schema("users")
.deleteField("first_name")
.deleteField("last_name")
.update()
}
}
```
Note that for this migration to work, we need to be able to reference both the removed `name` field and the new `firstName` and `lastName` fields at the same time. Furthermore, the original `UserMigration` should continue to be valid. This would not be possible to do with key paths.
## Setting Model Space
To define the [space for a model](model.md#database-space), pass the space to the `schema(_:space:)` when creating the table. E.g.
```swift
try await db.schema("planets", space: "mirror_universe")
.id()
// ...
.create()
```
# Advanced
Fluent strives to create a general, database-agnostic API for working with your data. This makes it easier to learn Fluent regardless of which database driver you are using. Creating generalized APIs can also make working with your database feel more at home in Swift.
However, you may need to use a feature of your underlying database driver that is not yet supported through Fluent. This guide covers advanced patterns and APIs in Fluent that only work with certain databases.
## SQL
All of Fluent's SQL database drivers are built on [SQLKit](https://github.com/vapor/sql-kit). This general SQL implementation is shipped with Fluent in the `FluentSQL` module.
### SQL Database
Any Fluent `Database` can be cast to a `SQLDatabase`. This includes `req.db`, `app.db`, the `database` passed to `Migration`, etc.
```swift
import FluentSQL
if let sql = req.db as? SQLDatabase {
// The underlying database driver is SQL.
let planets = try await sql.raw("SELECT * FROM planets").all(decoding: Planet.self)
} else {
// The underlying database driver is _not_ SQL.
}
```
This cast will only work if the underlying database driver is a SQL database. Learn more about `SQLDatabase`'s methods in [SQLKit's README](https://github.com/vapor/sql-kit).
### Specific SQL Database
You can also cast to specific SQL databases by importing the driver.
```swift
import FluentPostgresDriver
if let postgres = req.db as? PostgresDatabase {
// The underlying database driver is PostgreSQL.
postgres.simpleQuery("SELECT * FROM planets").all()
} else {
// The underlying database is _not_ PostgreSQL.
}
```
At the time of writing, the following SQL drivers are supported.
|Database|Driver|Library|
|-|-|-|
|`PostgresDatabase`|[vapor/fluent-postgres-driver](https://github.com/vapor/fluent-postgres-driver)|[vapor/postgres-nio](https://github.com/vapor/postgres-nio)|
|`MySQLDatabase`|[vapor/fluent-mysql-driver](https://github.com/vapor/fluent-mysql-driver)|[vapor/mysql-nio](https://github.com/vapor/mysql-nio)|
|`SQLiteDatabase`|[vapor/fluent-sqlite-driver](https://github.com/vapor/fluent-sqlite-driver)|[vapor/sqlite-nio](https://github.com/vapor/sqlite-nio)|
Visit the library's README for more information on the database-specific APIs.
### SQL Custom
Almost all of Fluent's query and schema types support a `.custom` case. This lets you utilize database features that Fluent doesn't support yet.
```swift
import FluentPostgresDriver
let query = Planet.query(on: req.db)
if req.db is PostgresDatabase {
// ILIKE supported.
query.filter(\.$name, .custom("ILIKE"), "earth")
} else {
// ILIKE not supported.
query.group(.or) { or in
or.filter(\.$name == "earth").filter(\.$name == "Earth")
}
}
query.all()
```
SQL databases support both `String` and `SQLExpression` in all `.custom` cases. The `FluentSQL` module provides convenience methods for common use cases.
```swift
import FluentSQL
let query = Planet.query(on: req.db)
if req.db is SQLDatabase {
// The underlying database driver is SQL.
query.filter(.sql(raw: "LOWER(name) = 'earth'"))
} else {
// The underlying database driver is _not_ SQL.
}
```
Below is an example of `.custom` via the `.sql(raw:)` convenience being used with the schema builder.
```swift
import FluentSQL
let builder = database.schema("planets").id()
if database is MySQLDatabase {
// The underlying database driver is MySQL.
builder.field("name", .sql(raw: "VARCHAR(64)"), .required)
} else {
// The underlying database driver is _not_ MySQL.
builder.field("name", .string, .required)
}
builder.create()
```
## MongoDB
Fluent MongoDB is an integration between [Fluent](../fluent/overview.md) and the [MongoKitten](https://github.com/OpenKitten/MongoKitten/) driver. It leverages Swift's strong type system and Fluent's database agnostic interface using MongoDB.
The most common identifier in MongoDB is ObjectId. You can use this for your project using `@ID(custom: .id)`.
If you need to use the same models with SQL, do not use `ObjectId`. Use `UUID` instead.
```swift
final class User: Model {
// Name of the table or collection.
static let schema = "users"
// Unique identifier for this User.
// In this case, ObjectId is used
// Fluent recommends using UUID by default, however ObjectId is also supported
@ID(custom: .id)
var id: ObjectId?
// The User's email address
@Field(key: "email")
var email: String
// The User's password stores as a BCrypt hash
@Field(key: "password")
var passwordHash: String
// Creates a new, empty User instance, for use by Fluent
init() { }
// Creates a new User with all properties set.
init(id: ObjectId? = nil, email: String, passwordHash: String, profile: Profile) {
self.id = id
self.email = email
self.passwordHash = passwordHash
self.profile = profile
}
}
```
### Data Modelling
In MongoDB, Models are defined in the same as in any other Fluent environment. The main difference between SQL databases and MongoDB lies in relationships and architecture.
In SQL environments, it's very common to create join tables for relationships between two entities. In MongoDB, however, an array can be used to store related identifiers. Due to the design of MongoDB, it's more efficient and practical to design your models with nested data structures.
### Flexible Data
You can add flexible data in MongoDB, but this code will not work in SQL environments.
To create grouped arbitrary data storage you can use `Document`.
```swift
@Field(key: "document")
var document: Document
```
Fluent cannot support strictly types queries on these values. You can use a dot notated key path in your query for querying.
This is accepted in MongoDB to access nested values.
```swift
Something.query(on: db).filter("document.key", .equal, 5).first()
```
### Use of regular expressions
You can query MongoDB using the `.custom()` case, and passing a regular expression. [MongoDB](https://www.mongodb.com/docs/manual/reference/operator/query/regex/) accepts Perl compatible regular expressions.
For example, you can query for case insensitive characters under the field `name`:
```swift
import FluentMongoDriver
var queryDocument = Document()
queryDocument["name"]["$regex"] = "e"
queryDocument["name"]["$options"] = "i"
let planets = try Planet.query(on: req.db).filter(.custom(queryDocument)).all()
```
This will return planets containing 'e' and 'E'. You can also create any other complex RegEx accepted by MongoDB.
### Raw Access
To access the raw `MongoDatabase` instance, cast the database instance to `MongoDatabaseRepresentable` as such:
```swift
guard let db = req.db as? MongoDatabaseRepresentable else {
throw Abort(.internalServerError)
}
let mongodb = db.raw
```
From here you can use all of the MongoKitten APIs.
# Leaf
Leaf is a powerful templating language with Swift-inspired syntax. You can use it to generate dynamic HTML pages for a front-end website or generate rich emails to send from an API.
## Package
The first step to using Leaf is adding it as a dependency to your project in your SPM package manifest file.
```swift
// swift-tools-version:5.8
import PackageDescription
let package = Package(
name: "MyApp",
platforms: [
.macOS(.v10_15)
],
dependencies: [
/// Any other dependencies ...
.package(url: "https://github.com/vapor/leaf.git", from: "4.4.0"),
],
targets: [
.target(name: "App", dependencies: [
.product(name: "Leaf", package: "leaf"),
// Any other dependencies
]),
// Other targets
]
)
```
## Configure
Once you have added the package to your project, you can configure Vapor to use it. This is usually done in [`configure.swift`](../getting-started/folder-structure.md#configureswift).
```swift
import Leaf
app.views.use(.leaf)
```
This tells Vapor to use the `LeafRenderer` when you call `req.view` in your code.
!!! warning
For Leaf to be able to find the templates when running from Xcode, you must set the [custom working directory](../getting-started/xcode.md#custom-working-directory) for you Xcode workspace.
### Cache for Rendering Pages
Leaf has an internal cache for rendering pages. When the `Application`'s environment is set to `.development`, this cache is disabled, so that changes to templates take effect immediately. In `.production` and all other environments, the cache is enabled by default. Any changes made to templates will not take effect until the application is restarted.
To disable Leaf's cache do the following:
```swift
app.leaf.cache.isEnabled = false
```
!!! warning
While disabling cache is helpful for debugging, it's not recommended for production environments as it can significantly impact performance due to the need to recompile templates on every request.
## Folder Structure
Once you have configured Leaf, you will need to ensure you have a `Views` folder to store your `.leaf` files in. By default, Leaf expects the views folder to be a `./Resources/Views` relative to your project's root.
You will also likely want to enable Vapor's [`FileMiddleware`](https://api.vapor.codes/vapor/filemiddleware) to serve files from your `/Public` folder if you plan on serving Javascript and CSS files for instance.
```
VaporApp
├── Package.swift
├── Resources
│ ├── Views
│ │ └── hello.leaf
├── Public
│ ├── images (images resources)
│ ├── styles (css resources)
└── Sources
└── ...
```
## Rendering a View
Now that Leaf is configured, let's render your first template. Inside of the `Resources/Views` folder, create a new file called `hello.leaf` with the following contents:
```leaf
Hello, #(name)!
```
!!! tip
If you're using VSCode as your code editor, we recommend installing the Vapor extension to enable syntax highlighting: [Vapor for VS Code](https://marketplace.visualstudio.com/items?itemName=Vapor.vapor-vscode).
Then, register a route (usually done in `routes.swift` or a controller) to render the view.
```swift
app.get("hello") { req -> EventLoopFuture in
return req.view.render("hello", ["name": "Leaf"])
}
// or
app.get("hello") { req async throws -> View in
return try await req.view.render("hello", ["name": "Leaf"])
}
```
This uses the generic `view` property on `Request` instead of calling Leaf directly. This allows you to switch to a different renderer in your tests.
Open your browser and visit `/hello`. You should see `Hello, Leaf!`. Congratulations on rendering your first Leaf view!
# Leaf Overview
Leaf is a powerful templating language with Swift-inspired syntax. You can use it to generate dynamic HTML pages for a front-end website or generate rich emails to send from an API.
This guide will give you an overview of Leaf's syntax and the available tags.
## Template syntax
Here is an example of a basic Leaf tag usage.
```leaf
There are #count(users) users.
```
Leaf tags are made up of four elements:
- Token `#`: This signals the Leaf parser to begin looking for a tag.
- Name `count`: that identifies the tag.
- Parameter List `(users)`: May accept zero or more arguments.
- Body: An optional body can be supplied to some tags using a colon and a closing tag
There can be many different usages of these four elements depending on the tag's implementation. Let's look at a few examples of how Leaf's built-in tags might be used:
```leaf
#(variable)
#extend("template"): I'm added to a base template! #endextend
#export("title"): Welcome to Vapor #endexport
#import("body")
#count(friends)
#for(friend in friends): #(friend.name) #endfor
```
Leaf also supports many expressions you are familiar with in Swift.
- `+`
- `%`
- `>`
- `==`
- `||`
- etc.
```leaf
#if(1 + 1 == 2):
Hello!
#endif
#if(index % 2 == 0):
This is even index.
#else:
This is odd index.
#endif
```
## Context
In the example from [Getting Started](getting-started.md), we used a `[String: String]` dictionary to pass data to Leaf. However, you can pass anything that conforms to `Encodable`. It's actually preferred to use `Encodable` structs since `[String: Any]` is not supported. This means you *can not* pass in an array, and should instead wrap it in a struct:
```swift
struct WelcomeContext: Encodable {
var title: String
var numbers: [Int]
}
return req.view.render("home", WelcomeContext(title: "Hello!", numbers: [42, 9001]))
```
That will expose `title` and `numbers` to our Leaf template, which can then be used inside tags. For example:
```leaf
#(title)
#for(number in numbers):
#(number)
#endfor
```
## Usage
Here are some common Leaf usage examples.
### Conditions
Leaf is able to evaluate a range of conditions using its `#if` tag. For example, if you provide a variable it will check that variable exists in its context:
```leaf
#if(title):
The title is #(title)
#else:
No title was provided.
#endif
```
You can also write comparisons, for example:
```leaf
#if(title == "Welcome"):
This is a friendly web page.
#else:
No strangers allowed!
#endif
```
If you want to use another tag as part of your condition, you should omit the `#` for the inner tag. For example:
```leaf
#if(count(users) > 0):
You have users!
#else:
There are no users yet :(
#endif
```
You can also use `#elseif` statements:
```leaf
#if(title == "Welcome"):
Hello new user!
#elseif(title == "Welcome back!"):
Hello old user
#else:
Unexpected page!
#endif
```
### Loops
If you provide an array of items, Leaf can loop over them and let you manipulate each item individually using its `#for` tag.
For example, we could update our Swift code to provide a list of planets:
```swift
struct SolarSystem: Codable {
let planets = ["Venus", "Earth", "Mars"]
}
return req.view.render("solarSystem", SolarSystem())
```
We could then loop over them in Leaf like this:
```leaf
Planets:
#for(planet in planets):
- #(planet)
#endfor
```
This would render a view that looks like:
```
Planets:
- Venus
- Earth
- Mars
```
Leaf also offers an index-entry option for iteration which allows you to access the index in the loop:
```leaf
Planets:
#for(index, planet in planets):
- #(index + 1) #(planet)
#endfor
```
This would result in:
```
Planets:
- 1 Venus
- 2 Earth
- 3 Mars
```
### Extending templates
Leaf’s `#extend` tag allows you to copy the contents of one template into another. When using this, you should always omit the template file's .leaf extension.
Extending is useful for copying in a standard piece of content, for example a page footer, advert code or table that's shared across multiple pages:
```leaf
#extend("footer")
```
This tag is also useful for building one template on top of another. For example, you might have a layout.leaf file that includes all the code required to lay out your website – HTML structure, CSS and JavaScript – with some gaps in place that represent where page content varies.
Using this approach, you would construct a child template that fills in its unique content, then extends the parent template that places the content appropriately. To do this, you can use the `#export` and `#import` tags to store and later retrieve content from the context.
For example, you might create a `child.leaf` template like this:
```leaf
#extend("main"):
#export("body"):
Welcome to Vapor!
#endexport
#endextend
```
We call `#export` to store some HTML and make it available to the template we're currently extending. We then render `main.leaf` and use the exported data when required along with any other context variables passed in from Swift. For example, `main.leaf` might look like this:
```leaf
#(title)
#import("body")
```
Here we are using `#import` to fetch the content passed to the `#extend` tag. When passed `["title": "Hi there!"]` from Swift, `child.leaf` will render as follows:
```html
Hi there!
Welcome to Vapor!
```
### Other tags
#### `#count`
The `#count` tag returns the number of items in an array. For example:
```leaf
Your search matched #count(matches) pages.
```
#### `#lowercased`
The `#lowercased` tag lowercases all letters in a string.
```leaf
#lowercased(name)
```
#### `#uppercased`
The `#uppercased` tag uppercases all letters in a string.
```leaf
#uppercased(name)
```
#### `#capitalized`
The `#capitalized` tag uppercases the first letter in each word of a string and lowercases the others. See [`String.capitalized`](https://developer.apple.com/documentation/foundation/nsstring/1416784-capitalized) for more information.
```leaf
#capitalized(name)
```
#### `#contains`
The `#contains` tag accepts an array and a value as its two parameters, and returns true if the array in parameter one contains the value in parameter two.
```leaf
#if(contains(planets, "Earth")):
Earth is here!
#else:
Earth is not in this array.
#endif
```
#### `#date`
The `#date` tag formats dates into a readable string. By default it uses ISO8601 formatting.
```swift
render(..., ["now": Date()])
```
```leaf
The time is #date(now)
```
You can pass a custom date formatter string as the second argument. See Swift's [`DateFormatter`](https://developer.apple.com/documentation/foundation/dateformatter) for more information.
```leaf
The date is #date(now, "yyyy-MM-dd")
```
You can also pass a time zone ID for the date formatter as the third argument. See Swift's [`DateFormatter.timeZone`](https://developer.apple.com/documentation/foundation/dateformatter/1411406-timezone) and [`TimeZone`](https://developer.apple.com/documentation/foundation/timezone) for more information.
```leaf
The date is #date(now, "yyyy-MM-dd", "America/New_York")
```
#### `#unsafeHTML`
The `#unsafeHTML` tag acts like a variable tag - e.g. `#(variable)`. However it does not escape any HTML that `variable` may contain:
```leaf
The time is #unsafeHTML(styledTitle)
```
!!! note
You should be careful when using this tag to ensure that the variable you provide it does not expose your users to an XSS attack.
#### `#comment`
The `#comment` tag allows you to add annotations to your templates that won't appear in the rendered output. The tag accepts a string parameter that is completely ignored during rendering.
```leaf
#comment("This is a single-line comment")
#(title)
```
For longer comments, you can use multi-line string syntax:
```leaf
#comment("""
This template renders the home page.
It expects a "title" and "body" variable.
""")
#(title)
```
#### `#isEmpty`
The `#isEmpty` tag returns true if a string property passed to the template is empty. It is typically used inside an `#if` condition:
```leaf
#if(isEmpty(title)):
No title was provided.
#else:
The title is #(title)
#endif
```
#### `#dumpContext`
The `#dumpContext` tag renders the whole context to a human readable string. Use this tag to debug what is being
provided as context to the current rendering.
```leaf
Hello, world!
#dumpContext
```
# Custom Tags
You can create custom Leaf tags using the [`LeafTag`](https://api.vapor.codes/leafkit/leaftag) protocol.
To demonstrate this, let's take a look at creating a custom tag `#now` that prints the current timestamp. The tag will also support a single, optional parameter for specifying the date format.
!!! tip
If your custom tag renders HTML you should conform your custom tag to `UnsafeUnescapedLeafTag` so the HTML is not escaped. Remember to check or sanitize any user input.
## `LeafTag`
First create a class called `NowTag` and conform it to `LeafTag`.
```swift
struct NowTag: LeafTag {
func render(_ ctx: LeafContext) throws -> LeafData {
...
}
}
```
Now let's implement the `render(_:)` method. The `LeafContext` context passed to this method has everything we should need.
```swift
enum NowTagError: Error {
case invalidFormatParameter
case tooManyParameters
}
struct NowTag: LeafTag {
func render(_ ctx: LeafContext) throws -> LeafData {
let formatter = DateFormatter()
switch ctx.parameters.count {
case 0: formatter.dateFormat = "yyyy-MM-dd HH:mm:ss"
case 1:
guard let string = ctx.parameters[0].string else {
throw NowTagError.invalidFormatParameter
}
formatter.dateFormat = string
default:
throw NowTagError.tooManyParameters
}
let dateAsString = formatter.string(from: Date())
return LeafData.string(dateAsString)
}
}
```
## Configure Tag
Now that we've implemented `NowTag`, we just need to tell Leaf about it. You can add any tag like this - even if they come from a separate package. You do this typically in `configure.swift`:
```swift
app.leaf.tags["now"] = NowTag()
```
And that's it! We can now use our custom tag in Leaf.
```leaf
The time is #now()
```
## Context Properties
The `LeafContext` contains two important properties. `parameters` and `data` that has everything we should need.
- `parameters`: An array that contains the parameters of the tag.
- `data`: A dictionary that contains the data of the view passed to `render(_:_:)` as the context.
### Example Hello Tag
To do see how to use this, let's implement a simple hello tag using both properties.
#### Using Parameters
We can access the first parameter that would contain the name.
```swift
enum HelloTagError: Error {
case missingNameParameter
}
struct HelloTag: UnsafeUnescapedLeafTag {
func render(_ ctx: LeafContext) throws -> LeafData {
guard let name = ctx.parameters[0].string else {
throw HelloTagError.missingNameParameter
}
return LeafData.string("Hello \(name)
")
}
}
```
```leaf
#hello("John")
```
#### Using Data
We can access the name value by using the "name" key inside the data property.
```swift
enum HelloTagError: Error {
case nameNotFound
}
struct HelloTag: UnsafeUnescapedLeafTag {
func render(_ ctx: LeafContext) throws -> LeafData {
guard let name = ctx.data["name"]?.string else {
throw HelloTagError.nameNotFound
}
return LeafData.string("Hello \(name)
")
}
}
```
```leaf
#hello()
```
_Controller_:
```swift
return try await req.view.render("home", ["name": "John"])
```
# Redis
[Redis](https://redis.io/) is one of the most popular in-memory data structure store commonly used as a cache or message broker.
This library is an integration between Vapor and [**RediStack**](https://github.com/swift-server/RediStack), which is the underlying driver that communicates with Redis.
!!! note
Most of the capabilities of Redis are provided by **RediStack**.
We highly recommend being familiar with its documentation.
_Links are provided where appropriate._
## Package
The first step to using Redis is adding it as a dependency to your project in your Swift package manifest.
> This example is for an existing package. For help on starting a new project, see the main [Getting Started](../getting-started/hello-world.md) guide.
```swift
dependencies: [
// ...
.package(url: "https://github.com/vapor/redis.git", from: "4.0.0")
]
// ...
targets: [
.target(name: "App", dependencies: [
// ...
.product(name: "Redis", package: "redis")
])
]
```
## Configure
Vapor employs a pooling strategy for [`RedisConnection`](https://swiftpackageindex.com/swift-server/RediStack/main/documentation/redistack/redisconnection) instances, and there are several options to configure individual connections as well as the pools themselves.
The bare minimum required for configuring Redis is to provide a URL to connect to:
```swift
let app = Application()
app.redis.configuration = try RedisConfiguration(hostname: "localhost")
```
### Redis Configuration
> API Documentation: [`RedisConfiguration`](https://api.vapor.codes/redis/redisconfiguration)
#### serverAddresses
If you have multiple Redis endpoints, such as a cluster of Redis instances, you'll want to create a [`[SocketAddress]`](https://swiftpackageindex.com/apple/swift-nio/main/documentation/niocore/socketaddress) collection to pass in the initializer instead.
The most common way of creating a `SocketAddress` is with the [`makeAddressResolvingHost(_:port:)`](https://swiftpackageindex.com/apple/swift-nio/main/documentation/niocore/socketaddress/makeaddressresolvinghost(_:port:)) static method.
```swift
let serverAddresses: [SocketAddress] = [
try .makeAddressResolvingHost("localhost", port: RedisConnection.Configuration.defaultPort)
]
```
For a single Redis endpoint, it can be easier to work with the convenience initializers, as it will handle creating the `SocketAddress` for you:
- [`.init(url:pool)`](https://api.vapor.codes/redis/redisconfiguration/init(url:tlsconfiguration:pool:)-o9lf) (with `String` or [`Foundation.URL`](https://developer.apple.com/documentation/foundation/url))
- [`.init(hostname:port:password:database:pool:)`](https://api.vapor.codes/redis/redisconfiguration/init(hostname:port:password:tlsconfiguration:database:pool:))
#### password
If your Redis instance is secured by a password, you will need to pass it as the `password` argument.
Each connection, as it is created, will be authenticated using the password.
#### database
This is the database index you wish to select when each connection is created.
This saves you from having to send the `SELECT` command to Redis yourself.
!!! warning
The database selection is not maintained. Be careful with sending the `SELECT` command on your own.
### Connection Pool Options
> API Documentation: [`RedisConfiguration.PoolOptions`](https://api.vapor.codes/redis/redisconfiguration/pooloptions)
!!! note
Only the most commonly changed options are highlighted here. For all of the options, refer to the API documentation.
#### minimumConnectionCount
This is the value to set how many connections you want each pool to maintain at all times.
If you value is `0` then if connections are lost for any reason, the pool will not recreate them until needed.
This is known as a "cold start" connection, and does have some overhead over maintaining a minimum connection count.
#### maximumConnectionCount
This option determines the behavior of how the maximum connection count is maintained.
!!! seealso
Refer to the `RedisConnectionPoolSize` API to be familiar with what options are available.
## Sending a Command
You can send commands using the `.redis` property on any [`Application`](https://api.vapor.codes/vapor/application) or [`Request`](https://api.vapor.codes/vapor/request) instance, which will give you access to a [`RedisClient`](https://swiftpackageindex.com/swift-server/RediStack/main/documentation/redistack/redisclient).
Any `RedisClient` has several extensions for all of the various [Redis commands](https://redis.io/commands).
```swift
let value = try app.redis.get("my_key", as: String.self).wait()
print(value)
// Optional("my_value")
// or
let value = try await app.redis.get("my_key", as: String.self)
print(value)
// Optional("my_value")
```
### Unsupported Commands
Should **RediStack** not support a command with an extension method, you can still send it manually.
```swift
// each value after the command is the positional argument that Redis expects
try app.redis.send(command: "PING", with: ["hello"])
.map {
print($0)
}
.wait()
// "hello"
// or
let res = try await app.redis.send(command: "PING", with: ["hello"])
print(res)
// "hello"
```
## Pub/Sub Mode
Redis supports the ability to enter a ["Pub/Sub" mode](https://redis.io/topics/pubsub) where a connection can listen to specific "channels" and run specific closures when the subscribed channels publish a "message" (some data value).
There is a defined lifecycle to a subscription:
1. **subscribe**: invoked once when the subscription first starts
1. **message**: invoked 0+ times as messages are published to the subscribed channels
1. **unsubscribe**: invoked once when the subscription ends, either by request or the connection being lost
When you create a subscription, you must provide at least a [`messageReceiver`](https://swiftpackageindex.com/swift-server/RediStack/main/documentation/redistack/redissubscriptionmessagereceiver) to handle all messages that are published by the subscribed channel.
You can optionally provide a `RedisSubscriptionChangeHandler` for `onSubscribe` and `onUnsubscribe` to handle their respective lifecycle events.
```swift
// creates 2 subscriptions, one for each given channel
app.redis.subscribe
to: "channel_1", "channel_2",
messageReceiver: { channel, message in
switch channel {
case "channel_1": // do something with the message
default: break
}
},
onUnsubscribe: { channel, subscriptionCount in
print("unsubscribed from \(channel)")
print("subscriptions remaining: \(subscriptionCount)")
}
```
# Redis & Sessions
Redis can act as a storage provider for caching [session data](../advanced/sessions.md#session-data) such as user credentials.
If a custom [`RedisSessionsDelegate`](https://api.vapor.codes/redis/redissessionsdelegate) isn't provided, a default will be used.
## Default Behavior
### SessionID Creation
Unless you implement the [`makeNewID()`](https://api.vapor.codes/redis/redissessionsdelegate/makenewid()) method in [your own `RedisSessionsDelegate`](#redissessionsdelegate), all [`SessionID`](https://api.vapor.codes/vapor/sessionid) values will be created by doing the following:
1. Generate 32 bytes of random characters
1. base64 encode the value
For example: `Hbxozx8rTj+XXGWAzOhh1npZFXaGLpTWpWCaXuo44xQ=`
### SessionData Storage
The default implementation of `RedisSessionsDelegate` will store [`SessionData`](https://api.vapor.codes/vapor/sessiondata) as a simple JSON string value using `Codable`.
Unless you implement the [`makeRedisKey(for:)`](https://api.vapor.codes/redis/redissessionsdelegate/makerediskey(for:)) method in your own `RedisSessionsDelegate`, `SessionData` will be stored in Redis with a key that prefixes the `SessionID` with `vrs-` (**V**apor **R**edis **S**essions)
For example: `vrs-Hbxozx8rTj+XXGWAzOhh1npZFXaGLpTWpWCaXuo44xQ=`
## Registering A Custom Delegate
To customize how the data is read from and written to Redis, register your own `RedisSessionsDelegate` object as follows:
```swift
import Redis
struct CustomRedisSessionsDelegate: RedisSessionsDelegate {
// implementation
}
app.sessions.use(.redis(delegate: CustomRedisSessionsDelegate()))
```
## RedisSessionsDelegate
> API Documentation: [`RedisSessionsDelegate`](https://api.vapor.codes/redis/redissessionsdelegate)
An object that conforms to this protocol can be used to change how `SessionData` is stored in Redis.
Only two methods are required to be implemented by a type conforming to the protocol: [`redis(_:store:with:)`](https://api.vapor.codes/redis/redissessionsdelegate/redis(_:store:with:)) and [`redis(_:fetchDataFor:)`](https://api.vapor.codes/redis/redissessionsdelegate/redis(_:fetchdatafor:)).
Both are required, as the way you customize writing the session data to Redis is intrinsically linked to how it is to be read from Redis.
### RedisSessionsDelegate Hash Example
For example, if you wanted to store the session data as a [**Hash** in Redis](https://redis.io/topics/data-types-intro#redis-hashes), you would implement something like the following:
```swift
func redis(
_ client: Client,
store data: SessionData,
with key: RedisKey
) -> EventLoopFuture {
// stores each data field as a separate hash field
return client.hmset(data.snapshot, in: key)
}
func redis(
_ client: Client,
fetchDataFor key: RedisKey
) -> EventLoopFuture {
return client
.hgetall(from: key)
.map { hash in
// hash is [String: RESPValue] so we need to try and unwrap the
// value as a string and store each value in the data container
return hash.reduce(into: SessionData()) { result, next in
guard let value = next.value.string else { return }
result[next.key] = value
}
}
}
```
# Middleware
Middleware is a logic chain between the client and a Vapor route handler. It allows you to perform operations on incoming requests before they get to the route handler and on outgoing responses before they go to the client.
## Configuration
Middleware can be registered globally (on every route) in `configure(_:)` using `app.middleware`.
```swift
app.middleware.use(MyMiddleware())
```
You can also add middleware to individual routes using route groups.
```swift
let group = app.grouped(MyMiddleware())
group.get("foo") { req in
// This request has passed through MyMiddleware.
}
```
### Order
The order in which middleware are added is important. Requests coming into your application will go through the middleware in the order they are added. Responses leaving your application will go back through the middleware in reverse order. Route-specific middleware always runs after application middleware. Take the following example:
```swift
app.middleware.use(MiddlewareA())
app.middleware.use(MiddlewareB())
app.group(MiddlewareC()) {
$0.get("hello") { req in
"Hello, middleware."
}
}
```
A request to `GET /hello` will visit middleware in the following order:
```
Request → A → B → C → Handler → C → B → A → Response
```
Middleware can be _prepended_ as well, which is useful when you want to add a middleware _before_ the default middleware vapor adds automatically:
```swift
app.middleware.use(someMiddleware, at: .beginning)
```
## Creating a Middleware
Vapor ships with a few useful middlewares, but you might need to create your own because of the requirements of your application. For example you could create a middleware that prevents any non-admin user from accessing a group of routes.
> We recommend creating a `Middleware` folder inside your `Sources/App` directory to keep your code organised
Middleware are types that conform to Vapor's `Middleware` or `AsyncMiddleware` protocol. They are inserted into the responder chain and can access and manipulate a request before it reaches a route handler and access and manipulate a response before it is returned.
Using the example mentioned above, create a middleware to block access to the user if they're not an admin:
```swift
import Vapor
struct EnsureAdminUserMiddleware: Middleware {
func respond(to request: Request, chainingTo next: Responder) -> EventLoopFuture {
guard let user = request.auth.get(User.self), user.role == .admin else {
return request.eventLoop.future(error: Abort(.unauthorized))
}
return next.respond(to: request)
}
}
```
Or if using `async`/`await` you can write:
```swift
import Vapor
struct EnsureAdminUserMiddleware: AsyncMiddleware {
func respond(to request: Request, chainingTo next: AsyncResponder) async throws -> Response {
guard let user = request.auth.get(User.self), user.role == .admin else {
throw Abort(.unauthorized)
}
return try await next.respond(to: request)
}
}
```
If you want to modify the response, for example to add a custom header, you can use a middleware for this too. Middlewares can wait until the response is received from the responder chain and manipulate the response:
```swift
import Vapor
struct AddVersionHeaderMiddleware: Middleware {
func respond(to request: Request, chainingTo next: Responder) -> EventLoopFuture {
next.respond(to: request).map { response in
response.headers.add(name: "My-App-Version", value: "v2.5.9")
return response
}
}
}
```
Or if using `async`/`await` you can write:
```swift
import Vapor
struct AddVersionHeaderMiddleware: AsyncMiddleware {
func respond(to request: Request, chainingTo next: AsyncResponder) async throws -> Response {
let response = try await next.respond(to: request)
response.headers.add(name: "My-App-Version", value: "v2.5.9")
return response
}
}
```
## File Middleware
`FileMiddleware` enables the serving of assets from the Public folder of your project to the client. You might include static files like stylesheets or bitmap images here.
```swift
let file = FileMiddleware(publicDirectory: app.directory.publicDirectory)
app.middleware.use(file)
```
Once `FileMiddleware` is registered, a file like `Public/images/logo.png` can be linked from a Leaf template as ` `.
If your server is contained in an Xcode Project, such as an iOS app, use this instead:
```swift
let file = try FileMiddleware(bundle: .main, publicDirectory: "Public")
```
Also make sure to use Folder References instead of Groups in Xcode to maintain folder structure in resources after building the application.
## CORS Middleware
Cross-origin resource sharing (CORS) is a mechanism that allows restricted resources on a web page to be requested from another domain outside the domain from which the first resource was served. REST APIs built in Vapor will require a CORS policy in order to safely return requests to modern web browsers.
An example configuration could look something like this:
```swift
let corsConfiguration = CORSMiddleware.Configuration(
allowedOrigin: .all,
allowedMethods: [.GET, .POST, .PUT, .OPTIONS, .DELETE, .PATCH],
allowedHeaders: [.accept, .authorization, .contentType, .origin, .xRequestedWith, .userAgent, .accessControlAllowOrigin]
)
let cors = CORSMiddleware(configuration: corsConfiguration)
// cors middleware should come before default error middleware using `at: .beginning`
app.middleware.use(cors, at: .beginning)
```
Given that thrown errors are immediately returned to the client, the `CORSMiddleware` must be listed _before_ the `ErrorMiddleware`. Otherwise, the HTTP error response will be returned without CORS headers, and cannot be read by the browser.
# Testing
## VaporTesting
Vapor includes a module named `VaporTesting` that provides test helpers built on `Swift Testing`. These testing helpers allow you to send test requests to your Vapor application programmatically or running over an HTTP server.
!!! note
For newer projects or teams adopting Swift concurrency, `Swift Testing` is highly recommended over `XCTest`.
### Getting Started
To use the `VaporTesting` module, ensure it has been added to your package's test target.
```swift
let package = Package(
...
dependencies: [
.package(url: "https://github.com/vapor/vapor.git", from: "4.110.1")
],
targets: [
...
.testTarget(name: "AppTests", dependencies: [
.target(name: "App"),
.product(name: "VaporTesting", package: "vapor"),
])
]
)
```
!!! warning
Be sure to use the corresponding testing module, as failing to do so can result in Vapor test failures not being properly reported.
Then, add `import VaporTesting` and `import Testing` at the top of your test files. Create structs with a `@Suite` name to write test cases.
```swift
@testable import App
import VaporTesting
import Testing
@Suite("App Tests")
struct AppTests {
@Test("Test Stub")
func stub() async throws {
// Test here.
}
}
```
Each function marked with `@Test` will run automatically when your app is tested.
To ensure your tests run in a serialized manner (e.g., when testing with a database), include the `.serialized` option in the test suite declaration:
```swift
@Suite("App Tests with DB", .serialized)
```
### Testable Application
To provide a streamlined and standardized setup and teardown of tests, `VaporTesting` offers the `withApp` helper function. This method encapsulates the lifecycle management of the `Application` instance, ensuring that the application is properly initialized, configured, and shut down for each test.
Pass your application's `configure(_:)` method to the `withApp` helper function to make sure all your routes get correctly registered:
```swift
@Test func someTest() async throws {
try await withApp(configure: configure) { app in
// your actual test
}
}
```
#### Send Request
To send a test request to your application, use the `withApp` private method and inside use the `app.testing().test()` method:
```swift
@Test("Test Hello World Route")
func helloWorld() async throws {
try await withApp(configure: configure) { app in
try await app.testing().test(.GET, "hello") { res async in
#expect(res.status == .ok)
#expect(res.body.string == "Hello, world!")
}
}
}
```
The first two parameters are the HTTP method and URL to request. The trailing closure accepts the HTTP response which you can verify using `#expect` macro.
For more complex requests, you can supply a `beforeRequest` closure to modify headers or encode content. Vapor's [Content API](../basics/content.md) is available on both the test request and response.
```swift
let newDTO = TodoDTO(id: nil, title: "test")
try await app.testing().test(.POST, "todos", beforeRequest: { req in
try req.content.encode(newDTO)
}, afterResponse: { res async throws in
#expect(res.status == .ok)
let models = try await Todo.query(on: app.db).all()
#expect(models.map({ $0.toDTO().title }) == [newDTO.title])
})
```
#### Testing Method
Vapor's testing API supports sending test requests programmatically and via a live HTTP server. You can specify which method you would like to use through the `testing` method.
```swift
// Use programmatic testing.
app.testing(method: .inMemory).test(...)
// Run tests through a live HTTP server.
app.testing(method: .running).test(...)
```
The `inMemory` option is used by default.
The `running` option supports passing a specific port to use. By default `8080` is used.
```swift
app.testing(method: .running(port: 8123)).test(...)
```
#### Database Integration Tests
Configure the database specifically for testing to ensure that your live database is never used during tests. For example, when you are using SQLite, you could configure your database in the `configure(_:)` function as follows:
```swift
public func configure(_ app: Application) async throws {
// All other configurations...
if app.environment == .testing {
app.databases.use(.sqlite(.memory), as: .sqlite)
} else {
app.databases.use(.sqlite(.file("db.sqlite")), as: .sqlite)
}
}
```
!!! warning
Make sure you run your tests against the correct database, so you prevent accidentally overwriting data you do not want to lose.
Then you can enhance your tests by using `autoMigrate()` and `autoRevert()` to manage the database schema and data lifecycle during testing. To do so, you should create your own helper function `withAppIncludingDB` that includes the database schema and data lifecycles:
```swift
private func withAppIncludingDB(_ test: (Application) async throws -> ()) async throws {
let app = try await Application.make(.testing)
do {
try await configure(app)
try await app.autoMigrate()
try await test(app)
try await app.autoRevert()
}
catch {
try? await app.autoRevert()
try await app.asyncShutdown()
throw error
}
try await app.asyncShutdown()
}
```
And then use this helper in your tests:
```swift
@Test func myDatabaseIntegrationTest() async throws {
try await withAppIncludingDB { app in
try await app.testing().test(.GET, "hello") { res async in
#expect(res.status == .ok)
#expect(res.body.string == "Hello, world!")
}
}
}
```
By combining these methods, you can ensure that each test starts with a fresh and consistent database state, making your tests more reliable and reducing the likelihood of false positives or negatives caused by lingering data.
## XCTVapor
Vapor includes a module named `XCTVapor` that provides test helpers built on `XCTest`. These testing helpers allow you to send test requests to your Vapor application programmatically or running over an HTTP server.
### Getting Started
To use the `XCTVapor` module, ensure it has been added to your package's test target.
```swift
let package = Package(
...
dependencies: [
.package(url: "https://github.com/vapor/vapor.git", from: "4.0.0")
],
targets: [
...
.testTarget(name: "AppTests", dependencies: [
.target(name: "App"),
.product(name: "XCTVapor", package: "vapor"),
])
]
)
```
Then, add `import XCTVapor` at the top of your test files. Create classes extending `XCTestCase` to write test cases.
```swift
import XCTVapor
final class MyTests: XCTestCase {
func testStub() throws {
// Test here.
}
}
```
Each function beginning with `test` will run automatically when your app is tested.
### Testable Application
Initialize an instance of `Application` using the `.testing` environment. You must call `app.shutdown()` before this application deinitializes.
The shutdown is necessary to help release the resources that the app has claimed. In particular it is important to release the threads the application requests at startup. If you do not call `shutdown()` on the app after each unit test, you may find your test suite crash with a precondition failure when allocating threads for a new instance of `Application`.
```swift
let app = Application(.testing)
defer { app.shutdown() }
try configure(app)
```
Pass the `Application` to your package's `configure(_:)` method to apply your configuration. Any test-only configurations can be applied after.
#### Send Request
To send a test request to your application, use the `test` method.
```swift
try app.test(.GET, "hello") { res in
XCTAssertEqual(res.status, .ok)
XCTAssertEqual(res.body.string, "Hello, world!")
}
```
The first two parameters are the HTTP method and URL to request. The trailing closure accepts the HTTP response which you can verify using `XCTAssert` methods.
For more complex requests, you can supply a `beforeRequest` closure to modify headers or encode content. Vapor's [Content API](../basics/content.md) is available on both the test request and response.
```swift
try app.test(.POST, "todos", beforeRequest: { req in
try req.content.encode(["title": "Test"])
}, afterResponse: { res in
XCTAssertEqual(res.status, .created)
let todo = try res.content.decode(Todo.self)
XCTAssertEqual(todo.title, "Test")
})
```
#### Testable Method
Vapor's testing API supports sending test requests programmatically and via a live HTTP server. You can specify which method you would like to use by using the `testable` method.
```swift
// Use programmatic testing.
app.testable(method: .inMemory).test(...)
// Run tests through a live HTTP server.
app.testable(method: .running).test(...)
```
The `inMemory` option is used by default.
The `running` option supports passing a specific port to use. By default `8080` is used.
```swift
.running(port: 8123)
```
# Server
Vapor includes a high-performance, asynchronous HTTP server built on [SwiftNIO](https://github.com/apple/swift-nio). This server supports HTTP/1, HTTP/2, and protocol upgrades like [WebSockets](websockets.md). The server also supports enabling TLS (SSL).
## Configuration
Vapor's default HTTP server can be configured via `app.http.server`.
```swift
// Only support HTTP/2
app.http.server.configuration.supportVersions = [.two]
```
The HTTP server supports several configuration options.
### Hostname
The hostname controls which address the server will accept new connections on. The default is `127.0.0.1`.
```swift
// Configure custom hostname.
app.http.server.configuration.hostname = "dev.local"
```
The server configuration's hostname can be overridden by passing the `--hostname` (`-H`) flag to the `serve` command or by passing the `hostname` parameter to `app.server.start(...)`.
```sh
# Override configured hostname.
swift run App serve --hostname dev.local
```
### Port
The port option controls which port at the specified address the server will accept new connections on. The default is `8080`.
```swift
// Configure custom port.
app.http.server.configuration.port = 1337
```
!!! info
`sudo` may be required for binding to ports less than `1024`. Ports greater than `65535` are not supported.
The server configuration's port can be overridden by passing the `--port` (`-p`) flag to the `serve` command or by passing the `port` parameter to `app.server.start(...)`.
```sh
# Override configured port.
swift run App serve --port 1337
```
### Backlog
The `backlog` parameter defines the maximum length for the queue of pending connections. The default is `256`.
```swift
// Configure custom backlog.
app.http.server.configuration.backlog = 128
```
### Reuse Address
The `reuseAddress` parameter allows for reuse of local addresses. Defaults to `true`.
```swift
// Disable address reuse.
app.http.server.configuration.reuseAddress = false
```
### TCP No Delay
Enabling the `tcpNoDelay` parameter will attempt to minimize TCP packet delay. Defaults to `true`.
```swift
// Minimize packet delay.
app.http.server.configuration.tcpNoDelay = true
```
### Response Compression
The `responseCompression` parameter controls HTTP response compression using gzip. The default is `.disabled`.
```swift
// Enable HTTP response compression.
app.http.server.configuration.responseCompression = .enabled
```
To specify an initial buffer capacity, use the `initialByteBufferCapacity` parameter.
```swift
.enabled(initialByteBufferCapacity: 1024)
```
### Request Decompression
The `requestDecompression` parameter controls HTTP request decompression using gzip. The default is `.disabled`.
```swift
// Enable HTTP request decompression.
app.http.server.configuration.requestDecompression = .enabled
```
To specify a decompression limit, use the `limit` parameter. The default is `.ratio(10)`.
```swift
// No decompression size limit
.enabled(limit: .none)
```
Available options are:
- `size`: Maximum decompressed size in bytes.
- `ratio`: Maximum decompressed size as ratio of compressed bytes.
- `none`: No size limits.
Setting decompression size limits can help prevent maliciously compressed HTTP requests from using large amounts of memory.
### Pipelining
The `supportPipelining` parameter enables support for HTTP request and response pipelining. The default is `false`.
```swift
// Support HTTP pipelining.
app.http.server.configuration.supportPipelining = true
```
### Versions
The `supportVersions` parameter controls which HTTP versions the server will use. By default, Vapor will support both HTTP/1 and HTTP/2 when TLS is enabled. Only HTTP/1 is supported when TLS is disabled.
```swift
// Disable HTTP/1 support.
app.http.server.configuration.supportVersions = [.two]
```
### TLS
The `tlsConfiguration` parameter controls whether TLS (SSL) is enabled on the server. The default is `nil`.
```swift
// Enable TLS.
app.http.server.configuration.tlsConfiguration = .makeServerConfiguration(
certificateChain: try NIOSSLCertificate.fromPEMFile("/path/to/cert.pem").map { .certificate($0) },
privateKey: .privateKey(try NIOSSLPrivateKey(file: "/path/to/key.pem", format: .pem))
)
```
For this configuration to compile you need to add `import NIOSSL` at the top of your configuration file. You also might need to add NIOSSL as a dependency in your Package.swift file.
### Name
The `serverName` parameter controls the `Server` header on outgoing HTTP responses. The default is `nil`.
```swift
// Add 'Server: vapor' header to responses.
app.http.server.configuration.serverName = "vapor"
```
## Serve Command
To start up Vapor's server, use the `serve` command. This command will run by default if no other commands are specified.
```swift
swift run App serve
```
The `serve` command accepts the following parameters:
- `hostname` (`-H`): Overrides configured hostname.
- `port` (`-p`): Overrides configured port.
- `bind` (`-b`): Overrides configured hostname and port joined by `:`.
An example using the `--bind` (`-b`) flag:
```swift
swift run App serve -b 0.0.0.0:80
```
Use `swift run App serve --help` for more information.
The `serve` command will listen for `SIGTERM` and `SIGINT` to gracefully shutdown the server. Use `ctrl+c` (`^c`) to send a `SIGINT` signal. When the log level is set to `debug` or lower, information about the status of graceful shutdown will be logged.
## Manual Start
Vapor's server can be started manually using `app.server`.
```swift
// Start Vapor's server.
try app.server.start()
// Request server shutdown.
app.server.shutdown()
// Wait for the server to shutdown.
try app.server.onShutdown.wait()
```
## Servers
The server Vapor uses is configurable. By default, the built in HTTP server is used.
```swift
app.servers.use(.http)
```
### Custom Server
Vapor's default HTTP server can be replaced by any type conforming to `Server`.
```swift
import Vapor
final class MyServer: Server {
...
}
app.servers.use { app in
MyServer()
}
```
Custom servers can extend `Application.Servers.Provider` for leading-dot syntax.
```swift
extension Application.Servers.Provider {
static var myServer: Self {
.init {
$0.servers.use { app in
MyServer()
}
}
}
}
app.servers.use(.myServer)
```
# Files
Vapor offers a simple API for reading and writing files asynchronously within route handlers. This API is built on top of NIO's [`NonBlockingFileIO`](https://swiftpackageindex.com/apple/swift-nio/main/documentation/nioposix/nonblockingfileio) type.
## Read
The main method for reading a file delivers chunks to a callback handler as they are read off the disk. The file to read is specified by its path. Relative paths will look in the process's current working directory.
```swift
// Asynchronously reads a file from disk.
let readComplete: EventLoopFuture = req.fileio.readFile(at: "/path/to/file") { chunk in
print(chunk) // ByteBuffer
}
// Or
let file = try await req.fileio.readFile(at: "/path/to/file")
for try await chunk in file {
print(chunk) // ByteBuffer
}
// Read is complete
```
If using `EventLoopFuture`s, the returned future will signal when the read has completed or an error has occurred. If using `async`/`await` then once the `await` has return the read has completed. If an error has occurred it will throw an error.
### Stream
The `streamFile` method converts a streaming file to a `Response`. This method will set appropriate headers such as `ETag` and `Content-Type` automatically.
```swift
// Asynchronously streams file as HTTP response.
req.fileio.streamFile(at: "/path/to/file").map { res in
print(res) // Response
}
// Or
let res = req.fileio.streamFile(at: "/path/to/file")
print(res)
```
The result can be returned directly by your route handler.
### Collect
The `collectFile` method reads the specified file into a buffer.
```swift
// Reads the file into a buffer.
req.fileio.collectFile(at: "/path/to/file").map { buffer in
print(buffer) // ByteBuffer
}
// or
let buffer = req.fileio.collectFile(at: "/path/to/file")
print(buffer)
```
!!! warning
This method requires the entire file to be in memory at once. Use chunked or streaming read to limit memory usage.
## Write
The `writeFile` method supports writing a buffer to a file.
```swift
// Writes buffer to file.
req.fileio.writeFile(ByteBuffer(string: "Hello, world"), at: "/path/to/file")
```
The returned future will signal when the write has completed or an error has occurred.
## Middleware
For more information on serving files from your project's _Public_ folder automatically, see [Middleware → FileMiddleware](middleware.md#file-middleware).
## Advanced
For cases that Vapor's API doesn't support, you can use NIO's `NonBlockingFileIO` type directly.
```swift
// Main thread.
let fileHandle = try await app.fileio.openFile(
path: "/path/to/file",
eventLoop: app.eventLoopGroup.next()
).get()
print(fileHandle)
// In a route handler.
let fileHandle = try await req.application.fileio.openFile(
path: "/path/to/file",
eventLoop: req.eventLoop)
print(fileHandle)
```
For more information, visit SwiftNIO's [API reference](https://swiftpackageindex.com/apple/swift-nio/main/documentation/nioposix/nonblockingfileio).
# Commands
Vapor's Command API allows you to build custom command-line functions and interact with the terminal. It is what Vapor's default commands like `serve`, `routes`, and `migrate` are built on.
## Default Commands
You can learn more about Vapor's default commands using the `--help` option.
```sh
swift run App --help
```
You can use `--help` on a specific command to see what arguments and options it accepts.
```sh
swift run App serve --help
```
### Xcode
You can run commands in Xcode by adding arguments to the `App` scheme. To do this, follow these steps:
- Choose `App` scheme (to the right of play/stop buttons)
- Click "Edit Scheme"
- Choose "App" product
- Select "Arguments" tab
- Add the name of the command to "Arguments Passed On Launch" (i.e., `serve`)
## Custom Commands
You can create your own commands by creating types conforming to `AsyncCommand`.
```swift
import Vapor
struct HelloCommand: AsyncCommand {
...
}
```
Adding the custom command to `app.asyncCommands` will make it available via `swift run`.
```swift
app.asyncCommands.use(HelloCommand(), as: "hello")
```
To conform to `AsyncCommand`, you must implement the `run` method. This requires declaring a `Signature`. You must also provide default help text.
```swift
import Vapor
struct HelloCommand: AsyncCommand {
struct Signature: CommandSignature { }
var help: String {
"Says hello"
}
func run(using context: CommandContext, signature: Signature) async throws {
context.console.print("Hello, world!")
}
}
```
This simple command example has no arguments or options, so leave the signature empty.
You can get access to the current console via the supplied context. Console has many helpful methods for prompting user input, output formatting, and more.
```swift
let name = context.console.ask("What is your \("name", color: .blue)?")
context.console.print("Hello, \(name) 👋")
```
Test your command by running:
```sh
swift run App hello
```
### Cowsay
Take a look at this re-creation of the famous [`cowsay`](https://en.wikipedia.org/wiki/Cowsay) command for an example of using `@Argument` and `@Option`.
```swift
import Vapor
struct Cowsay: AsyncCommand {
struct Signature: CommandSignature {
@Argument(name: "message")
var message: String
@Option(name: "eyes", short: "e")
var eyes: String?
@Option(name: "tongue", short: "t")
var tongue: String?
}
var help: String {
"Generates ASCII picture of a cow with a message."
}
func run(using context: CommandContext, signature: Signature) async throws {
let eyes = signature.eyes ?? "oo"
let tongue = signature.tongue ?? " "
let cow = #"""
< $M >
\ ^__^
\ ($E)\_______
(__)\ )\/\
$T ||----w |
|| ||
"""#.replacingOccurrences(of: "$M", with: signature.message)
.replacingOccurrences(of: "$E", with: eyes)
.replacingOccurrences(of: "$T", with: tongue)
context.console.print(cow)
}
}
```
Try adding this to your application and running it.
```swift
app.asyncCommands.use(Cowsay(), as: "cowsay")
```
```sh
swift run App cowsay sup --eyes ^^ --tongue "U "
```
# Queues
Vapor Queues ([vapor/queues](https://github.com/vapor/queues)) is a pure Swift queuing system that allows you to offload task responsibility to a side worker.
Some of the tasks this package works well for:
- Sending emails outside of the main request thread
- Performing complex or long-running database operations
- Ensuring job integrity and resilience
- Speeding up response time by delaying non-critical processing
- Scheduling jobs to occur at a specific time
This package is similar to [Ruby Sidekiq](https://github.com/mperham/sidekiq). It provides the following features:
- Safe handling of `SIGTERM` and `SIGINT` signals sent by hosting providers to indicate a shutdown, restart, or new deploy.
- Different queue priorities. For example, you can specify a queue job to be run on the email queue and another job to be run on the data-processing queue.
- Implements the reliable queue process to help with unexpected failures.
- Includes a `maxRetryCount` feature that will repeat the job until it succeeds up until a specified count.
- Uses NIO to utilize all available cores and EventLoops for jobs.
- Allows users to schedule repeating tasks
Queues currently has one officially supported driver which interfaces with the main protocol:
- [QueuesRedisDriver](https://github.com/vapor/queues-redis-driver)
Queues also has community-based drivers:
- [QueuesMongoDriver](https://github.com/vapor-community/queues-mongo-driver)
- [QueuesFluentDriver](https://github.com/vapor-community/vapor-queues-fluent-driver)
!!! tip
You should not install the `vapor/queues` package directly unless you are building a new driver. Install one of the driver packages instead.
## Getting Started
Let's take a look at how you can get started using Queues.
### Package
The first step to using Queues is adding one of the drivers as a dependency to your project in your SwiftPM package manifest file. In this example, we'll use the Redis driver.
```swift
// swift-tools-version:5.8
import PackageDescription
let package = Package(
name: "MyApp",
dependencies: [
/// Any other dependencies ...
.package(url: "https://github.com/vapor/queues-redis-driver.git", from: "1.0.0"),
],
targets: [
.executableTarget(name: "App", dependencies: [
// Other dependencies
.product(name: "QueuesRedisDriver", package: "queues-redis-driver")
]),
.testTarget(name: "AppTests", dependencies: [.target(name: "App")]),
]
)
```
If you edit the manifest directly inside Xcode, it will automatically pick up the changes and fetch the new dependency when the file is saved. Otherwise, from Terminal, run `swift package resolve` to fetch the new dependency.
### Config
The next step is to configure Queues in `configure.swift`. We'll use the Redis library as an example:
```swift
import QueuesRedisDriver
try app.queues.use(.redis(url: "redis://127.0.0.1:6379"))
```
### Registering a `Job`
After modeling a job you must add it to your configuration section like this:
```swift
// Register jobs
let emailJob = EmailJob()
app.queues.add(emailJob)
```
### Running Workers as Processes
To start a new queue worker, run `swift run App queues`. You can also specify a specific type of worker to run: `swift run App queues --queue emails`.
!!! tip
Workers should stay running in production. Consult your hosting provider to find out how to keep long-running processes alive. Heroku, for example, allows you to specify "worker" dynos like this in your Procfile: `worker: Run queues`. With this in place, you can start workers on the Dashboard/Resources tab, or with `heroku ps:scale worker=1` (or any number of dynos preferred).
### Running Workers in-process
To run a worker in the same process as your application (as opposed to starting a whole separate server to handle it), call the convenience methods on `Application`:
```swift
try app.queues.startInProcessJobs(on: .default)
```
To run scheduled jobs in process, call the following method:
```swift
try app.queues.startScheduledJobs()
```
!!! warning
If you don't start the queue worker either via command line or the in-process worker the jobs will not dispatch.
## The `Job` Protocol
Jobs are defined by the `Job` or `AsyncJob` protocol.
### Modeling a `Job` object:
```swift
import Vapor
import Foundation
import Queues
struct Email: Codable {
let to: String
let message: String
}
struct EmailJob: Job {
typealias Payload = Email
func dequeue(_ context: QueueContext, _ payload: Email) -> EventLoopFuture {
// This is where you would send the email
return context.eventLoop.future()
}
func error(_ context: QueueContext, _ error: Error, _ payload: Email) -> EventLoopFuture {
// If you don't want to handle errors you can simply return a future. You can also omit this function entirely.
return context.eventLoop.future()
}
}
```
If using `async`/`await` you should use `AsyncJob`:
```swift
struct EmailJob: AsyncJob {
typealias Payload = Email
func dequeue(_ context: QueueContext, _ payload: Email) async throws {
// This is where you would send the email
}
func error(_ context: QueueContext, _ error: Error, _ payload: Email) async throws {
// If you don't want to handle errors you can simply return. You can also omit this function entirely.
}
}
```
!!! info
Make sure your `Payload` type implements the `Codable` protocol.
!!! tip
Don't forget to follow the instructions in **Getting Started** to add this job to your configuration file.
## Dispatching Jobs
To dispatch a queue job, you need access to an instance of `Application` or `Request`. You will most likely be dispatching jobs inside of a route handler:
```swift
app.get("email") { req -> EventLoopFuture in
return req
.queue
.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message")
).map { "done" }
}
// or
app.get("email") { req async throws -> String in
try await req.queue.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message"))
return "done"
}
```
If you, instead, need to dispatch a job from a context where the `Request` object is not available (like, for example, from within a `Command`), you will need to use the `queues` property inside the `Application` object, such as:
```swift
struct SendEmailCommand: AsyncCommand {
func run(using context: CommandContext, signature: Signature) async throws {
context
.application
.queues
.queue
.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message")
)
}
}
```
### Setting `maxRetryCount`
Jobs will automatically retry themselves upon error if you specify a `maxRetryCount`. For example:
```swift
app.get("email") { req -> EventLoopFuture in
return req
.queue
.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message"),
maxRetryCount: 3
).map { "done" }
}
// or
app.get("email") { req async throws -> String in
try await req.queue.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message"),
maxRetryCount: 3)
return "done"
}
```
### Specifying a delay
Jobs can also be set to only run after a certain `Date` has passed. To specify a delay, pass a `Date` into the `delayUntil` parameter in `dispatch`:
```swift
app.get("email") { req async throws -> String in
let futureDate = Date(timeIntervalSinceNow: 60 * 60 * 24) // One day
try await req.queue.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message"),
maxRetryCount: 3,
delayUntil: futureDate)
return "done"
}
```
If a job is dequeued before its delay parameter, the job will be re-queued by the driver.
### Specify a priority
Jobs can be sorted into different queue types/priorities depending on your needs. For example, you may want to open an `email` queue and a `background-processing` queue to sort jobs.
Start by extending `QueueName`:
```swift
extension QueueName {
static let emails = QueueName(string: "emails")
}
```
You can also set a per-queue `workerCount` when creating a `QueueName`:
```swift
extension QueueName {
static let serialEmails = QueueName(string: "serial-emails", workerCount: 1)
}
```
Setting `workerCount: 1` makes that queue process jobs consecutively, which is useful when job order matters.
Then, specify the queue type when you retrieve the `jobs` object:
```swift
app.get("email") { req -> EventLoopFuture in
let futureDate = Date(timeIntervalSinceNow: 60 * 60 * 24) // One day
return req
.queues(.emails)
.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message"),
maxRetryCount: 3,
delayUntil: futureDate
).map { "done" }
}
// or
app.get("email") { req async throws -> String in
let futureDate = Date(timeIntervalSinceNow: 60 * 60 * 24) // One day
try await req
.queues(.emails)
.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message"),
maxRetryCount: 3,
delayUntil: futureDate
)
return "done"
}
```
When accessing from within the `Application` object you should do as follows:
```swift
struct SendEmailCommand: AsyncCommand {
func run(using context: CommandContext, signature: Signature) async throws {
context
.application
.queues
.queue(.emails)
.dispatch(
EmailJob.self,
.init(to: "email@email.com", message: "message"),
maxRetryCount: 3,
delayUntil: futureDate
)
}
}
```
If you do not specify a queue the job will be run on the `default` queue. Make sure to follow the instructions in **Getting Started** to start workers for each queue type.
## Scheduling Jobs
The Queues package also allows you to schedule jobs to occur at certain points in time.
!!! warning
Scheduled jobs only work when set up before the application boots up, such as in `configure.swift`. They will not work in route handlers.
### Starting the scheduler worker
The scheduler requires a separate worker process to be running, similar to the queue worker. You can start the worker by running this command:
```sh
swift run App queues --scheduled
```
!!! tip
Workers should stay running in production. Consult your hosting provider to find out how to keep long-running processes alive. Heroku, for example, allows you to specify "worker" dynos like this in your Procfile: `worker: App queues --scheduled`
### Creating a `ScheduledJob`
To begin, start by creating a new `ScheduledJob` or `AsyncScheduledJob`:
```swift
import Vapor
import Queues
struct CleanupJob: ScheduledJob {
// Add extra services here via dependency injection, if you need them.
func run(context: QueueContext) -> EventLoopFuture {
// Do some work here, perhaps queue up another job.
return context.eventLoop.makeSucceededFuture(())
}
}
struct CleanupJob: AsyncScheduledJob {
// Add extra services here via dependency injection, if you need them.
func run(context: QueueContext) async throws {
// Do some work here, perhaps queue up another job.
}
}
```
Then, in your configure code, register the scheduled job:
```swift
app.queues.schedule(CleanupJob())
.yearly()
.in(.may)
.on(23)
.at(.noon)
```
The job in the example above will be run every year on May 23rd at 12:00 PM.
!!! tip
The Scheduler takes the timezone of your server.
### Available builder methods
There are two styles of scheduler APIs:
- Calendar-style builders that return builder objects for chaining.
- Interval-style builders that run jobs every fixed duration.
You should continue building out a calendar-style scheduler chain until the compiler does not give you a warning about an unused result. See below for all available methods:
| Helper Function | Available Modifiers | Description |
|-----------------|---------------------------------------|--------------------------------------------------------------------------------|
| `yearly()` | `in(_ month: Month) -> Monthly` | The month to run the job in. Returns a `Monthly` object for further building. |
| `monthly()` | `on(_ day: Day) -> Daily` | The day to run the job in. Returns a `Daily` object for further building. |
| `weekly()` | `on(_ weekday: Weekday) -> Daily` | The day of the week to run the job on. Returns a `Daily` object. |
| `daily()` | `at(_ time: Time)` | The time to run the job on. Final method in the chain. |
| | `at(_ hour: Hour24, _ minute: Minute)`| The hour and minute to run the job on. Final method in the chain. |
| | `at(_ hour: Hour12, _ minute: Minute, _ period: HourPeriod)` | The hour, minute, and period to run the job on. Final method of the chain |
| `hourly()` | `at(_ minute: Minute)` | The minute to run the job at. Final method of the chain. |
| `minutely()` | `at(_ second: Second)` | The second to run the job at. Final method of the chain. |
### Interval builder methods (`.every(...)`)
The scheduler also supports fixed-interval scheduling with `.every(...)` methods:
| Helper Function | Description |
|-----------------|--------------------------------------------------------------------------------|
| `every(seconds: Int)` | Runs the job every given number of seconds. |
| `every(minutes: Int)` | Runs the job every given number of minutes. |
| `every(hours: Int)` | Runs the job every given number of hours. |
| `every(days: Int)` | Runs the job every given number of days. |
| `every(weeks: Int)` | Runs the job every given number of weeks. |
Example:
```swift
app.queues.schedule(CleanupJob())
.every(hours: 6)
```
### Available helpers
Queues ships with some helpers enums to make scheduling easier:
| Helper Function | Available Helper Enum |
|-----------------|---------------------------------------|
| `yearly()` | `.january`, `.february`, `.march`, ...|
| `monthly()` | `.first`, `.last`, `.exact(1)` |
| `weekly()` | `.sunday`, `.monday`, `.tuesday`, ... |
| `daily()` | `.midnight`, `.noon` |
To use the helper enum, call in to the appropriate modifier on the helper function and pass the value. For example:
```swift
// Every year in January
.yearly().in(.january)
// Every month on the first day
.monthly().on(.first)
// Every week on Sunday
.weekly().on(.sunday)
// Every day at midnight
.daily().at(.midnight)
```
## Event Delegates
The Queues package allows you to specify `JobEventDelegate` objects that will receive notifications when the worker takes action on a job. This can be used for monitoring, surfacing insights, or alerting purposes.
To get started, conform an object to `JobEventDelegate` and implement any required methods
```swift
struct MyEventDelegate: JobEventDelegate {
/// Called when the job is dispatched to the queue worker from a route
func dispatched(job: JobEventData, eventLoop: EventLoop) -> EventLoopFuture {
eventLoop.future()
}
/// Called when the job is placed in the processing queue and work begins
func didDequeue(jobId: String, eventLoop: EventLoop) -> EventLoopFuture {
eventLoop.future()
}
/// Called when the job has finished processing and has been removed from the queue
func success(jobId: String, eventLoop: EventLoop) -> EventLoopFuture {
eventLoop.future()
}
/// Called when the job has finished processing but had an error
func error(jobId: String, error: Error, eventLoop: EventLoop) -> EventLoopFuture {
eventLoop.future()
}
}
```
Then, add it in your configuration file:
```swift
app.queues.add(MyEventDelegate())
```
There are a number of third-party packages that use the delegate functionality to provide additional insight into your queue workers:
- [QueuesDatabaseHooks](https://github.com/vapor-community/queues-database-hooks)
- [QueuesDash](https://github.com/gotranseo/queues-dash)
## Testing
To avoid synchronization problems and ensure deterministic testing, the Queues package provides an `XCTQueue` library and an `AsyncTestQueuesDriver` driver dedicated to testing which you can use as follows:
```swift
final class UserCreationServiceTests: XCTestCase {
var app: Application!
override func setUp() async throws {
self.app = try await Application.make(.testing)
try await configure(app)
// Override the driver being used for testing
app.queues.use(.asyncTest)
}
override func tearDown() async throws {
try await self.app.asyncShutdown()
self.app = nil
}
}
```
See more details in [Romain Pouclet's blog post](https://romain.codes/2024/10/08/using-and-testing-vapor-queues/).
# Troubleshooting
When using [queues-redis-driver](https://github.com/vapor/queues-redis-driver) with a cluster based Redis-compatible server, such as Redis or Valkey on Amazon AWS, you might run into this error message: `CROSSSLOT Keys in request don't hash to the same slot`.
This only happens in cluster mode, because Redis or Valkey can't know for sure on which cluster node to store the job data.
To fix this, add a [hash tag](https://redis.io/docs/latest/operate/oss_and_stack/reference/cluster-spec/#hash-tags) to the names of your job data entries by using curly brackets in the names:
```swift
app.queues.configuration.persistenceKey = "vapor-queues-{queues}"
```
# WebSockets
[WebSockets](https://en.wikipedia.org/wiki/WebSocket) allow for two-way communication between a client and server. Unlike HTTP, which has a request and response pattern, WebSocket peers can send an arbitrary number of messages in either direction. Vapor's WebSocket API allows you to create both clients and servers that handle messages asynchronously.
## Server
WebSocket endpoints can be added to your existing Vapor application using the Routing API. Use the `webSocket` method like you would use `get` or `post`.
```swift
app.webSocket("echo") { req, ws in
// Connected WebSocket.
print(ws)
}
```
WebSocket routes can be grouped and protected by middleware like normal routes.
In addition to accepting the incoming HTTP request, WebSocket handlers accept the newly established WebSocket connection. See below for more information on using this WebSocket to send and read messages.
## Client
To connect to a remote WebSocket endpoint, use `WebSocket.connect`.
```swift
WebSocket.connect(to: "ws://echo.websocket.org", on: eventLoop) { ws in
// Connected WebSocket.
print(ws)
}
```
The `connect` method returns a future that completes when the connection is established. Once connected, the supplied closure will be called with the newly connected WebSocket. See below for more information on using this WebSocket to send and read messages.
## Messages
The `WebSocket` class has methods for sending and receiving messages as well as listening for events like closure. WebSockets can transmit data via two protocols: text and binary. Text messages are interpreted as UTF-8 strings while binary data is interpreted as an array of bytes.
### Sending
Messages can be sent using the WebSocket's `send` method.
```swift
ws.send("Hello, world")
```
Passing a `String` to this method results in a text message being sent. Binary messages can be sent by passing a `[UInt8]`.
```swift
ws.send([1, 2, 3])
```
Message sending is asynchronous. You can supply an `EventLoopPromise` to the send method to be notified when the message has finished sending or failed to send.
```swift
let promise = eventLoop.makePromise(of: Void.self)
ws.send(..., promise: promise)
promise.futureResult.whenComplete { result in
// Succeeded or failed to send.
}
```
If using `async`/`await` you can use `await` to wait for the asynchronous operation to complete
```swift
try await ws.send(...)
```
### Receiving
Incoming messages are handled via the `onText` and `onBinary` callbacks.
```swift
ws.onText { ws, text in
// String received by this WebSocket.
print(text)
}
ws.onBinary { ws, binary in
// [UInt8] received by this WebSocket.
print(binary)
}
```
The WebSocket itself is supplied as the first parameter to these callbacks to prevent reference cycles. Use this reference to take action on the WebSocket after receiving data. For example, to send a reply:
```swift
// Echoes received messages.
ws.onText { ws, text in
ws.send(text)
}
```
## Closing
To close a WebSocket, call the `close` method.
```swift
ws.close()
```
This method returns a future that will be completed when the WebSocket has closed. Like `send`, you may also pass a promise to this method.
```swift
ws.close(promise: nil)
```
Or `await` on it if using `async`/`await`:
```swift
try await ws.close()
```
To be notified when the peer closes the connection, use `onClose`. This future will be completed when either the client or server closes the WebSocket.
```swift
ws.onClose.whenComplete { result in
// Succeeded or failed to close.
}
```
The `closeCode` property is set when the WebSocket closes. This can be used to determine why the peer closed the connection.
## Ping / Pong
Ping and pong messages are sent automatically by the client and server to keep WebSocket connections alive. Your application can listen for these events using the `onPing` and `onPong` callbacks.
```swift
ws.onPing { ws in
// Ping was received.
}
ws.onPong { ws in
// Pong was received.
}
```
# Sessions
Sessions allow you to persist a user's data between multiple requests. Sessions work by creating and returning a unique cookie alongside the HTTP response when a new session is initialized. Browsers will automatically detect this cookie and include it in future requests. This allows Vapor to automatically restore a specific user's session in your request handler.
Sessions are great for front-end web applications built in Vapor that serve HTML directly to web browsers. For APIs, we recommend using stateless, [token-based authentication](../security/authentication.md) to persist user data between requests.
## Configuration
To use sessions in a route, the request must pass through `SessionsMiddleware`. The easiest way to achieve this is by adding this middleware globally. It is recommended that you do add this after you declare the cookie factory. This is because Sessions is a struct, therefore it is a value type, and not a reference type. Since it is a value type, you must set the value before using `SessionsMiddleware`.
```swift
app.middleware.use(app.sessions.middleware)
```
If only a subset of your routes utilize sessions, you can instead add `SessionsMiddleware` to a route group.
```swift
let sessions = app.grouped(app.sessions.middleware)
```
The HTTP cookie generated by sessions can be configured using `app.sessions.configuration`. You can change the cookie name and declare a custom function for generating cookie values.
```swift
// Change the cookie name to "foo".
app.sessions.configuration.cookieName = "foo"
// Configures cookie value creation.
app.sessions.configuration.cookieFactory = { sessionID in
.init(string: sessionID.string, isSecure: true)
}
app.middleware.use(app.sessions.middleware)
```
By default, Vapor will use `vapor_session` as the cookie name.
## Drivers
Session drivers are responsible for storing and retrieving session data by identifier. You can create custom drivers by conforming to the `SessionDriver` protocol.
!!! warning
The session driver should be configured _before_ adding `app.sessions.middleware` to your application.
### In-Memory
Vapor utilizes in-memory sessions by default. In-memory sessions require zero configuration and do not persist between application launches which makes them great for testing. To enable in-memory sessions manually, use `.memory`:
```swift
app.sessions.use(.memory)
```
For production use cases, take a look at the other session drivers which utilize databases to persist and share sessions across multiple instances of your app.
### Fluent
Fluent includes support for storing session data in your application's database. This section assumes you have [configured Fluent](../fluent/overview.md) and can connect to a database. The first step is to enable the Fluent sessions driver.
```swift
import Fluent
app.sessions.use(.fluent)
```
This will configure sessions to use the application's default database. To specify a specific database, pass the database's identifier.
```swift
app.sessions.use(.fluent(.sqlite))
```
Finally, add `SessionRecord`'s migration to your database's migrations. This will prepare your database for storing session data in the `_fluent_sessions` schema.
```swift
app.migrations.add(SessionRecord.migration)
```
Make sure to run your application's migrations after adding the new migration. Sessions will now be stored in your application's database allowing them to persist between restarts and be shared between multiple instances of your app.
### Redis
Redis provides support for storing session data in your configured Redis instance. This section assumes you have [configured Redis](../redis/overview.md) and can send commands to the Redis instance.
To use Redis for Sessions, select it when configuring your application:
```swift
import Redis
app.sessions.use(.redis)
```
This will configure sessions to use the Redis sessions driver with the default behavior.
!!! seealso
Refer to [Redis → Sessions](../redis/sessions.md) for more detailed information about Redis and Sessions.
## Session Data
Now that sessions are configured, you are ready to persist data between requests. New sessions are initialized automatically when data is added to `req.session`. The example route handler below accepts a dynamic route parameter and adds the value to `req.session.data`.
```swift
app.get("set", ":value") { req -> HTTPStatus in
req.session.data["name"] = req.parameters.get("value")
return .ok
}
```
Use the following request to initialize a session with the name Vapor.
```http
GET /set/vapor HTTP/1.1
content-length: 0
```
You should receive a response similar to the following:
```http
HTTP/1.1 200 OK
content-length: 0
set-cookie: vapor-session=123; Expires=Fri, 10 Apr 2020 21:08:09 GMT; Path=/
```
Notice the `set-cookie` header has been added automatically to the response after adding data to `req.session`. Including this cookie in subsequent requests will allow access to the session data.
Add the following route handler for accessing the name value from the session.
```swift
app.get("get") { req -> String in
req.session.data["name"] ?? "n/a"
}
```
Use the following request to access this route while making sure to pass the cookie value from the previous response.
```http
GET /get HTTP/1.1
cookie: vapor-session=123
```
You should see the name Vapor returned in the response. You can add or remove data from the session as you see fit. Session data will be synchronized with the session driver automatically before returning the HTTP response.
To end a session, use `req.session.destroy`. This will delete the data from the session driver and invalidate the session cookie.
```swift
app.get("del") { req -> HTTPStatus in
req.session.destroy()
return .ok
}
```
# Services
Vapor's `Application` and `Request` are built to be extended by your application and third-party packages. New functionality added to these types are often called services.
## Read Only
The simplest type of service is read-only. These services consist of computed variables or methods added to either application or request.
```swift
import Vapor
struct MyAPI {
let client: Client
func foos() async throws -> [String] { ... }
}
extension Request {
var myAPI: MyAPI {
.init(client: self.client)
}
}
```
Read-only services can depend on any pre-existing services, like `client` in this example. Once the extension has been added, your custom service can be used like any other property on request.
```swift
req.myAPI.foos()
```
## Writable
Services that need state or configuration can utilize `Application` and `Request` storage for storing data. Let's assume you want to add the following `MyConfiguration` struct to your application.
```swift
struct MyConfiguration {
var apiKey: String
}
```
To use storage, you must declare a `StorageKey`.
```swift
struct MyConfigurationKey: StorageKey {
typealias Value = MyConfiguration
}
```
This is an empty struct with a `Value` typealias specifying which type is being stored. By using an empty type as the key, you can control what code is able to access your storage value. If the type is internal or private, only your code will be able to modify the associated value in storage.
Finally, add an extension to `Application` for getting and setting the `MyConfiguration` struct.
```swift
extension Application {
var myConfiguration: MyConfiguration? {
get {
self.storage[MyConfigurationKey.self]
}
set {
self.storage[MyConfigurationKey.self] = newValue
}
}
}
```
Once the extension is added, you can use `myConfiguration` like a normal property on `Application`.
```swift
app.myConfiguration = .init(apiKey: ...)
print(app.myConfiguration?.apiKey)
```
## Lifecycle
Vapor's `Application` allows you to register lifecycle handlers. These let you hook into events such as boot and shutdown.
```swift
// Prints hello during boot.
struct Hello: LifecycleHandler {
// Called before application boots.
func willBoot(_ app: Application) throws {
app.logger.info("Hello!")
}
// Called after application boots.
func didBoot(_ app: Application) throws {
app.logger.info("Server is running")
}
// Called before application shutdown.
func shutdown(_ app: Application) {
app.logger.info("Goodbye!")
}
}
// Add lifecycle handler.
app.lifecycle.use(Hello())
```
## Locks
Vapor's `Application` includes conveniences for synchronizing code using locks. By declaring a `LockKey`, you can get a unique, shared lock to synchronize access to your code.
```swift
struct TestKey: LockKey { }
let test = app.locks.lock(for: TestKey.self)
test.withLock {
// Do something.
}
```
Each call to `lock(for:)` with the same `LockKey` will return the same lock. This method is thread-safe.
For an application-wide lock, you can use `app.sync`.
```swift
app.sync.withLock {
// Do something.
}
```
## Request
Services that are intended to be used in route handlers should be added to `Request`. Request services should use the request's logger and event loop. It is important that a request stay on the same event loop or an assertion will be hit when the response is returned to Vapor.
If a service must leave the request's event loop to do work, it should make sure to return to the event loop before finishing. This can be done using the `hop(to:)` on `EventLoopFuture`.
Request services that need access to application services, such as configurations, can use `req.application`. Take care to consider thread-safety when accessing the application from a route handler. Generally, only read operations should be performed by requests. Write operations must be protected by locks.
# Request
The [`Request`](https://api.vapor.codes/vapor/request) object is passed into every [route handler](../basics/routing.md).
```swift
app.get("hello", ":name") { req -> String in
let name = req.parameters.get("name")!
return "Hello, \(name)!"
}
```
It is the main window into the rest of Vapor's functionality. It contains APIs for the [request body](../basics/content.md), [query parameters](../basics/content.md#query), [logger](../basics/logging.md), [HTTP client](../basics/client.md), [Authenticator](../security/authentication.md), and more. Accessing this functionality through the request keeps computation on the correct event loop and allows it to be mocked for testing. You can even add your own [services](../advanced/services.md) to the `Request` with extensions.
The full API documentation for `Request` can be found [here](https://api.vapor.codes/vapor/request).
## Application
The `Request.application` property holds a reference to the [`Application`](https://api.vapor.codes/vapor/application). This object contains all of the configuration and core functionality for the application. Most of it should only be set in `configure.swift`, before the application fully starts, and many of the lower level APIs won't be needed in most applications. One of the most useful properties is `Application.eventLoopGroup`, which can be used to get an `EventLoop` for processes that need a new one via the `any()` method. It also contains the [`Environment`](../basics/environment.md).
## Body
If you want direct access to the request body as a `ByteBuffer`, you can use `Request.body.data`. This can be used for streaming data from the request body to a file (though you should use the [`fileio`](../advanced/files.md) property on the request for this instead) or to another HTTP client.
## Cookies
While the most useful application of cookies is via built-in [sessions](../advanced/sessions.md#configuration), you can also access cookies directly via `Request.cookies`.
```swift
app.get("my-cookie") { req -> String in
guard let cookie = req.cookies["my-cookie"] else {
throw Abort(.badRequest)
}
if let expiration = cookie.expires, expiration < Date() {
throw Abort(.badRequest)
}
return cookie.string
}
```
## Headers
An `HTTPHeaders` object can be accessed at `Request.headers`. This contains all of the headers sent with the request. It can be used to access the `Content-Type` header, for example.
```swift
app.get("json") { req -> String in
guard let contentType = req.headers.contentType, contentType == .json else {
throw Abort(.badRequest)
}
return "JSON"
}
```
See further documentation for `HTTPHeaders` [here](https://swiftpackageindex.com/apple/swift-nio/2.56.0/documentation/niohttp1/httpheaders). Vapor also adds several extensions to `HTTPHeaders` to make working with the most commonly-used headers easier; a list is available [here](https://api.vapor.codes/vapor/niohttp1/httpheaders#instance-properties)
## IP Address
The `SocketAddress` representing the client can be accessed via `Request.remoteAddress`, which may be useful for logging or rate limiting using the string representation `Request.remoteAddress.ipAddress`. It may not accurately represent the client's IP address if the application is behind a reverse proxy.
```swift
app.get("ip") { req -> String in
return req.remoteAddress.ipAddress
}
```
See further documentation for `SocketAddress` [here](https://swiftpackageindex.com/apple/swift-nio/2.56.0/documentation/niocore/socketaddress).
# APNS
Vapor's Apple Push Notification Service (APNS) API makes it easy to authenticate and send push notifications to Apple devices. It's built on top of [APNSwift](https://github.com/swift-server-community/APNSwift).
## Getting Started
Let's take a look at how you can get started using APNS.
### Package
The first step to using APNS is adding the package to your dependencies.
```swift
// swift-tools-version:5.8
import PackageDescription
let package = Package(
name: "my-app",
dependencies: [
// Other dependencies...
.package(url: "https://github.com/vapor/apns.git", from: "4.0.0"),
],
targets: [
.target(name: "App", dependencies: [
// Other dependencies...
.product(name: "VaporAPNS", package: "apns")
]),
// Other targets...
]
)
```
If you edit the manifest directly inside Xcode, it will automatically pick up the changes and fetch the new dependency when the file is saved. Otherwise, from Terminal, run `swift package resolve` to fetch the new dependency.
### Configuration
The APNS module adds a new property `apns` to `Application`. To send push notifications, you will need to set the `configuration` property with your credentials.
```swift
import APNS
import VaporAPNS
import APNSCore
// Configure APNS using JWT authentication.
let apnsConfig = APNSClientConfiguration(
authenticationMethod: .jwt(
privateKey: try .loadFrom(string: "<#key.p8 content#>"),
keyIdentifier: "<#key identifier#>",
teamIdentifier: "<#team identifier#>"
),
environment: .development
)
app.apns.containers.use(
apnsConfig,
eventLoopGroupProvider: .shared(app.eventLoopGroup),
responseDecoder: JSONDecoder(),
requestEncoder: JSONEncoder(),
as: .default
)
```
Fill in the placeholders with your credentials. The above example shows [JWT-based auth](https://developer.apple.com/documentation/usernotifications/establishing-a-token-based-connection-to-apns) using the `.p8` key you get from Apple's developer portal. For [TLS-based auth](https://developer.apple.com/documentation/usernotifications/establishing-a-certificate-based-connection-to-apns) with a certificate, use the `.tls` authentication method:
```swift
authenticationMethod: .tls(
privateKeyPath: <#path to private key#>,
pemPath: <#path to pem file#>,
pemPassword: <#optional pem password#>
)
```
### Send
Once APNS is configured, you can send push notifications using `apns.send` method on `Application` or `Request`.
```swift
// Custom Codable Payload
struct Payload: Codable {
let acme1: String
let acme2: Int
}
// Create push notification Alert
let dt = "70075697aa918ebddd64efb165f5b9cb92ce095f1c4c76d995b384c623a258bb"
let payload = Payload(acme1: "hey", acme2: 2)
let alert = APNSAlertNotification(
alert: .init(
title: .raw("Hello"),
subtitle: .raw("This is a test from vapor/apns")
),
expiration: .immediately,
priority: .immediately,
topic: "<#my topic#>",
payload: payload
)
// Send the notification
try! await req.apns.client.sendAlertNotification(
alert,
deviceToken: dt,
deadline: .distantFuture
)
```
Use `req.apns` whenever you are inside of a route handler.
```swift
// Sends a push notification.
app.get("test-push") { req async throws -> HTTPStatus in
try await req.apns.client.send(...)
return .ok
}
```
The first parameter accepts the push notification alert and the second parameter is the target device token.
## Alert
`APNSAlertNotification` is the actual metadata of the push notification alert to send. More details on the specifics of each property are provided [here](https://developer.apple.com/library/archive/documentation/NetworkingInternet/Conceptual/RemoteNotificationsPG/PayloadKeyReference.html). They follow a one-to-one naming scheme listed in Apple's documentation.
```swift
let alert = APNSAlertNotification(
alert: .init(
title: .raw("Hello"),
subtitle: .raw("This is a test from vapor/apns")
),
expiration: .immediately,
priority: .immediately,
topic: "<#my topic#>",
payload: payload
)
```
This type can be passed directly to the `send` method.
### Custom Notification Data
Apple provides engineers with the ability to add custom payload data to each notification. In order to facilitate this we accept `Codable` conformance to the payload parameter on all `send` apis.
```swift
// Custom Codable Payload
struct Payload: Codable {
let acme1: String
let acme2: Int
}
```
## More Information
For more information on available methods, see [APNSwift's README](https://github.com/swift-server-community/APNSwift).
# Tracing
Tracing is a powerful tool for monitoring and debugging distributed systems. Vapor's tracing API allows developers to easily track request lifecycles, propagate metadata, and integrate with popular backends like OpenTelemetry.
Vapor's tracing API is built on top of [swift-distributed-tracing](https://github.com/apple/swift-distributed-tracing), which means it is compatible with all of swift-distributed-tracing's [backend implementations](https://github.com/apple/swift-distributed-tracing/blob/main/README.md#tracing-backends).
If you are unfamiliar with tracing and spans in Swift, review the [OpenTelemetry Trace documentation](https://opentelemetry.io/docs/concepts/signals/traces/) and [swift-distributed-tracing documentation](https://swiftpackageindex.com/apple/swift-distributed-tracing/main/documentation/tracing).
## TracingMiddleware
To automatically create a fully annotated span for each request, add the `TracingMiddleware` to your application.
```swift
app.middleware.use(TracingMiddleware())
```
To get accurate span measurements and ensure that tracing identifiers are passed along correctly to other services, add this middleware before other middlewares.
## Adding Spans
When adding spans to route handlers, it's ideal for them to be associated with the top-level request span. This is referred to as "span propagation" and can be handled in two different ways: automatic or manual.
### Automatic Propagation
Vapor has support to automatically propagate spans between middleware and route callbacks. To do so, set the `Application.traceAutoPropagation` property to true during configuration.
```swift
app.traceAutoPropagation = true
```
!!! note
Enabling auto-propagation may degrade performance on high-throughput APIs with minimal tracing needs, since request span metadata must be restored for every route handler regardless of whether spans are created.
Then spans may be created in the route closure using the ordinary distributed tracing syntax.
```swift
app.get("fetchAndProcess") { req in
let result = try await fetch()
return try await withSpan("getNameParameter") { _ in
try await process(result)
}
}
```
### Manual Propagation
To avoid the performance implications of automatic propagation, you may manually restore span metadata where necessary. `TracingMiddleware` automatically sets a `Request.serviceContext` property which may be used directly in `withSpan`'s `context` parameter.
```swift
app.get("fetchAndProcess") { req in
let result = try await fetch()
return try await withSpan("getNameParameter", context: req.serviceContext) { _ in
try await process(result)
}
}
```
To restore the span metadata without creating a span, use `ServiceContext.withValue`. This is valuable if you know that downstream async libraries emit their own tracing spans, and those should be nested underneath the parent request span.
```swift
app.get("fetchAndProcess") { req in
try await ServiceContext.withValue(req.serviceContext) {
try await fetch()
return try await process(result)
}
}
```
## NIO Considerations
Because `swift-distributed-tracing` uses [`TaskLocal properties`](https://developer.apple.com/documentation/swift/tasklocal) to propagate, you must manually re-restore the context whenever you cross `NIO EventLoopFuture` boundaries to ensure spans are linked correctly. **This is necessary regardless of whether automatic propagation is enabled**.
```swift
app.get("fetchAndProcessNIO") { req in
withSpan("fetch", context: req.serviceContext) { span in
fetchSomething().map { result in
withSpan("process", context: span.context) { _ in
process(result)
}
}
}
}
```
# Authentication
Authentication is the act of verifying a user's identity. This is done through the verification of credentials like a username and password or unique token. Authentication (sometimes called auth/c) is distinct from authorization (auth/z) which is the act of verifying a previously authenticated user's permissions to perform certain tasks.
## Introduction
Vapor's Authentication API provides support for authenticating a user via the `Authorization` header, using [Basic](https://tools.ietf.org/html/rfc7617) and [Bearer](https://tools.ietf.org/html/rfc6750). It also supports authenticating a user via the data decoded from the [Content](../basics/content.md) API.
Authentication is implemented by creating an `Authenticator` which contains the verification logic. An authenticator can be used to protect individual route groups or an entire app. The following authenticator helpers ship with Vapor:
|Protocol|Description|
|-|-|
|`RequestAuthenticator`/`AsyncRequestAuthenticator`|Base authenticator capable of creating middleware.|
|[`BasicAuthenticator`/`AsyncBasicAuthenticator`](#basic)|Authenticates Basic authorization header.|
|[`BearerAuthenticator`/`AsyncBearerAuthenticator`](#bearer)|Authenticates Bearer authorization header.|
|`CredentialsAuthenticator`/`AsyncCredentialsAuthenticator`|Authenticates a credentials payload from the request body.|
If authentication is successful, the authenticator adds the verified user to `req.auth`. This user can then be accessed using `req.auth.get(_:)` in routes protected by the authenticator. If authentication fails, the user is not added to `req.auth` and any attempts to access it will fail.
## Authenticatable
To use the Authentication API, you first need a user type that conforms to `Authenticatable`. This can be a `struct`, `class`, or even a Fluent `Model`. The following examples assume this simple `User` struct that has one property: `name`.
```swift
import Vapor
struct User: Authenticatable {
var name: String
}
```
Each example below will use an instance of an authenticator which we created. In these examples, we've called it `UserAuthenticator`.
### Route
Authenticators are middleware and can be used for protecting routes.
```swift
let protected = app.grouped(UserAuthenticator())
protected.get("me") { req -> String in
try req.auth.require(User.self).name
}
```
`req.auth.require` is used to fetch the authenticated `User`. If authentication failed, this method will throw an error, protecting the route.
### Guard Middleware
You can also use `GuardMiddleware` in your route group to ensure that a user has been authenticated before reaching your route handler.
```swift
let protected = app.grouped(UserAuthenticator())
.grouped(User.guardMiddleware())
```
Requiring authentication is not done by the authenticator middleware to allow for composition of authenticators. Read more about [composition](#composition) below.
## Basic
Basic authentication sends a username and password in the `Authorization` header. The username and password are concatenated with a colon (e.g. `test:secret`), base-64 encoded, and prefixed with `"Basic "`. The following example request encodes the username `test` with password `secret`.
```http
GET /me HTTP/1.1
Authorization: Basic dGVzdDpzZWNyZXQ=
```
Basic authentication is typically used once to log a user in and generate a token. This minimizes how frequently the user's sensitive password must be sent. You should never send Basic authorization over a plaintext or unverified TLS connection.
To implement Basic authentication in your app, create a new authenticator conforming to `BasicAuthenticator`. Below is an example authenticator hard-coded to verify the request from above.
```swift
import Vapor
struct UserAuthenticator: BasicAuthenticator {
typealias User = App.User
func authenticate(
basic: BasicAuthorization,
for request: Request
) -> EventLoopFuture {
if basic.username == "test" && basic.password == "secret" {
request.auth.login(User(name: "Vapor"))
}
return request.eventLoop.makeSucceededFuture(())
}
}
```
If you're using `async`/`await` you can use `AsyncBasicAuthenticator` instead:
```swift
import Vapor
struct UserAuthenticator: AsyncBasicAuthenticator {
typealias User = App.User
func authenticate(
basic: BasicAuthorization,
for request: Request
) async throws {
if basic.username == "test" && basic.password == "secret" {
request.auth.login(User(name: "Vapor"))
}
}
}
```
This protocol requires you to implement `authenticate(basic:for:)` which will be called when an incoming request contains the `Authorization: Basic ...` header. A `BasicAuthorization` struct containing the username and password is passed to the method.
In this test authenticator, the username and password are tested against hard-coded values. In a real authenticator, you might check against a database or external API. This is why the `authenticate` method allows you to return a future.
!!! tip
Passwords should never be stored in a database as plaintext. Always use password hashes for comparison.
If the authentication parameters are correct, in this case matching the hard-coded values, a `User` named Vapor is logged in. If the authentication parameters do not match, no user is logged in, which signifies authentication failed.
If you add this authenticator to your app, and test the route defined above, you should see the name `"Vapor"` returned for a successful login. If the credentials are not correct, you should see a `401 Unauthorized` error.
## Bearer
Bearer authentication sends a token in the `Authorization` header. The token is prefixed with `"Bearer "`. The following example request sends the token `foo`.
```http
GET /me HTTP/1.1
Authorization: Bearer foo
```
Bearer authentication is commonly used for authentication of API endpoints. The user typically requests a Bearer token by sending credentials like a username and password to a login endpoint. This token may last minutes or days depending on the application's needs.
As long as the token is valid, the user can use it in place of his or her credentials to authenticate against the API. If the token becomes invalid, a new one can be generated using the login endpoint.
To implement Bearer authentication in your app, create a new authenticator conforming to `BearerAuthenticator`. Below is an example authenticator hard-coded to verify the request from above.
```swift
import Vapor
struct UserAuthenticator: BearerAuthenticator {
typealias User = App.User
func authenticate(
bearer: BearerAuthorization,
for request: Request
) -> EventLoopFuture {
if bearer.token == "foo" {
request.auth.login(User(name: "Vapor"))
}
return request.eventLoop.makeSucceededFuture(())
}
}
```
If you're using `async`/`await` you can use `AsyncBearerAuthenticator` instead:
```swift
import Vapor
struct UserAuthenticator: AsyncBearerAuthenticator {
typealias User = App.User
func authenticate(
bearer: BearerAuthorization,
for request: Request
) async throws {
if bearer.token == "foo" {
request.auth.login(User(name: "Vapor"))
}
}
}
```
This protocol requires you to implement `authenticate(bearer:for:)` which will be called when an incoming request contains the `Authorization: Bearer ...` header. A `BearerAuthorization` struct containing the token is passed to the method.
In this test authenticator, the token is tested against a hard-coded value. In a real authenticator, you might verify the token by checking against a database or using cryptographic measures, like is done with JWT. This is why the `authenticate` method allows you to return a future.
!!! tip
When implementing token verification, it's important to consider horizontal scalability. If your application needs to handle many users concurrently, authentication can be a potential bottleneck. Consider how your design will scale across multiple instances of your application running at once.
If the authentication parameters are correct, in this case matching the hard-coded value, a `User` named Vapor is logged in. If the authentication parameters do not match, no user is logged in, which signifies authentication failed.
If you add this authenticator to your app, and test the route defined above, you should see the name `"Vapor"` returned for a successful login. If the credentials are not correct, you should see a `401 Unauthorized` error.
## Composition
Multiple authenticators can be composed (combined together) to create more complex endpoint authentication. Since an authenticator middleware will not reject the request if authentication fails, more than one of these middleware can be chained together. Authenticators can be composed in two key ways.
### Composing Methods
The first method of authentication composition is chaining more than one authenticator for the same user type. Take the following example:
```swift
app.grouped(UserPasswordAuthenticator())
.grouped(UserTokenAuthenticator())
.grouped(User.guardMiddleware())
.post("login")
{ req in
let user = try req.auth.require(User.self)
// Do something with user.
}
```
This example assumes two authenticators `UserPasswordAuthenticator` and `UserTokenAuthenticator` that both authenticate `User`. Both of these authenticators are added to the route group. Finally, `GuardMiddleware` is added after the authenticators to require that `User` was successfully authenticated.
This composition of authenticators results in a route that can be accessed by either password or token. Such a route could allow a user to login and generate a token, then continue to use that token to generate new tokens.
### Composing Users
The second method of authentication composition is chaining authenticators for different user types. Take the following example:
```swift
app.grouped(AdminAuthenticator())
.grouped(UserAuthenticator())
.get("secure")
{ req in
guard req.auth.has(Admin.self) || req.auth.has(User.self) else {
throw Abort(.unauthorized)
}
// Do something.
}
```
This example assumes two authenticators `AdminAuthenticator` and `UserAuthenticator` that authenticate `Admin` and `User`, respectively. Both of these authenticators are added to the route group. Instead of using `GuardMiddleware`, a check in the route handler is added to see if either `Admin` or `User` were authenticated. If not, an error is thrown.
This composition of authenticators results in a route that can be accessed by two different types of users with potentially different methods of authentication. Such a route could allow for normal user authentication while still giving access to a super-user.
## Manual
You can also handle authentication manually using `req.auth`. This is especially useful for testing.
To manually log a user in, use `req.auth.login(_:)`. Any `Authenticatable` user can be passed to this method.
```swift
req.auth.login(User(name: "Vapor"))
```
To get the authenticated user, use `req.auth.require(_:)`
```swift
let user: User = try req.auth.require(User.self)
print(user.name) // String
```
You can also use `req.auth.get(_:)` if you don't want to automatically throw an error when authentication fails.
```swift
let user = req.auth.get(User.self)
print(user?.name) // String?
```
To unauthenticate a user, pass the user type to `req.auth.logout(_:)`.
```swift
req.auth.logout(User.self)
```
## Fluent
[Fluent](../fluent/overview.md) defines two protocols `ModelAuthenticatable` and `ModelTokenAuthenticatable` which can be added to your existing models. Conforming your models to these protocols allows for the creation of authenticators for protecting endpoints.
`ModelTokenAuthenticatable` authenticates with a Bearer token. This is what you use to protect most of your endpoints. `ModelAuthenticatable` authenticates with username and password and is used by a single endpoint for generating tokens.
This guide assumes you are familiar with Fluent and have successfully configured your app to use a database. If you are new to Fluent, start with the [overview](../fluent/overview.md).
### User
To start, you will need a model representing the user that will be authenticated. For this guide, we'll be using the following model, but you are free to use an existing model.
```swift
import Fluent
import Vapor
final class User: Model, Content {
static let schema = "users"
@ID(key: .id)
var id: UUID?
@Field(key: "name")
var name: String
@Field(key: "email")
var email: String
@Field(key: "password_hash")
var passwordHash: String
init() { }
init(id: UUID? = nil, name: String, email: String, passwordHash: String) {
self.id = id
self.name = name
self.email = email
self.passwordHash = passwordHash
}
}
```
The model must be able to store a username, in this case an email, and a password hash. We also set `email` to be a unique field, to avoid duplicate users. The corresponding migration for this example model is here:
```swift
import Fluent
import Vapor
extension User {
struct Migration: AsyncMigration {
var name: String { "CreateUser" }
func prepare(on database: Database) async throws {
try await database.schema("users")
.id()
.field("name", .string, .required)
.field("email", .string, .required)
.field("password_hash", .string, .required)
.unique(on: "email")
.create()
}
func revert(on database: Database) async throws {
try await database.schema("users").delete()
}
}
}
```
Don't forget to add the migration to `app.migrations`.
```swift
app.migrations.add(User.Migration())
```
!!! tip
Because email addresses are not case sensitive, you may want to add a [`Middleware`](../fluent/model.md#lifecycle) that coerces the email address to lowercase before saving it to the database. Be aware, though, that `ModelAuthenticatable` uses a case sensitive comparison, so if you do this you'll want to make sure the user's input is all lower case, either with case coercion in the client, or with a custom authenticator.
The first thing you will need is an endpoint to create new users. Let's use `POST /users`. Create a [Content](../basics/content.md) struct representing the data this endpoint expects.
```swift
import Vapor
extension User {
struct Create: Content {
var name: String
var email: String
var password: String
var confirmPassword: String
}
}
```
If you like, you can conform this struct to [Validatable](../basics/validation.md) to add validation requirements.
```swift
import Vapor
extension User.Create: Validatable {
static func validations(_ validations: inout Validations) {
validations.add("name", as: String.self, is: !.empty)
validations.add("email", as: String.self, is: .email)
validations.add("password", as: String.self, is: .count(8...))
}
}
```
Now you can create the `POST /users` endpoint.
```swift
app.post("users") { req async throws -> User in
try User.Create.validate(content: req)
let create = try req.content.decode(User.Create.self)
guard create.password == create.confirmPassword else {
throw Abort(.badRequest, reason: "Passwords did not match")
}
let user = try User(
name: create.name,
email: create.email,
passwordHash: Bcrypt.hash(create.password)
)
try await user.save(on: req.db)
return user
}
```
This endpoint validates the incoming request, decodes the `User.Create` struct, and checks that the passwords match. It then uses the decoded data to create a new `User` and saves it to the database. The plaintext password is hashed using `Bcrypt` before saving to the database.
Build and run the project, making sure to migrate the database first, then use the following request to create a new user.
```http
POST /users HTTP/1.1
Content-Length: 97
Content-Type: application/json
{
"name": "Vapor",
"email": "test@vapor.codes",
"password": "secret42",
"confirmPassword": "secret42"
}
```
#### Model Authenticatable
Now that you have a user model and an endpoint to create new users, let's conform the model to `ModelAuthenticatable`. This will allow for the model to be authenticated using username and password.
```swift
import Fluent
import Vapor
extension User: ModelAuthenticatable {
static let usernameKey = \User.$email
static let passwordHashKey = \User.$passwordHash
func verify(password: String) throws -> Bool {
try Bcrypt.verify(password, created: self.passwordHash)
}
}
```
This extension adds `ModelAuthenticatable` conformance to `User`. The first two properties specify which fields should be used for storing the username and password hash respectively. The `\` notation creates a key path to the fields that Fluent can use to access them.
The last requirement is a method for verifying plaintext passwords sent in the Basic authentication header. Since we're using Bcrypt to hash the password during signup, we'll use Bcrypt to verify that the supplied password matches the stored password hash.
Now that the `User` conforms to `ModelAuthenticatable`, we can create an authenticator for protecting the login route.
```swift
let passwordProtected = app.grouped(User.authenticator())
passwordProtected.post("login") { req -> User in
try req.auth.require(User.self)
}
```
`ModelAuthenticatable` adds a static method `authenticator` for creating an authenticator.
Test that this route works by sending the following request.
```http
POST /login HTTP/1.1
Authorization: Basic dGVzdEB2YXBvci5jb2RlczpzZWNyZXQ0Mg==
```
This request passes the username `test@vapor.codes` and password `secret42` via the Basic authentication header. You should see the previously created user returned.
While you could theoretically use Basic authentication to protect all of your endpoints, it's recommended to use a separate token instead. This minimizes how often you must send the user's sensitive password over the Internet. It also makes authentication much faster since you only need to perform password hashing during login.
### User Token
Create a new model for representing user tokens.
```swift
import Fluent
import Vapor
final class UserToken: Model, Content {
static let schema = "user_tokens"
@ID(key: .id)
var id: UUID?
@Field(key: "value")
var value: String
@Parent(key: "user_id")
var user: User
init() { }
init(id: UUID? = nil, value: String, userID: User.IDValue) {
self.id = id
self.value = value
self.$user.id = userID
}
}
```
This model must have a `value` field for storing the token's unique string. It must also have a [parent-relation](../fluent/overview.md#parent) to the user model. You may add additional properties to this token as you see fit, such as an expiration date.
Next, create a migration for this model.
```swift
import Fluent
extension UserToken {
struct Migration: AsyncMigration {
var name: String { "CreateUserToken" }
func prepare(on database: Database) async throws {
try await database.schema("user_tokens")
.id()
.field("value", .string, .required)
.field("user_id", .uuid, .required, .references("users", "id"))
.unique(on: "value")
.create()
}
func revert(on database: Database) async throws {
try await database.schema("user_tokens").delete()
}
}
}
```
Notice that this migration makes the `value` field unique. It also creates a foreign key reference between the `user_id` field and the users table.
Don't forget to add the migration to `app.migrations`.
```swift
app.migrations.add(UserToken.Migration())
```
Finally, add a method on `User` for generating a new token. This method will be used during login.
```swift
extension User {
func generateToken() throws -> UserToken {
try .init(
value: [UInt8].random(count: 16).base64,
userID: self.requireID()
)
}
}
```
Here we're using `[UInt8].random(count:)` to generate a random token value. For this example, 16 bytes, or 128 bits, of random data are being used. You can adjust this number as you see fit. The random data is then base-64 encoded to make it easy to transmit in HTTP headers.
Now that you can generate user tokens, update the `POST /login` route to create and return a token.
```swift
let passwordProtected = app.grouped(User.authenticator())
passwordProtected.post("login") { req async throws -> UserToken in
let user = try req.auth.require(User.self)
let token = try user.generateToken()
try await token.save(on: req.db)
return token
}
```
Test that this route works by using the same login request from above. You should now get a token upon logging in that looks something like:
```
8gtg300Jwdhc/Ffw784EXA==
```
Hold onto the token you get as we'll use it shortly.
#### Model Token Authenticatable
Conform `UserToken` to `ModelTokenAuthenticatable`. This will allow for tokens to authenticate your `User` model.
```swift
import Vapor
import Fluent
extension UserToken: ModelTokenAuthenticatable {
static var valueKey: KeyPath> { \.$value }
static var userKey: KeyPath> { \.$user }
var isValid: Bool {
true
}
}
```
The first protocol requirement specifies which field stores the token's unique value. This is the value that will be sent in the Bearer authentication header. The second requirement specifies the parent-relation to the `User` model. This is how Fluent will look up the authenticated user.
The final requirement is an `isValid` boolean. If this is `false`, the token will be deleted from the database and the user will not be authenticated. For simplicity, we'll make the tokens eternal by hard-coding this to `true`.
Now that the token conforms to `ModelTokenAuthenticatable`, you can create an authenticator for protecting routes.
Create a new endpoint `GET /me` for getting the currently authenticated user.
```swift
let tokenProtected = app.grouped(UserToken.authenticator())
tokenProtected.get("me") { req -> User in
try req.auth.require(User.self)
}
```
Similar to `User`, `UserToken` now has a static `authenticator()` method that can generate an authenticator. The authenticator will attempt to find a matching `UserToken` using the value provided in the Bearer authentication header. If it finds a match, it will fetch the related `User` and authenticate it.
Test that this route works by sending the following HTTP request where the token is the value you saved from the `POST /login` request.
```http
GET /me HTTP/1.1
Authorization: Bearer
```
You should see the authenticated `User` returned.
## Session
Vapor's [Session API](../advanced/sessions.md) can be used to automatically persist user authentication between requests. This works by storing a unique identifier for the user in the request's session data after successful login. On subsequent requests, the user's identifier is fetched from the session and used to authenticate the user before calling your route handler.
Sessions are great for front-end web applications built in Vapor that serve HTML directly to web browsers. For APIs, we recommend using stateless, token-based authentication to persist user data between requests.
### Session Authenticatable
To use session-based authentication, you will need a type that conforms to `SessionAuthenticatable`. For this example, we'll use a simple struct.
```swift
import Vapor
struct User {
var email: String
}
```
To conform to `SessionAuthenticatable`, you will need to specify a `sessionID`. This is the value that will be stored in the session data and must uniquely identify the user.
```swift
extension User: SessionAuthenticatable {
var sessionID: String {
self.email
}
}
```
For our simple `User` type, we'll use the email address as the unique session identifier.
### Session Authenticator
Next, we'll need a `SessionAuthenticator` to handle resolving instances of our User from the persisted session identifier.
```swift
struct UserSessionAuthenticator: SessionAuthenticator {
typealias User = App.User
func authenticate(sessionID: String, for request: Request) -> EventLoopFuture {
let user = User(email: sessionID)
request.auth.login(user)
return request.eventLoop.makeSucceededFuture(())
}
}
```
If you're using `async`/`await` you can use the `AsyncSessionAuthenticator`:
```swift
struct UserSessionAuthenticator: AsyncSessionAuthenticator {
typealias User = App.User
func authenticate(sessionID: String, for request: Request) async throws {
let user = User(email: sessionID)
request.auth.login(user)
}
}
```
Since all the information we need to initialize our example `User` is contained in the session identifier, we can create and login the user synchronously. In a real-world application, you would likely use the session identifier to perform a database lookup or API request to fetch the rest of the user data before authenticating.
Next, let's create a simple bearer authenticator to perform the initial authentication.
```swift
struct UserBearerAuthenticator: AsyncBearerAuthenticator {
func authenticate(bearer: BearerAuthorization, for request: Request) async throws {
if bearer.token == "test" {
let user = User(email: "hello@vapor.codes")
request.auth.login(user)
}
}
}
```
This authenticator will authenticate a user with the email `hello@vapor.codes` when the bearer token `test` is sent.
Finally, let's combine all these pieces together in your application.
```swift
// Create protected route group which requires user auth.
let protected = app.routes.grouped([
app.sessions.middleware,
UserSessionAuthenticator(),
UserBearerAuthenticator(),
User.guardMiddleware(),
])
// Add GET /me route for reading user's email.
protected.get("me") { req -> String in
try req.auth.require(User.self).email
}
```
`SessionsMiddleware` is added first to enable session support on the application. More information about configuring sessions can be found in the [Session API](../advanced/sessions.md) section.
Next, the `SessionAuthenticator` is added. This handles authenticating the user if a session is active.
If the authentication has not been persisted in the session yet, the request will be forwarded to the next authenticator. `UserBearerAuthenticator` will check the bearer token and authenticate the user if it equals `"test"`.
Finally, `User.guardMiddleware()` will ensure that `User` has been authenticated by one of the previous middleware. If the user has not been authenticated, an error will be thrown.
To test this route, first send the following request:
```http
GET /me HTTP/1.1
authorization: Bearer test
```
This will cause `UserBearerAuthenticator` to authenticate the user. Once authenticated, `UserSessionAuthenticator` will persist the user's identifier in session storage and generate a cookie. Use the cookie from the response in a second request to the route.
```http
GET /me HTTP/1.1
cookie: vapor_session=123
```
This time, `UserSessionAuthenticator` will authenticate the user and you should again see the user's email returned.
### Model Session Authenticatable
Fluent models can generate `SessionAuthenticator`s by conforming to `ModelSessionAuthenticatable`. This will use the model's unique identifier as the session identifier and automatically perform a database lookup to restore the model from the session.
```swift
import Fluent
final class User: Model { ... }
// Allow this model to be persisted in sessions.
extension User: ModelSessionAuthenticatable { }
```
You can add `ModelSessionAuthenticatable` to any existing model as an empty conformance. Once added, a new static method will be available for creating a `SessionAuthenticator` for that model.
```swift
User.sessionAuthenticator()
```
This will use the application's default database for resolving the user. To specify a database, pass the identifier.
```swift
User.sessionAuthenticator(.sqlite)
```
## Website Authentication
Websites are a special case for authentication because the use of a browser restricts how you can attach credentials to a browser. This leads to two different authentication scenarios:
* the initial log in via a form
* subsequent calls authenticated with a session cookie
Vapor and Fluent provides several helpers to make this seamless.
### Session Authentication
Session authentication works as described above. You need to apply the session middleware and session authenticator to all routes that your user will access. These include any protected routes, any routes which are public but you may still want to access the user if they're logged in (to display an account button for instance) **and** login routes.
You can enable this globally in your app in **configure.swift** like so:
```swift
app.middleware.use(app.sessions.middleware)
app.middleware.use(User.sessionAuthenticator())
```
These middlewares do the following:
* the sessions middleware takes the session cookie provided in the request and converts it into a session
* the session authenticator takes the session and see if there is an authenticated user for that session. If so, the middleware authenticates the request. In the response, the session authenticator sees if the request has an authenticated user and saves them in the session so they're authenticated in the next request.
!!! note
The session cookie is not set to `secure` and `httpOnly` by default. Check Vapor's [Session API](../advanced/sessions.md#configuration) for more information on how to configure cookies.
### Protecting Routes
When protecting routes for an API, you traditionally return an HTTP response with a status code such as **401 Unauthorized** if the request is not authenticated. However, this isn't a very good user experience for someone using a browser. Vapor provides a `RedirectMiddleware` for any `Authenticatable` type to use in this scenario:
```swift
let protectedRoutes = app.grouped(User.redirectMiddleware(path: "/login?loginRequired=true"))
```
The `RedirectMiddleware` object also supports passing a closure that returns the redirect path as a `String` during creation for advanced url handling. For instance, including the path redirected from as query parameter to the redirect target for state management.
```swift
let redirectMiddleware = User.redirectMiddleware { req -> String in
return "/login?authRequired=true&next=\(req.url.path)"
}
```
This works similar to the `GuardMiddleware`. Any requests to routes registered to `protectedRoutes` that aren't authenticated will be redirected to the path provided. This allows you to tell your users to log in, rather than just providing a **401 Unauthorized**.
Be sure to include a Session Authenticator before the `RedirectMiddleware` to ensure the authenticated user is loaded before running through the `RedirectMiddleware`.
```swift
let protectedRoutes = app.grouped([User.sessionAuthenticator(), redirectMiddleware])
```
### Form Log In
To authenticate a user and future requests with a session, you need to log a user in. Vapor provides a `ModelCredentialsAuthenticatable` protocol to conform to. This handles log in via a form. First conform your `User` to this protocol:
```swift
extension User: ModelCredentialsAuthenticatable {
static let usernameKey = \User.$email
static let passwordHashKey = \User.$password
func verify(password: String) throws -> Bool {
try Bcrypt.verify(password, created: self.password)
}
}
```
This is identical to `ModelAuthenticatable` and if you already conform to that then you don't need to do anything else. Next apply this `ModelCredentialsAuthenticator` middleware to your log in form POST request:
```swift
let credentialsProtectedRoute = sessionRoutes.grouped(User.credentialsAuthenticator())
credentialsProtectedRoute.post("login", use: loginPostHandler)
```
This uses the default credentials authenticator to protect the login route. You must send `username` and `password` in the POST request. You can set your form up like so:
```html
```
The `CredentialsAuthenticator` extracts the `username` and `password` from the request body, finds the user from the username and verifies the password. If the password is valid, the middleware authenticates the request. The `SessionAuthenticator` then authenticates the session for subsequent requests.
## JWT
[JWT](jwt.md) provides a `JWTAuthenticator` that can be used to authenticate JSON Web Tokens in incoming requests. If you are new to JWT, check out the [overview](jwt.md).
First, create a type representing a JWT payload.
```swift
// Example JWT payload.
struct SessionToken: Content, Authenticatable, JWTPayload {
// Constants
let expirationTime: TimeInterval = 60 * 15
// Token Data
var expiration: ExpirationClaim
var userId: UUID
init(userId: UUID) {
self.userId = userId
self.expiration = ExpirationClaim(value: Date().addingTimeInterval(expirationTime))
}
init(with user: User) throws {
self.userId = try user.requireID()
self.expiration = ExpirationClaim(value: Date().addingTimeInterval(expirationTime))
}
func verify(using algorithm: some JWTAlgorithm) throws {
try expiration.verifyNotExpired()
}
}
```
Next, we can define a representation of the data contained in a successful login response. For now the response will only have one property which is a string representing a signed JWT.
```swift
struct ClientTokenResponse: Content {
var token: String
}
```
Using our model for the JWT token and response, we can use a password protected login route which returns a `ClientTokenResponse` and includes a signed `SessionToken`.
```swift
let passwordProtected = app.grouped(User.authenticator(), User.guardMiddleware())
passwordProtected.post("login") { req async throws -> ClientTokenResponse in
let user = try req.auth.require(User.self)
let payload = try SessionToken(with: user)
return ClientTokenResponse(token: try await req.jwt.sign(payload))
}
```
Alternatively, if you don't want to use an authenticator you can have something that looks like the following.
```swift
app.post("login") { req async throws -> ClientTokenResponse in
// Validate provided credential for user
// Get userId for provided user
let payload = try SessionToken(userId: userId)
return ClientTokenResponse(token: try await req.jwt.sign(payload))
}
```
By conforming the payload to `Authenticatable` and `JWTPayload`, you can generate a route authenticator using the `authenticator()` method. Add this to a route group to automatically fetch and verify the JWT before your route is called.
```swift
// Create a route group that requires the SessionToken JWT.
let secure = app.grouped(SessionToken.authenticator(), SessionToken.guardMiddleware())
```
Adding the optional [guard middleware](#guard-middleware) will require that authorization succeeded.
Inside the protected routes, you can access the authenticated JWT payload using `req.auth`.
```swift
// Return ok reponse if the user-provided token is valid.
secure.post("validateLoggedInUser") { req -> HTTPStatus in
let sessionToken = try req.auth.require(SessionToken.self)
print(sessionToken.userId)
return .ok
}
```
# Crypto
Vapor includes [SwiftCrypto](https://github.com/apple/swift-crypto/) which is a Linux-compatible port of Apple's CryptoKit library. Some additional crypto APIs are exposed for things SwiftCrypto does not have yet, like [Bcrypt](https://en.wikipedia.org/wiki/Bcrypt) and [TOTP](https://en.wikipedia.org/wiki/Time-based_One-time_Password_algorithm).
## SwiftCrypto
Swift's `Crypto` library implements Apple's CryptoKit API. As such, the [CryptoKit documentation](https://developer.apple.com/documentation/cryptokit) and the [WWDC talk](https://developer.apple.com/videos/play/wwdc2019/709) are great resources for learning the API.
These APIs will be available automatically when you import Vapor.
```swift
import Vapor
let digest = SHA256.hash(data: Data("hello".utf8))
print(digest)
```
CryptoKit includes support for:
- Hashing: `SHA512`, `SHA384`, `SHA256`
- Message Authentication Codes: `HMAC`
- Ciphers: `AES`, `ChaChaPoly`
- Public-Key Cryptography: `Curve25519`, `P521`, `P384`, `P256`
- Insecure hashing: `SHA1`, `MD5`
## Bcrypt
Bcrypt is a password hashing algorithm that uses a randomized salt to ensure hashing the same password multiple times doesn't result in the same digest.
Vapor provides a `Bcrypt` type for hashing and comparing passwords.
```swift
import Vapor
let digest = try Bcrypt.hash("test")
```
Because Bcrypt uses a salt, password hashes cannot be compared directly. Both the plaintext password and the existing digest must be verified together.
```swift
import Vapor
let pass = try Bcrypt.verify("test", created: digest)
if pass {
// Password and digest match.
} else {
// Wrong password.
}
```
Login with Bcrypt passwords can be implemented by first fetching the user's password digest from the database by email or username. The known digest can then be verified against the supplied plaintext password.
## OTP
Vapor supports both HOTP and TOTP one-time passwords. OTPs work with the SHA-1, SHA-256, and SHA-512 hash functions and can provide six, seven, or eight digits of output. An OTP provides authentication by generating a single-use human-readable password. To do so, parties first agree on a symmetric key, which must be kept private at all times to maintain the security of the generated passwords.
#### HOTP
HOTP is an OTP based on an HMAC signature. In addition to the symmetric key, both parties also agree on a counter, which is a number providing uniqueness for the password. After each generation attempt, the counter is increased.
```swift
let key = SymmetricKey(size: .bits128)
let hotp = HOTP(key: key, digest: .sha256, digits: .six)
let code = hotp.generate(counter: 25)
// Or using the static generate function
HOTP.generate(key: key, digest: .sha256, digits: .six, counter: 25)
```
#### TOTP
A TOTP is a time-based variation of the HOTP. It works mostly the same, but instead of a simple counter, the current time is used to generate uniqueness. To compensate for the inevitable skew introduced by unsynchronized clocks, network latency, user delay, and other confounding factors, a generated TOTP code remains valid over a specified time interval (most commonly, 30 seconds).
```swift
let key = SymmetricKey(size: .bits128)
let totp = TOTP(key: key, digest: .sha256, digits: .six, interval: 60)
let code = totp.generate(time: Date())
// Or using the static generate function
TOTP.generate(key: key, digest: .sha256, digits: .six, interval: 60, time: Date())
```
#### Range
OTPs are very useful for providing leeway in validation and out of sync counters. Both OTP implementations have the ability to generate an OTP with a margin for error.
```swift
let key = SymmetricKey(size: .bits128)
let hotp = HOTP(key: key, digest: .sha256, digits: .six)
// Generate a window of correct counters
let codes = hotp.generate(counter: 25, range: 2)
```
The example above allows for a margin of 2, which means the HOTP will be calculated for the counter values `23 ... 27`, and all of these codes will be returned.
!!! warning
Note: The larger the error margin used, the more time and freedom an attacker has to act, decreasing the security of the algorithm.
# Passwords
Vapor includes a password hashing API to help you store and verify passwords securely. This API is configurable based on environment and supports asynchronous hashing.
## Configuration
To configure the Application's password hasher, use `app.passwords`.
```swift
import Vapor
app.passwords.use(...)
```
### Bcrypt
To use Vapor's [Bcrypt API](crypto.md#bcrypt) for password hashing, specify `.bcrypt`. This is the default.
```swift
app.passwords.use(.bcrypt)
```
Bcrypt will use a cost of 12 unless otherwise specified. You can configure this by passing the `cost` parameter.
```swift
app.passwords.use(.bcrypt(cost: 8))
```
### Plaintext
Vapor includes an insecure password hasher that stores and verifies passwords as plaintext. This should not be used in production but can be useful for testing.
```swift
switch app.environment {
case .testing:
app.passwords.use(.plaintext)
default: break
}
```
## Hashing
To hash passwords, use the `password` helper available on `Request`.
```swift
let digest = try req.password.hash("vapor")
```
Password digests can be verified against the plaintext password using the `verify` method.
```swift
let bool = try req.password.verify("vapor", created: digest)
```
The same API is available on `Application` for use during boot.
```swift
let digest = try app.password.hash("vapor")
```
### Async
Password hashing algorithms are designed to be slow and CPU intensive. Because of this, you may want to avoid blocking the event loop while hashing passwords. Vapor provides an asynchronous password hashing API that dispatches hashing to a background thread pool. To use the asynchronous API, use the `async` property on a password hasher.
```swift
req.password.async.hash("vapor").map { digest in
// Handle digest.
}
// or
let digest = try await req.password.async.hash("vapor")
```
Verifying digests works similarly:
```swift
req.password.async.verify("vapor", created: digest).map { bool in
// Handle result.
}
// or
let result = try await req.password.async.verify("vapor", created: digest)
```
Calculating hashes on background threads can free your application's event loops up to handle more incoming requests.
# JWT
JSON Web Token (JWT) is an open standard ([RFC 7519](https://tools.ietf.org/html/rfc7519)) that defines a compact and self-contained way for securely transmitting information between parties as a JSON object. This information can be verified and trusted because it is digitally signed.
JWTs are particularly useful in web applications, where they are commonly used for stateless authentication/authorization and information exchange. You can read more about the theory behind JWTs in the spec linked above or on [jwt.io](https://jwt.io/introduction).
Vapor provides first-class support for JWTs through the `JWT` module. This module is built on top of the `JWTKit` library, which is a Swift implementation of the JWT standard based on [SwiftCrypto](https://github.com/apple/swift-crypto). JWTKit provides signers and verifiers for a variety of algorithms, including HMAC, ECDSA, EdDSA, and RSA.
## Getting Started
The first step to using JWTs in your Vapor application is to add the `JWT` dependency to your project's `Package.swift` file:
```swift
// swift-tools-version:5.10
import PackageDescription
let package = Package(
name: "my-app",
dependencies: [
// Other dependencies...
.package(url: "https://github.com/vapor/jwt.git", from: "5.0.0"),
],
targets: [
.target(name: "App", dependencies: [
// Other dependencies...
.product(name: "JWT", package: "jwt")
]),
// Other targets...
]
)
```
### Configuration
After adding the dependency, you can start using the `JWT` module in your application. The JWT module adds a new `jwt` property to `Application` that is used for configuration, of which the internals are provided by the [JWTKit](https://github.com/vapor/jwt-kit) library.
#### Key Collection
The `jwt` object comes with a `keys` property, which is an instance of JWTKit's `JWTKeyCollection`. This collection is used to store and manage the keys used to sign and verify JWTs. The `JWTKeyCollection` is an `actor`, which means that all operations on the collection are serialized and thread-safe.
To sign or verify JWTs, you will need to add a key to the collection. This is usually done in your `configure.swift` file:
```swift
import JWT
// Add HMAC with SHA-256 signer.
await app.jwt.keys.add(hmac: "secret", digestAlgorithm: .sha256)
```
This adds an HMAC key with SHA-256 as the digest algorithm to the keychain, or HS256 in JWA notation. Check out the [algorithms](#algorithms) section below for more information on the available algorithms.
!!! note
Be sure to replace `"secret"` with an actual secret key. This key should be kept secure, ideally in a configuration file or environment variable.
### Signing
The added key can then be used to sign JWTs. To do this, you first of all need _something_ to sign, namely a 'payload'.
This payload is simply a JSON object containing the data you want to transmit. You can create your custom payload by conforming your structure to the `JWTPayload` protocol:
```swift
// JWT payload structure.
struct TestPayload: JWTPayload {
// Maps the longer Swift property names to the
// shortened keys used in the JWT payload.
enum CodingKeys: String, CodingKey {
case subject = "sub"
case expiration = "exp"
case isAdmin = "admin"
}
// The "sub" (subject) claim identifies the principal that is the
// subject of the JWT.
var subject: SubjectClaim
// The "exp" (expiration time) claim identifies the expiration time on
// or after which the JWT MUST NOT be accepted for processing.
var expiration: ExpirationClaim
// Custom data.
// If true, the user is an admin.
var isAdmin: Bool
// Run any additional verification logic beyond
// signature verification here.
// Since we have an ExpirationClaim, we will
// call its verify method.
func verify(using algorithm: some JWTAlgorithm) async throws {
try self.expiration.verifyNotExpired()
}
}
```
Signing the payload is done by calling the `sign` method on the `JWT` module, for example inside of a route handler:
```swift
app.post("login") { req async throws -> [String: String] in
let payload = TestPayload(
subject: "vapor",
expiration: .init(value: .distantFuture),
isAdmin: true
)
return try await ["token": req.jwt.sign(payload)]
}
```
When a request is made to this endpoint, it will return the signed JWT as a `String` in the response body, and if everything went according to plan, you'll see something like this:
```json
{
"token": "eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9.eyJzdWIiOiJ2YXBvciIsImV4cCI6NjQwOTIyMTEyMDAsImFkbWluIjp0cnVlfQ.lS5lpwfRNSZDvpGQk6x5JI1g40gkYCOWqbc3J_ghowo"
}
```
You can decode and verify this token using the [`jwt.io` debugger](https://jwt.io/#debugger). The debugger will show you the payload (which should be the data you specified earlier) and header of the JWT, and you can verify the signature using the secret key you used to sign the JWT.
### Verifying
When a token is instead sent _to_ your application, you can verify the authenticity of the token by calling the `verify` method on the `JWT` module:
```swift
// Fetch and verify JWT from incoming request.
app.get("me") { req async throws -> HTTPStatus in
let payload = try await req.jwt.verify(as: TestPayload.self)
print(payload)
return .ok
}
```
The `req.jwt.verify` helper will check the `Authorization` header for a bearer token. If one exists, it will parse the JWT and verify its signature and claims. If any of these steps fail, a 401 Unauthorized error will be thrown.
Test the route by sending the following HTTP request:
```http
GET /me HTTP/1.1
authorization: Bearer eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9.eyJzdWIiOiJ2YXBvciIsImV4cCI6NjQwOTIyMTEyMDAsImFkbWluIjp0cnVlfQ.lS5lpwfRNSZDvpGQk6x5JI1g40gkYCOWqbc3J_ghowo
```
If everything worked, a `200 OK` response will be returned and the payload printed:
```swift
TestPayload(
subject: "vapor",
expiration: 4001-01-01 00:00:00 +0000,
isAdmin: true
)
```
The whole authentication flow can be found at [Authentication → JWT](authentication.md#jwt).
## Algorithms
JWTs can be signed using a variety of algorithms.
To add a key to the keychain, an overload of the `add` method is available for each of the following algorithms:
### HMAC
HMAC (Hash-based Message Authentication Code) is a symmetric algorithm that uses a secret key to sign and verify the JWT. Vapor supports the following HMAC algorithms:
- `HS256`: HMAC with SHA-256
- `HS384`: HMAC with SHA-384
- `HS512`: HMAC with SHA-512
```swift
// Add an HS256 key.
await app.jwt.keys.add(hmac: "secret", digestAlgorithm: .sha256)
```
### ECDSA
ECDSA (Elliptic Curve Digital Signature Algorithm) is an asymmetric algorithm that uses a public/private key pair to sign and verify the JWT. It's reliance is based on the math around elliptic curves. Vapor supports the following ECDSA algorithms:
- `ES256`: ECDSA with a P-256 curve and SHA-256
- `ES384`: ECDSA with a P-384 curve and SHA-384
- `ES512`: ECDSA with a P-521 curve and SHA-512
All algorithms provide both a public key and a private key, such as `ES256PublicKey` and `ES256PrivateKey`. You can add ECDSA keys using the PEM format:
```swift
let ecdsaPublicKey = """
-----BEGIN PUBLIC KEY-----
MFkwEwYHKoZIzj0CAQYIKoZIzj0DAQcDQgAE2adMrdG7aUfZH57aeKFFM01dPnkx
C18ScRb4Z6poMBgJtYlVtd9ly63URv57ZW0Ncs1LiZB7WATb3svu+1c7HQ==
-----END PUBLIC KEY-----
"""
// Initialize an ECDSA key with public PEM.
let key = try ES256PublicKey(pem: ecdsaPublicKey)
```
or generate random ones (useful for testing):
```swift
let key = ES256PrivateKey()
```
To add the key to the keychain:
```swift
await app.jwt.keys.add(ecdsa: key)
```
### EdDSA
EdDSA (Edwards-curve Digital Signature Algorithm) is an asymmetric algorithm that uses a public/private key pair to sign and verify the JWT. It's similar to ECDSA in that both rely on the DSA algorithm, but EdDSA is based on the Edwards-curve, a different family of elliptic curves, and has slight performance improvements. It's however also newer and therefore less widely supported. Vapor only supports the `EdDSA` algorithm which uses the `Ed25519` curve.
You can create an EdDSA key using its (base-64 encoded `String`) coordinate, so `x` if it's a public key and `d` if it's a private key:
```swift
let publicKey = try EdDSA.PublicKey(x: "0ZcEvMCSYqSwR8XIkxOoaYjRQSAO8frTMSCpNbUl4lE", curve: .ed25519)
let privateKey = try EdDSA.PrivateKey(d: "d1H3/dcg0V3XyAuZW2TE5Z3rhY20M+4YAfYu/HUQd8w=", curve: .ed25519)
```
You can also generate random ones:
```swift
let key = EdDSA.PrivateKey(curve: .ed25519)
```
To add the key to the keychain:
```swift
await app.jwt.keys.add(eddsa: key)
```
### RSA
RSA (Rivest-Shamir-Adleman) is an asymmetric algorithm that uses a public/private key pair to sign and verify the JWT.
!!! warning
As you'll see, RSA keys are gated behind an `Insecure` namespace to discourage new users from using them. This is because RSA is considered less secure than ECDSA and EdDSA, and should only be used for compatibility reasons.
If possible, use any of the other algorithms instead.
Vapor supports the following RSA algorithms:
- `RS256`: RSA with SHA-256
- `RS384`: RSA with SHA-384
- `RS512`: RSA with SHA-512
You can create an RSA key using its PEM format:
```swift
let rsaPublicKey = """
-----BEGIN PUBLIC KEY-----
MIGfMA0GCSqGSIb3DQEBAQUAA4GNADCBiQKBgQC0cOtPjzABybjzm3fCg1aCYwnx
PmjXpbCkecAWLj/CcDWEcuTZkYDiSG0zgglbbbhcV0vJQDWSv60tnlA3cjSYutAv
7FPo5Cq8FkvrdDzeacwRSxYuIq1LtYnd6I30qNaNthntjvbqyMmBulJ1mzLI+Xg/
aX4rbSL49Z3dAQn8vQIDAQAB
-----END PUBLIC KEY-----
"""
// Initialize an RSA key with public pem.
let key = try Insecure.RSA.PublicKey(pem: rsaPublicKey)
```
or usign its components:
```swift
// Initialize an RSA private key with components.
let key = try Insecure.RSA.PrivateKey(
modulus: modulus,
exponent: publicExponent,
privateExponent: privateExponent
)
```
!!! warning
The package does not support RSA keys smaller than 2048 bits.
Then you can add the key to the key collection:
```swift
await app.jwt.keys.add(rsa: key, digestAlgorithm: .sha256)
```
### PSS
In addition to the RSA-PKCS1v1.5 algorithm, Vapor also supports the RSA-PSS algorithm. PSS (Probabilistic Signature Scheme) is a more secure padding scheme for RSA signatures. It is recommended to use PSS over PKCS1v1.5 when possible.
The algorithm only differs in the signature phase, which means that the keys are the same as RSA, however, you need to specify the padding scheme when adding them to the key collection:
```swift
await app.jwt.keys.add(pss: key, digestAlgorithm: .sha256)
```
## Key Identifier (kid)
When adding a key to the key collection, you can also specify a key identifier (kid). This is a unique identifier for the key that can be used to look up the key in the collection.
```swift
// Add HMAC with SHA-256 key named "a".
await app.jwt.keys.add(hmac: "foo", digestAlgorithm: .sha256, kid: "a")
```
If you don't specify a `kid`, the key will be assigned as the default key.
!!! note
The default key will be overridden if you add another key without a `kid`.
When signing a JWT, you can specify the `kid` to use:
```swift
let token = try await req.jwt.sign(payload, kid: "a")
```
When verifying on the other hand, the `kid` is automatically extracted from the JWT header and used to look up the key in the collection. There's also a `iteratingKeys` parameter on the verify method that allows you to specify whether to iterate over all keys in the collection if the `kid` is not found.
## Claims
Vapor's JWT package includes several helpers for implementing common [JWT claims](https://tools.ietf.org/html/rfc7519#section-4.1).
|Claim|Type|Verify Method|
|---|---|---|
|`aud`|`AudienceClaim`|`verifyIntendedAudience(includes:)`|
|`exp`|`ExpirationClaim`|`verifyNotExpired(currentDate:)`|
|`jti`|`IDClaim`|n/a|
|`iat`|`IssuedAtClaim`|n/a|
|`iss`|`IssuerClaim`|n/a|
|`locale`|`LocaleClaim`|n/a|
|`nbf`|`NotBeforeClaim`|`verifyNotBefore(currentDate:)`|
|`sub`|`SubjectClaim`|n/a|
All claims should be verified in the `JWTPayload.verify` method. If the claim has a special verify method, you can use that. Otherwise, access the value of the claim using `value` and check that it is valid.
## JWK
A JSON Web Key (JWK) is a JSON data structure that represents a cryptographic key ([RFC7517](https://datatracker.ietf.org/doc/html/rfc7517)). These are commonly used to supply clients with keys for verifying JWTs.
For example, Apple hosts their Sign in with Apple JWKS at the following URL.
```http
GET https://appleid.apple.com/auth/keys
```
Vapor provides utilities to add JWKs to the key collection:
```swift
let privateKey = """
{
"kty": "RSA",
"d": "\(rsaPrivateExponent)",
"e": "AQAB",
"use": "sig",
"kid": "1234",
"alg": "RS256",
"n": "\(rsaModulus)"
}
"""
let jwk = try JWK(json: privateKey)
try await app.jwt.keys.use(jwk: jwk)
```
This will add the JWK to the key collection, and you can use it to sign and verify JWTs as you would with any other key.
### JWKs
If you have multiple JWKs, you can add them just as well:
```swift
let json = """
{
"keys": [
{"kty": "RSA", "alg": "RS256", "kid": "a", "n": "\(rsaModulus)", "e": "AQAB"},
{"kty": "RSA", "alg": "RS512", "kid": "b", "n": "\(rsaModulus)", "e": "AQAB"},
]
}
"""
try await app.jwt.keys.use(jwksJSON: json)
```
## Vendors
Vapor provides APIs for handling JWTs from the popular issuers below.
### Apple
First, configure your Apple application identifier.
```swift
// Configure Apple app identifier.
app.jwt.apple.applicationIdentifier = "..."
```
Then, use the `req.jwt.apple` helper to fetch and verify an Apple JWT.
```swift
// Fetch and verify Apple JWT from Authorization header.
app.get("apple") { req async throws -> HTTPStatus in
let token = try await req.jwt.apple.verify()
print(token) // AppleIdentityToken
return .ok
}
```
### Google
First, configure your Google application identifier and G Suite domain name.
```swift
// Configure Google app identifier and domain name.
app.jwt.google.applicationIdentifier = "..."
app.jwt.google.gSuiteDomainName = "..."
```
Then, use the `req.jwt.google` helper to fetch and verify a Google JWT.
```swift
// Fetch and verify Google JWT from Authorization header.
app.get("google") { req async throws -> HTTPStatus in
let token = try await req.jwt.google.verify()
print(token) // GoogleIdentityToken
return .ok
}
```
### Microsoft
First, configure your Microsoft application identifier.
```swift
// Configure Microsoft app identifier.
app.jwt.microsoft.applicationIdentifier = "..."
```
Then, use the `req.jwt.microsoft` helper to fetch and verify a Microsoft JWT.
```swift
// Fetch and verify Microsoft JWT from Authorization header.
app.get("microsoft") { req async throws -> HTTPStatus in
let token = try await req.jwt.microsoft.verify()
print(token) // MicrosoftIdentityToken
return .ok
}
```
# Deploying to DigitalOcean
This guide will walk you through deploying a simple Hello, world Vapor application to a [Droplet](https://www.digitalocean.com/products/droplets/). To follow this guide, you must have a [DigitalOcean](https://www.digitalocean.com) account with billing configured.
## Create Server
Let's start by installing Swift on a Linux server. Use the create menu to create a new Droplet.
Under distributions, select Ubuntu 22.04 LTS. The following guide will use this version as an example.
!!! note
You may select any Linux distribution with a version that Swift supports. You can check which operating systems are officially supported on the [Swift Releases](https://swift.org/download/#releases) page.
After selecting the distribution, choose any plan and datacenter region you prefer. Then setup an SSH key to access the server after it is created. Finally, click create Droplet and wait for the new server to spin up.
Once the new server is ready, hover over the Droplet's IP address and click copy.

## Initial Setup
Open your terminal and connect to the server as root using SSH.
```sh
ssh root@your_server_ip
```
DigitalOcean has an in-depth guide for [initial server setup on Ubuntu 22.04](https://www.digitalocean.com/community/tutorials/initial-server-setup-with-ubuntu-22-04). This guide will quickly cover the basics.
### Configure Firewall
Allow OpenSSH through the firewall and enable it.
```sh
ufw allow OpenSSH
ufw enable
```
### Add User
Create a new user besides `root`. This guide calls the new user `vapor`.
```sh
adduser vapor
```
Allow the newly created user to use `sudo`.
```sh
usermod -aG sudo vapor
```
Copy the root user's authorized SSH keys to the newly created user. This will allow you to SSH in as the new user.
```sh
rsync --archive --chown=vapor:vapor ~/.ssh /home/vapor
```
Finally, exit the current SSH session and login as the newly created user.
```sh
exit
ssh vapor@your_server_ip
```
## Install Swift
Now that you've created a new Ubuntu server and logged in as a non-root user you can install Swift.
### Automated installation using Swiftly CLI tool (recommended)
Visit the [Swiftly website](https://swiftlang.github.io/swiftly/) for instructions on how to install Swiftly and Swift on Linux. After that, install Swift with the following command:
#### Basic usage
```sh
$ swiftly install latest
Fetching the latest stable Swift release...
Installing Swift 5.9.1
Downloaded 488.5 MiB of 488.5 MiB
Extracting toolchain...
Swift 5.9.1 installed successfully!
$ swift --version
Swift version 5.9.1 (swift-5.9.1-RELEASE)
Target: x86_64-unknown-linux-gnu
```
## Install Vapor Using the Vapor Toolbox
Now that Swift is installed, let's install Vapor using the Vapor Toolbox. You will need to build the toolbox from source. View the toolbox's [releases](https://github.com/vapor/toolbox/releases) on GitHub to find the latest version. In this example, we are using 18.6.0.
### Clone and Build Vapor
Clone the Vapor Toolbox repository.
```sh
git clone https://github.com/vapor/toolbox.git
```
Checkout the latest release.
```sh
cd toolbox
git checkout 18.6.0
```
Build Vapor and move the binary into your path.
```sh
swift build -c release --disable-sandbox --enable-test-discovery
sudo mv .build/release/vapor /usr/local/bin
```
### Create a Vapor Project
Use the Toolbox's new project command to initiate a project.
```sh
vapor new HelloWorld -n
```
!!! tip
The `-n` flag gives you a bare bones template by automatically answering no to all questions.
Once the command finishes, change into the newly created folder:
```sh
cd HelloWorld
```
### Open HTTP Port
In order to access Vapor on your server, open an HTTP port.
```sh
sudo ufw allow 8080
```
### Run
Now that Vapor is setup and we have an open port, let's run it.
```sh
swift run App serve --hostname 0.0.0.0 --port 8080
```
Visit your server's IP via browser or local terminal and you should see "It works!". The IP address is `134.122.126.139` in this example.
```
$ curl http://134.122.126.139:8080
It works!
```
Back on your server, you should see logs for the test request.
```
[ NOTICE ] Server starting on http://0.0.0.0:8080
[ INFO ] GET /
```
Use `CTRL+C` to quit the server. It may take a second to shutdown.
Congratulations on getting your Vapor app running on a DigitalOcean Droplet!
## Next Steps
The rest of this guide points to additional resources to improve your deployment.
### Supervisor
Supervisor is a process control system that can run and monitor your Vapor executable. With supervisor setup, your app can automatically start when the server boots and be restarted in case it crashes. Learn more about [Supervisor](../deploy/supervisor.md).
### Nginx
Nginx is an extremely fast, battle tested, and easy-to-configure HTTP server and proxy. While Vapor supports directly serving HTTP requests, proxying behind Nginx can provide increased performance, security, and ease-of-use. Learn more about [Nginx](../deploy/nginx.md).
# Fly
Fly is a hosting platform that enables running server applications and databases with a focus on edge computing. See [their website](https://fly.io/) for more information.
!!! note
Commands specified in this document are subject to [Fly's pricing](https://fly.io/docs/about/pricing/), make sure you understand it properly before continuing.
## Signing up
If you don't have an account, you will need to [create one](https://fly.io/app/sign-up).
## Installing flyctl
The main way you interact with Fly is by using the dedicated CLI tool, `flyctl`, which you'll need to install.
### macOS
```bash
brew install flyctl
```
### Linux
```bash
curl -L https://fly.io/install.sh | sh
```
### Other install options
For more options and details, see [the `flyctl` installation docs](https://fly.io/docs/flyctl/install/).
## Logging in
To log in from your terminal, run the following command:
```bash
fly auth login
```
## Configuring your Vapor project
Before deploying to Fly, you must make sure you have a Vapor project with an adequately configured Dockerfile, since it's required by Fly to build your app. In most cases, this should be very easy since the default Vapor templates already contain one.
### New Vapor project
To easiest way to create a new project is to start with a template. You can create one using GitHub templates or the Vapor toolbox. If you need a database, it is recommended to use Fluent with Postgres; Fly makes it easy to create a Postgres database to connect your apps to (see the [dedicated section](#configuring-postgres) below).
#### Using the Vapor toolbox
First, ensure you have installed the Vapor toolbox (see install the instructions for [macOS](../install/macos.md#install-toolbox) or [Linux](../install/linux.md#install-toolbox)).
Create your new app with the following command, replacing `app-name` with the app name you desire:
```bash
vapor new app-name
```
This command will display an interactive prompt that will let you configure your Vapor project, this is where you can select Fluent and Postgres if you need them.
#### Using GitHub templates
Choose the template that best suits your needs in the following list. You can either clone it locally using Git or create a GitHub project with the "Use this template" button.
- [Barebones template](https://github.com/vapor/template-bare)
- [Fluent/Postgres template](https://github.com/vapor/template-fluent-postgres)
- [Fluent/Postgres + Leaf template](https://github.com/vapor/template-fluent-postgres-leaf)
### Existing Vapor project
If you have an existing Vapor project, make sure you have a properly configured `Dockerfile` present at the root of your directory; the [Vapor docs about using Docker](../deploy/docker.md) and [Fly docs about deploying an app via a Dockerfile](https://fly.io/docs/languages-and-frameworks/dockerfile/) might come in handy.
## Launch your app on Fly
Once your Vapor project is ready, you can launch it on Fly.
First, make sure your current directory is set to the root directory of your Vapor application and run the following command:
```bash
fly launch
```
This will start an interactive prompt to configure your Fly application settings:
- **Name:** you can type one or keep it blank to get an automatically generated name.
- **Region:** the default is the one that's the closest to you. You can choose to use it or any other in the list. This is easy to change later.
- **Database:** you can ask Fly to create a database to use with your app. If you prefer, you can always do the same later with the `fly pg create` and `fly pg attach` commands (see the [Configuring Postgres section](#configuring-postgres) for more details).
The `fly launch` command automatically creates a `fly.toml` file. It contains settings such as private/public port mappings, health checks parameters, and many others. If you just created a new project from scratch using `vapor new`, the default `fly.toml` file needs no changes. If you have an existing project, chances are `fly.toml` might also be ok with no or minor changes only. You can find more information in [the `fly.toml` docs](https://fly.io/docs/reference/configuration/).
Note that if you request Fly to create a database, you will have to wait a bit for it to be created and pass health checks.
Before exiting, the `fly launch` command will ask you if you would like to deploy your app immediately. You can accept it or do it later using `fly deploy`.
!!! tip
When your current directory is in your app's root, the fly CLI tool automatically detects the presence of a `fly.toml` file which lets Fly know which app your commands are targetting. If you want to target a specific app no matter your current directory, you can append `-a name-of-your-app` to most Fly commands.
## Deploying
You run the `fly deploy` command whenever you need to deploy new changes to Fly.
Fly reads your directory's `Dockerfile` and `fly.toml` files to determine how to build and run your Vapor project.
Once your container is built, Fly starts an instance of it. It will run various health checks, ensuring your application is running fine and your server responds to requests. The `fly deploy` command exits with an error if health checks fail.
By default, Fly will roll back to the latest working version of your app if health checks fail for the new version you attempted to deploy.
When deploying a background worker (with Vapor Queues). Do not change the CMD or ENTRYPOINT in your Dockerfile; leave that as-is so the main web application starts normally. Instead, add a [processes] section in your fly.toml file like this:
```
[processes]
app = ""
worker = "queues"
```
This tells Fly.io to run the app process with the default Docker entrypoint (your web server), and the worker process to run your job queue using Vapor’s command-line interface (ie, swift run App queues).
## Configuring Postgres
### Creating a Postgres database on Fly
If you didn't create a database app when you first launched your app, you can do it later using:
```bash
fly pg create
```
This command creates a Fly app that will be able to host databases available to your other apps on Fly, see the [dedicated Fly docs](https://fly.io/docs/postgres/) for more details.
Once your database app is created, go to your Vapor app's root directory and run:
```bash
fly pg attach name-of-your-postgres-app
```
If you don't know the name of your Postgres app, you can find it with `fly pg list`.
The `fly pg attach` command creates a database and user destined to your app, and then exposes it to your app through the `DATABASE_URL` environment variable.
!!! note
The difference between `fly pg create` and `fly pg attach` is that the former allocates and configures a Fly app that will be able to host Postgres databases, while the latter creates an actual database and user destined to the app of your choice. Provided it suits your requirements, a single Postgres Fly app could host multiple databases used by various apps. When you ask Fly to create a database app in `fly launch`, it does the equivalent of calling both `fly pg create` and `fly pg attach`.
### Connecting your Vapor app to the database
Once your app is attached to your database, Fly sets the `DATABASE_URL` environment variable to the connection URL that contains your credentials (it should be treated as sensitive information).
With most common Vapor project setups, you configure your database in `configure.swift`. Here's how you might want to do this:
```swift
if let databaseURL = Environment.get("DATABASE_URL") {
try app.databases.use(.postgres(url: databaseURL), as: .psql)
} else {
// Handle missing DATABASE_URL here...
//
// Alternatively, you could also set a different config
// depending on wether app.environment is set to to
// `.development` or `.production`
}
```
At this point, your project should be ready to run migrations and use the database.
### Running migrations
With `fly.toml`'s `release_command`, you can ask Fly to run a certain command before running your main server process. Add this to `fly.toml`:
```toml
[deploy]
release_command = "migrate -y"
```
!!! note
The code snippet above assumes you are using the default Vapor Dockerfile which sets your app `ENTRYPOINT` to `./App`. Concretely, this means that when you set `release_command` to `migrate -y`, Fly will call `./App migrate -y`. If your `ENTRYPOINT` is set to a different value, you will need to adapt the value of `release_command`.
Fly will run your release command in a temporary instance that has access to your internal Fly network, secrets, and environment variables.
If your release command fails, the deployment won't continue.
### Other databases
While Fly makes it easy to create a Postgres database app, it is possible to host other types of databases as well (for instance, see ["Use a MySQL database"](https://fly.io/docs/app-guides/mysql-on-fly/) in the Fly Docs).
## Secrets and environment variables
### Secrets
Use secrets to set any sensitive values as environment variables.
```bash
fly secrets set MYSECRET=A_SUPER_SECRET_VALUE
```
!!! warning
Keep in mind that most shells keep an history of the commands you typed. Be cautious about this when setting secrets this way. Some shells can be configured to not remember commands that are prefixed by a whitespace. See also the [`fly secrets import` command](https://fly.io/docs/flyctl/secrets-import/).
For more information, see the [documentation of `fly secrets`](https://fly.io/docs/apps/secrets/).
### Environment variables
You can set other non-sensitive [environment variables in `fly.toml`](https://fly.io/docs/reference/configuration/#the-env-variables-section), for instance:
```toml
[env]
MAX_API_RETRY_COUNT = "3"
SMS_LOG_LEVEL = "error"
```
## SSH connection
You can connect to an app's instances using:
```bash
fly ssh console -s
```
## Checking the logs
You can check your app's live logs using:
```bash
fly logs
```
## Next steps
Now that your Vapor app is deployed, there is a lot more you can do such as scaling your apps vertically and horizontally across multiple regions, adding persistent volumes, setting up continuous deployment, or even creating distributed app clusters. The best place to learn how to do all of this and more is the [Fly docs](https://fly.io/docs/).
# What is Heroku
Heroku is a popular all in one hosting solution, you can find more at [heroku.com](https://www.heroku.com)
## Signing Up
You'll need a heroku account, if you don't have one, please sign up here: [https://signup.heroku.com/](https://signup.heroku.com/)
## Installing CLI
Make sure that you've installed the heroku cli tool.
### HomeBrew
```bash
brew tap heroku/brew && brew install heroku
```
### Other Install Options
See alternative install options here: [https://devcenter.heroku.com/articles/heroku-cli#download-and-install](https://devcenter.heroku.com/articles/heroku-cli#download-and-install).
### Logging in
Once you've installed the cli, login with the following:
```bash
heroku login
```
Verify that the correct email is logged in with:
```bash
heroku auth:whoami
```
### Create an application
Visit dashboard.heroku.com to access your account, and create a new application from the drop down in the upper right hand corner. Heroku will ask a few questions such as region and application name, just follow their prompts.
### Git
Heroku uses Git to deploy your app, so you’ll need to put your project into a Git repository, if it isn’t already.
#### Initialize Git
If you need to add Git to your project, enter the following command in Terminal:
```bash
git init
```
#### Main
You should decide for one branch and stick to that for deploying to Heroku, like the **main** or **master** branch. Make sure all changes are checked into this branch before pushing.
Check your current branch with:
```bash
git branch
```
The asterisk indicates current branch.
```bash
* main
commander
other-branches
```
!!! note
If you don’t see any output and you’ve just performed `git init`. You’ll need to commit your code first then you’ll see output from the `git branch` command.
If you’re _not_ currently on the right branch, switch there by entering (for **main**):
```bash
git checkout main
```
#### Commit changes
If this command produces output, then you have uncommitted changes.
```bash
git status --porcelain
```
Commit them with the following
```bash
git add .
git commit -m "a description of the changes I made"
```
#### Connect with Heroku
Connect your app with heroku (replace with your app's name).
```bash
$ heroku git:remote -a your-apps-name-here
```
### Set Buildpack
Set the buildpack to teach heroku how to deal with vapor.
```bash
heroku buildpacks:set vapor/vapor
```
### Swift version file
The buildpack we added looks for a **.swift-version** file to know which version of swift to use. (Replace 5.8.1 with whatever version your project requires.)
```bash
echo "5.8.1" > .swift-version
```
This creates **.swift-version** with `5.8.1` as its contents.
### Procfile
Heroku uses the **Procfile** to know how to run your app, in our case it needs to look like this:
```
web: App serve --env production --hostname 0.0.0.0 --port $PORT
```
We can create this with the following terminal command
```bash
echo "web: App serve --env production" \
"--hostname 0.0.0.0 --port \$PORT" > Procfile
```
### Commit changes
We just added these files, but they're not committed. If we push, heroku will not find them.
Commit them with the following.
```bash
git add .
git commit -m "adding heroku build files"
```
### Deploying to Heroku
You're ready to deploy, run this from the terminal. It may take a while to build, this is normal.
```bash
git push heroku main
```
### Scale Up
Once you've built successfully, you need to add at least one server. Prices start at $5/month for the Eco plan (see [pricing](https://www.heroku.com/pricing#containers)), make sure you have payment configured on Heroku. Then for a single web worker:
```bash
heroku ps:scale web=1
```
### Continued Deployment
Any time you want to update, just get the latest changes into main and push to heroku and it will redeploy.
## Postgres
### Add PostgreSQL database
Visit your application at dashboard.heroku.com and go to the **Add-ons** section.
From here enter `postgres` and you'll see an option for `Heroku Postgres`. Select it.
Choose the Essential 0 plan for $5/month (see [pricing](https://www.heroku.com/pricing#data-services)), and provision. Heroku will do the rest.
Once you finish, you’ll see the database appears under the **Resources** tab.
### Configure the database
We have to now tell our app how to access the database. In our app directory, let's run.
```bash
heroku config
```
This will make output somewhat like this
```none
=== today-i-learned-vapor Config Vars
DATABASE_URL: postgres://cybntsgadydqzm:2d9dc7f6d964f4750da1518ad71hag2ba729cd4527d4a18c70e024b11cfa8f4b@ec2-54-221-192-231.compute-1.amazonaws.com:5432/dfr89mvoo550b4
```
**DATABASE_URL** here will represent our postgres database. **NEVER** hard code the static url from this, heroku will rotate it and it will break your application. It is also bad practice. Instead, read the environment variable at runtime.
The Heroku Postgres addon [requires](https://devcenter.heroku.com/changelog-items/2035) all connections to be encrypted. The certificates used by the Postgres servers are internal to Heroku, therefore an **unverified** TLS connection must be set up.
The following snippet shows how to achieve both:
```swift
if let databaseURL = Environment.get("DATABASE_URL") {
var tlsConfig: TLSConfiguration = .makeClientConfiguration()
tlsConfig.certificateVerification = .none
let nioSSLContext = try NIOSSLContext(configuration: tlsConfig)
var postgresConfig = try SQLPostgresConfiguration(url: databaseURL)
postgresConfig.coreConfiguration.tls = .require(nioSSLContext)
app.databases.use(.postgres(configuration: postgresConfig), as: .psql)
} else {
// ...
}
```
Don't forget to commit these changes
```bash
git add .
git commit -m "configured heroku database"
```
### Migrations
You can run commmands on Heroku with the `run` command.
To migrate:
```bash
heroku run App -- migrate --env production
```
To revert your database:
```bash
heroku run App -- migrate --revert --all --yes --env production
```
# Supervisor
[Supervisor](http://supervisord.org) is a process control system that makes it easy to start, stop, and restart your Vapor app.
## Install
Supervisor can be installed through package managers on Linux.
### Ubuntu
```sh
sudo apt-get update
sudo apt-get install supervisor
```
### CentOS and Amazon Linux
```sh
sudo yum install supervisor
```
### Fedora
```sh
sudo dnf install supervisor
```
## Configure
Each Vapor app on your server should have its own configuration file. For an example `Hello` project, the configuration file would be located at `/etc/supervisor/conf.d/hello.conf`
```sh
[program:hello]
command=/home/vapor/hello/.build/release/App serve --env production
directory=/home/vapor/hello/
user=vapor
stdout_logfile=/var/log/supervisor/%(program_name)s-stdout.log
stderr_logfile=/var/log/supervisor/%(program_name)s-stderr.log
```
As specified in our configuration file the `Hello` project is located in the home folder for the user `vapor`. Make sure `directory` points to the root directory of your project where the `Package.swift` file is.
The `--env production` flag will disable verbose logging.
### Environment
You can export variables to your Vapor app with supervisor. For exporting multiple environment values, put them all on one line. Per [Supervisor documentation](http://supervisord.org/configuration.html#program-x-section-values):
> Values containing non-alphanumeric characters should be quoted (e.g. KEY="val:123",KEY2="val,456"). Otherwise, quoting the values is optional but recommended.
```sh
environment=PORT=8123,ANOTHERVALUE="/something/else"
```
Exported variables can be used in Vapor using `Environment.get`
```swift
let port = Environment.get("PORT")
```
## Start
You can now load and start your app.
```sh
supervisorctl reread
supervisorctl add hello
supervisorctl start hello
```
!!! note
The `add` command may have already started your app.
# Systemd
Systemd is the default system and service manager on most Linux distributions. It is usually installed by default so no installation is needed on supported Swift distributions.
## Configure
Each Vapor app on your server should have its own service file. For an example `Hello` project, the configuration file would be located at `/etc/systemd/system/hello.service`. This file should look like the following:
```sh
[Unit]
Description=Hello
Requires=network.target
After=network.target
[Service]
Type=simple
User=vapor
Group=vapor
Restart=always
RestartSec=3
WorkingDirectory=/home/vapor/hello
ExecStart=/home/vapor/hello/.build/release/App serve --env production
StandardOutput=syslog
StandardError=syslog
SyslogIdentifier=vapor-hello
[Install]
WantedBy=multi-user.target
```
As specified in our configuration file the `Hello` project is located in the home folder for the user `vapor`. Make sure `WorkingDirectory` points to the root directory of your project where the `Package.swift` file is.
The `--env production` flag will disable verbose logging.
### Environment
You can export variables in two ways via systemd. Either by creating an environment file with all the variables set in it:
```sh
EnvironmentFile=/path/to/environment/file1
EnvironmentFile=/path/to/environment/file2
```
Or you can add them directly to the service file under `[service]`:
```sh
Environment="PORT=8123"
Environment="ANOTHERVALUE=/something/else"
```
Exported variables can be used in Vapor using `Environment.get`
```swift
let port = Environment.get("PORT")
```
## Start
You can now load, enable, start, stop and restart your app by running the following as root.
```sh
systemctl daemon-reload
systemctl enable hello
systemctl start hello
systemctl stop hello
systemctl restart hello
```
# Deploying with Nginx
Nginx is an extremely fast, battle tested, and easy-to-configure HTTP server and proxy. While Vapor supports directly serving HTTP requests with or without TLS, proxying behind Nginx can provide increased performance, security, and ease-of-use.
!!! note
We recommend proxying Vapor HTTP servers behind Nginx.
## Overview
What does it mean to proxy an HTTP server? In short, a proxy acts as a middleman between the public internet and your HTTP server. Requests come to the proxy and then it sends them to Vapor.
An important feature of this middleman proxy is that it can alter or even redirect the requests. For instance, the proxy can require that the client use TLS (https), rate limit requests, or even serve public files without talking to your Vapor application.

### More Detail
The default port for receiving HTTP requests is port `80` (and `443` for HTTPS). When you bind a Vapor server to port `80`, it will directly receive and respond to the HTTP requests that come to your server. When adding a proxy like Nginx, you bind Vapor to an internal port, like port `8080`.
!!! note
Ports greater than 1024 do not require `sudo` to bind.
When Vapor is bound to a port besides `80` or `443`, it will not be accessible to the outside internet. You then bind Nginx to port `80` and configure it to route requests to your Vapor server bound at port `8080` (or whichever port you've chosen).
And that's it. If Nginx is properly configured, you will see your Vapor app responding to requests on port `80`. Nginx proxies the requests and responses invisibly.
## Install Nginx
The first step is installing Nginx. One of the great parts of Nginx is the tremendous amount of community resources and documentation surrounding it. Because of this, we will not go into great detail here about installing Nginx as there is almost definitely a tutorial for your specific platform, OS, and provider.
Tutorials:
- [How To Install Nginx on Ubuntu 20.04](https://www.digitalocean.com/community/tutorials/how-to-install-nginx-on-ubuntu-20-04)
- [How To Install Nginx on Ubuntu 18.04](https://www.digitalocean.com/community/tutorials/how-to-install-nginx-on-ubuntu-18-04)
- [How to Install Nginx on CentOS 8](https://www.digitalocean.com/community/tutorials/how-to-install-nginx-on-centos-8)
- [How To Install Nginx on Ubuntu 16.04](https://www.digitalocean.com/community/tutorials/how-to-install-nginx-on-ubuntu-16-04)
- [How to Deploy Nginx on Heroku](https://blog.codeship.com/how-to-deploy-nginx-on-heroku/)
### Package Managers
Nginx can be installed through package managers on Linux.
#### Ubuntu
```sh
sudo apt-get update
sudo apt-get install nginx
```
#### CentOS and Amazon Linux
```sh
sudo yum install nginx
```
#### Fedora
```sh
sudo dnf install nginx
```
### Validate Installation
Check whether Nginx was installed correctly by visiting your server's IP address in a browser
```
http://server_domain_name_or_IP
```
### Service
The service can be started or stopped.
```sh
sudo service nginx stop
sudo service nginx start
sudo service nginx restart
```
## Booting Vapor
Nginx can be started and stopped with the `sudo service nginx ...` commands. You will need something similar to start and stop your Vapor server.
There are many ways to do this, and they depend on which platform you are deploying to. Check out the [Supervisor](supervisor.md) instructions to add commands for starting and stopping your Vapor app.
## Configure Proxy
The configuration files for enabled sites can be found in `/etc/nginx/sites-enabled/`.
Create a new file or copy the example template from `/etc/nginx/sites-available/` to get started.
Here is an example configuration file for a Vapor project called `Hello` in the home directory.
```sh
server {
server_name hello.com;
listen 80;
root /home/vapor/Hello/Public/;
location @proxy {
proxy_pass http://127.0.0.1:8080;
proxy_pass_header Server;
proxy_set_header Host $host;
proxy_set_header X-Real-IP $remote_addr;
proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
proxy_connect_timeout 3s;
proxy_read_timeout 10s;
}
}
```
This configuration file assumes the `Hello` project binds to port `8080` when started in production mode.
### Serving Files
Nginx can also serve public files without asking your Vapor app. This can improve performance by freeing up the Vapor process for other tasks under heavy load.
```sh
server {
...
# Serve all public/static files via nginx and then fallback to Vapor for the rest
location / {
try_files $uri @proxy;
}
location @proxy {
...
}
}
```
### TLS
Adding TLS is relatively straightforward as long as the certificates have been properly generated. To generate TLS certificates for free, check out [Let's Encrypt](https://letsencrypt.org/getting-started/).
```sh
server {
...
listen 443 ssl;
ssl_certificate /etc/letsencrypt/live/hello.com/fullchain.pem;
ssl_certificate_key /etc/letsencrypt/live/hello.com/privkey.pem;
ssl_protocols TLSv1 TLSv1.1 TLSv1.2;
ssl_prefer_server_ciphers on;
ssl_dhparam /etc/ssl/certs/dhparam.pem;
ssl_ciphers 'ECDHE-RSA-AES128-GCM-SHA256:ECDHE-ECDSA-AES128-GCM-SHA256:ECDHE-RSA-AES256-GCM-SHA384:ECDHE-ECDSA-AES256-GCM-SHA384:DHE-RSA-AES128-GCM-SHA256:DHE-DSS-AES128-GCM-SHA256:kEDH+AESGCM:ECDHE-RSA-AES128-SHA256:ECDHE-ECDSA-AES128-SHA256:ECDHE-RSA-AES128-SHA:ECDHE-ECDSA-AES128-SHA:ECDHE-RSA-AES256-SHA384:ECDHE-ECDSA-AES256-SHA384:ECDHE-RSA-AES256-SHA:ECDHE-ECDSA-AES256-SHA:DHE-RSA-AES128-SHA256:DHE-RSA-AES128-SHA:DHE-DSS-AES128-SHA256:DHE-RSA-AES256-SHA256:DHE-DSS-AES256-SHA:DHE-RSA-AES256-SHA:AES128-GCM-SHA256:AES256-GCM-SHA384:AES128-SHA256:AES256-SHA256:AES128-SHA:AES256-SHA:AES:CAMELLIA:DES-CBC3-SHA:!aNULL:!eNULL:!EXPORT:!DES:!RC4:!MD5:!PSK:!aECDH:!EDH-DSS-DES-CBC3-SHA:!EDH-RSA-DES-CBC3-SHA:!KRB5-DES-CBC3-SHA';
ssl_session_timeout 1d;
ssl_session_cache shared:SSL:50m;
ssl_stapling on;
ssl_stapling_verify on;
add_header Strict-Transport-Security max-age=15768000;
...
location @proxy {
...
}
}
```
The configuration above are the relatively strict settings for TLS with Nginx. Some of the settings here are not required, but enhance security.
# Docker Deploys
Using Docker to deploy your Vapor app has several benefits:
1. Your dockerized app can be spun up reliably using the same commands on any platform with a Docker Daemon -- namely, Linux (CentOS, Debian, Fedora, Ubuntu), macOS, and Windows.
2. You can use docker-compose or Kubernetes manifests to orchestrate multiple services needed for a full deployment (e.g. Redis, Postgres, nginx, etc.).
3. It is easy to test your app's ability to scale horizontally, even locally on your development machine.
This guide will stop short of explaining how to get your dockerized app onto a server. The simplest deploy would involve installing Docker on your server and running the same commands you would run on your development machine to spin up your application.
More complicated and robust deployments are usually different depending on your hosting solution; many popular solutions like AWS have builtin support for Kubernetes and custom database solutions which make it difficult to write best practices in a way that applies to all deployments.
Nevertheless, using Docker to spin your entire server stack up locally for testing purposes is incredibly valuable for both big and small serverside apps. Additionally, the concepts described in this guide apply in broad strokes to all Docker deployments.
## Set Up
You will need to set your developer environment up to run Docker and gain a basic understanding of the resource files that configure Docker stacks.
### Install Docker
You will need to install Docker for your developer environment. You can find information for any platform in the [Supported Platforms](https://docs.docker.com/install/#supported-platforms) section of the Docker Engine Overview. If you are on Mac OS, you can jump straight to the [Docker for Mac](https://docs.docker.com/docker-for-mac/install/) install page.
### Generate Template
We suggest using the Vapor template as a starting place. If you already have an App, build the template as described below into a new folder as a point of reference while dockerizing your existing app -- you can copy key resources from the template to your app and tweak them slightly as a jumping off point.
1. Install or build the Vapor Toolbox ([macOS](../install/macos.md#install-toolbox), [Linux](../install/linux.md#install-toolbox)).
2. Create a new Vapor App with `vapor new my-dockerized-app` and walk through the prompts to enable or disable relevant features. Your answers to these prompts will affect how the Docker resource files are generated.
## Docker Resources
It is worthwhile, whether now or in the near future, to familiarize yourself with the [Docker Overview](https://docs.docker.com/engine/docker-overview/). The overview will explain some key terminology that this guide uses.
The template Vapor App has two key Docker-specific resources: A **Dockerfile** and a **docker-compose** file.
### Dockerfile
A Dockerfile tells Docker how to build an image of your dockerized app. That image contains both your app's executable and all dependencies needed to run it. The [full reference](https://docs.docker.com/engine/reference/builder/) is worth keeping open when you work on customizing your Dockerfile.
The Dockerfile generated for your Vapor app has two stages. The first stage builds your app and sets up a holding area containing the result. The second stage sets up the basics of a secure runtime environment, transfers everything in the holding area to where it will live in the final image, and sets a default entrypoint and command that will run your app in production mode on the default port (8080). This configuration can be overridden when the image is used.
### Docker Compose File
A Docker Compose file defines the way Docker should build out multiple services in relation to each other. The Docker Compose file in the Vapor App template provides the necessary functionality to deploy your app, but if you want to learn more you should consult the [full reference](https://docs.docker.com/compose/compose-file/) which has details on all of the available options.
!!! note
If you ultimately plan to use Kubernetes to orchestrate your app, the Docker Compose file is not directly relevant. However, Kubernetes manifest files are similar conceptually and there are even projects out there aimed at [porting Docker Compose files](https://kubernetes.io/docs/tasks/configure-pod-container/translate-compose-kubernetes/) to Kubernetes manifests.
The Docker Compose file in your new Vapor App will define services for running your app, running migrations or reverting them, and running a database as your app's persistence layer. The exact definitions will vary depending on which database you chose to use when you ran `vapor new`.
Note that your Docker Compose file has some shared environment variables near the top. (You may have a different set of default variables depending on whether or not you're using Fluent, and which Fluent driver is in use if you are.)
```docker
x-shared_environment: &shared_environment
LOG_LEVEL: ${LOG_LEVEL:-debug}
DATABASE_HOST: db
DATABASE_NAME: vapor_database
DATABASE_USERNAME: vapor_username
DATABASE_PASSWORD: vapor_password
```
You will see these pulled into multiple services below with the `<<: *shared_environment` YAML reference syntax.
The `DATABASE_HOST`, `DATABASE_NAME`, `DATABASE_USERNAME`, and `DATABASE_PASSWORD` variables are hard coded in this example whereas the `LOG_LEVEL` will take its value from the environment running the service or fall back to `'debug'` if that variable is unset.
!!! note
Hard-coding the username and password is acceptable for local development, but you should store these variables in a secrets file for production deployment. One way to handle this in production is to export the secrets file to the environment that is running your deploy and use lines like the following in your Docker Compose file:
```
DATABASE_USERNAME: ${DATABASE_USERNAME}
```
This passes the environment variable through to the containers as-defined by the host.
Other things to take note of:
- Service dependencies are defined by `depends_on` arrays.
- Service ports are exposed to the system running the services with `ports` arrays (formatted as `:`).
- The `DATABASE_HOST` is defined as `db`. This means your app will access the database at `http://db:5432`. That works because Docker is going to spin up a network in use by your services and the internal DNS on that network will route the name `db` to the service named `'db'`.
- The `CMD` directive in the Dockerfile is overridden in some services with the `command` array. Note that what is specified by `command` is run against the `ENTRYPOINT` in the Dockerfile.
- In Swarm Mode (more on this below) services will by default be given 1 instance, but the `migrate` and `revert` services are defined as having `deploy` `replicas: 0` so they do not start up by default when running a Swarm.
## Building
The Docker Compose file tells Docker how to build your app (by using the Dockerfile in the current directory) and what to name the resulting image (`my-dockerized-app:latest`). The latter is actually the combination of a name (`my-dockerized-app`) and a tag (`latest`) where tags are used to version Docker images.
To build a Docker image for your app, run
```shell
docker compose build
```
from the root directory of your app's project (the folder containing `docker-compose.yml`).
You'll see that your app and its dependencies must be built again even if you had previously built them on your development machine. They are being built in the Linux build environment Docker is using so the build artifacts from your development machine are not reusable.
When it is done, you will find your app's image when running
```shell
docker image ls
```
## Running
Your stack of services can be run directly from the Docker Compose file or you can use an orchestration layer like Swarm Mode or Kubernetes.
### Standalone
The simplest way to run your app is to start it as a standalone container. Docker will use the `depends_on` arrays to make sure any dependant services are also started.
First, execute:
```shell
docker compose up app
```
and notice that both the `app` and `db` services are started.
Your app is listening on port 8080 and, as defined by the Docker Compose file, it is made accessible on your development machine at **http://localhost:8080**.
This port mapping distinction is very important because you can run any number of services on the same ports if they are all running in their own containers and they each expose different ports to the host machine.
Visit `http://localhost:8080` and you will see `It works!` but visit `http://localhost:8080/todos` and you will get:
```
{"error":true,"reason":"Something went wrong."}
```
Take a peak at the logs output in the terminal where you ran `docker compose up app` and you will see:
```
[ ERROR ] relation "todos" does not exist
```
Of course! We need to run migrations on the database. Press `Ctrl+C` to bring your app down. We are going to start the app up again but this time with:
```shell
docker compose up --detach app
```
Now your app is going to start up "detached" (in the background). You can verify this by running:
```shell
docker container ls
```
where you will see both the database and your app running in containers. You can even check on the logs by running:
```shell
docker logs
```
To run migrations, execute:
```shell
docker compose run migrate
```
After migrations run, you can visit `http://localhost:8080/todos` again and you will get an empty list of todos instead of an error message.
#### Log Levels
Recall above that the `LOG_LEVEL` environment variable in the Docker Compose file will be inherited from the environment where the service is started if available.
You can bring your services up with
```shell
LOG_LEVEL=trace docker-compose up app
```
to get `trace` level logging (the most granular). You can use this environment variable to set the logging to [any available level](../basics/logging.md#level).
#### All Service Logs
If you explicitly specify your database service when you bring containers up then you will see logs for both your database and your app.
```shell
docker-compose up app db
```
#### Bringing Standalone Containers Down
Now that you've got containers running "detached" from your host shell, you need to tell them to shut down somehow. It's worth knowing that any running container can be asked to shut down with
```shell
docker container stop
```
but the easiest way to bring these particular containers down is
```shell
docker-compose down
```
#### Wiping The Database
The Docker Compose file defines a `db_data` volume to persist your database between runs. There are a couple of ways to reset your database.
You can remove the `db_data` volume at the same time as bringing your containers down with
```shell
docker-compose down --volumes
```
You can see any volumes currently persisting data with `docker volume ls`. Note that the volume name will generally have a prefix of `my-dockerized-app_` or `test_` depending on whether you were running in Swarm Mode or not.
You can remove these volumes one at a time with e.g.
```shell
docker volume rm my-dockerized-app_db_data
```
You can also clean up all volumes with
```shell
docker volume prune
```
Just be careful you don't accidentally prune a volume with data you wanted to keep around!
Docker will not let you remove volumes that are currently in use by running or stopped containers. You can get a list of running containers with `docker container ls` and you can see stopped containers as well with `docker container ls -a`.
### Swarm Mode
Swarm Mode is an easy interface to use when you've got a Docker Compose file handy and you want to test how your app scales horizontally. You can read all about Swarm Mode in the pages rooted at the [overview](https://docs.docker.com/engine/swarm/).
The first thing we need is a manager node for our Swarm. Run
```shell
docker swarm init
```
Next we will use our Docker Compose file to bring up a stack named `'test'` containing our services
```shell
docker stack deploy -c docker-compose.yml test
```
We can see how our services are doing with
```shell
docker service ls
```
You should expect to see `1/1` replicas for your `app` and `db` services and `0/0` replicas for your `migrate` and `revert` services.
We need to use a different command to run migrations in Swarm mode.
```shell
docker service scale --detach test_migrate=1
```
!!! note
We have just asked a short-lived service to scale to 1 replica. It will successfully scale up, run, and then exit. However, that will leave it with `0/1` replicas running. This is no big deal until we want to run migrations again, but we cannot tell it to "scale up to 1 replica" if that is already where it is at. A quirk of this setup is that the next time we want to run migrations within the same Swarm runtime, we need to first scale the service down to `0` and then back up to `1`.
The payoff for our trouble in the context of this short guide is that now we can scale our app to whatever we want in order to test how well it handles database contention, crashes, and more.
If you want to run 5 instances of your app concurrently, execute
```shell
docker service scale test_app=5
```
In addition to watching docker scale your app up, you can see that 5 replicas are indeed running by again checking `docker service ls`.
You can view (and follow) the logs for your app with
```shell
docker service logs -f test_app
```
#### Bringing Swarm Services Down
When you want to bring your services down in Swarm Mode, you do so by removing the stack you created earlier.
```shell
docker stack rm test
```
## Production Deploys
As noted at the top, this guide will not go into great detail about deploying your dockerized app to production because the topic is large and varies greatly depending on the hosting service (AWS, Azure, etc.), tooling (Terraform, Ansible, etc.), and orchestration (Docker Swarm, Kubernetes, etc.).
However, the techniques you learn to run your dockerized app locally on your development machine are largely transferable to production environments. A server instance set up to run the docker daemon will accept all the same commands.
Copy your project files to your server, SSH into the server, and run a `docker-compose` or `docker stack deploy` command to get things running remotely.
Alternatively, set your local `DOCKER_HOST` environment variable to point at your server and run the `docker` commands locally on your machine. It is important to note that with this approach, you do not need to copy any of your project files to the server _but_ you do need to host your docker image somewhere your server can pull it from.
# Contributing to Vapor
Vapor is a community-driven project and contributions from community members form a significant amount of development of Vapor. This guide will help you understand the contribution process and help you make your first commits in Vapor!
Any contribution you make is useful! Even small things like fixing typos make a big difference to people using Vapor.
## Code of Conduct
Vapor has adopted Swift's Code of Conduct which can be found at [https://www.swift.org/code-of-conduct/](https://www.swift.org/code-of-conduct/). All contributors are expected to follow the code of conduct.
## What to work on
Working out what to work on can be a big hurdle when it comes to getting started in open source! Usually the best things to work on are issues you find or features you want. However, Vapor has some handy things to help you contribute.
### Security Issues
If you discover a security issue and want to report it or help fix it please **do not** raise an issue or create a pull request. We have a separate process for security issues to ensure we don't expose vulnerability until a fix is available. Email security@vapor.codes or [see here](https://github.com/vapor/.github/blob/main/SECURITY.md) for more details.
### Small issues
If you find a small issue, bug or typo, then feel free to go ahead and create a pull request to fix it. If it resolves an open issue on any of the repos then you can link it in the pull request in the sidebar so the issue is automatically closed when the pull request is merged.

### New features
If you want to propose larger changes like new features or bug fixes that change significant amounts of code then please either open an issue first or post in the `#development` channel in Discord. This enables us to discuss the change with you as there might be some context we need to apply or we can give you pointers. We don't want you wasting time if a feature doesn't fit in with our plans!
### Vapor's Boards
If you just want to contribute but don't have an idea of what to work on, that's awesome! Vapor has a couple of boards that can help. Vapor has around 40 repositories that are actively developed and looking through them all to find something to work on is not practical so we use boards to aggregate these.
The first board is the [good first issue board](https://github.com/orgs/vapor/projects/14). Any issue in Vapor's GitHub org that's tagged with `good first issue` will be added to the board for you to find. These are issues that we think will be good for people relatively new to Vapor to work on as they don't require much experience of the code.
The second board is the [help wanted board](https://github.com/orgs/vapor/projects/13). This pulls in issues labelled `help wanted`. These are issues that could be good to fix but the core team currently has other priorities. These issues usually require a bit more knowledge if they aren't also marked with `good first issue`, but they could be fun projects to work on!
### Translations
The final area where contributions are extremely valuable is the documentation. The docs have translations for multiple languages but not every page is translated and there are lots more languages we'd like to support! If you're interested in contributing new languages or updates see the [docs README](https://github.com/vapor/docs#translating) or reach out in the `#documentation` channel on Discord.
## Contributing Process
If you've never worked on an open source project, the steps to actual contribute can be confusing but they're pretty simple.
First, fork Vapor or whichever repo you want to work in. You can do this in the GitHub UI and GitHub has [some excellent docs](https://docs.github.com/en/get-started/quickstart/fork-a-repo) on how to do this.
You can then make changes in your fork with the usual commit and push process. Once you're ready to submit your fix, you can create a PR onto Vapor's repo. Again, GitHub has [excellent docs](https://docs.github.com/en/pull-requests/collaborating-with-pull-requests/proposing-changes-to-your-work-with-pull-requests/creating-a-pull-request-from-a-fork) on how to do this.
## Submitting a Pull Request
When submitting a pull request there are number of things you should check:
* All the tests pass
* New tests added for any new behavior or bugs fixed
* New public APIs are documented. We use DocC for our API documentation.
Vapor uses automation to reduce the amount of work needed for many tasks. For pull requests, we use the [Vapor Bot](https://github.com/VaporBot) to generate releases when a pull request is merged. The pull request body and title are used to generate the release notes, so make sure that they make sense and cover what you'd expect to see in release notes. We have more details on [Vapor's contributing guidelines](https://github.com/vapor/vapor/blob/main/.github/contributing.md#release-title).
# Upgrading to 4.0
This guide shows you how to upgrade an existing Vapor 3.x project to 4.x. This guide attempts to cover all of Vapor's official packages as well as some commonly used providers. If you notice anything missing, [Vapor's team chat](https://discord.gg/vapor) is a great place to ask for help. Issues and pull requests are also appreciated.
## Dependencies
To use Vapor 4, you will need Xcode 11.4 and macOS 10.15 or greater.
The Install section of the docs goes over installing dependencies.
## Package.swift
The first step to upgrading to Vapor 4 is to update your package's dependencies. Below is an example of an upgraded Package.swift file. You can also check out the updated [template Package.swift](https://github.com/vapor/template/blob/main/Package.swift).
```diff
-// swift-tools-version:4.0
+// swift-tools-version:5.2
import PackageDescription
let package = Package(
name: "api",
+ platforms: [
+ .macOS(.v10_15),
+ ],
dependencies: [
- .package(url: "https://github.com/vapor/fluent-postgresql.git", from: "1.0.0"),
+ .package(url: "https://github.com/vapor/fluent.git", from: "4.0.0"),
+ .package(url: "https://github.com/vapor/fluent-postgres-driver.git", from: "2.0.0"),
- .package(url: "https://github.com/vapor/jwt.git", from: "3.0.0"),
+ .package(url: "https://github.com/vapor/jwt.git", from: "4.0.0"),
- .package(url: "https://github.com/vapor/vapor.git", from: "3.0.0"),
+ .package(url: "https://github.com/vapor/vapor.git", from: "4.3.0"),
],
targets: [
.target(name: "App", dependencies: [
- "FluentPostgreSQL",
+ .product(name: "Fluent", package: "fluent"),
+ .product(name: "FluentPostgresDriver", package: "fluent-postgres-driver"),
- "Vapor",
+ .product(name: "Vapor", package: "vapor"),
- "JWT",
+ .product(name: "JWT", package: "jwt"),
]),
- .target(name: "Run", dependencies: ["App"]),
- .testTarget(name: "AppTests", dependencies: ["App"])
+ .target(name: "Run", dependencies: [
+ .target(name: "App"),
+ ]),
+ .testTarget(name: "AppTests", dependencies: [
+ .target(name: "App"),
+ ])
]
)
```
All packages that have been upgraded for Vapor 4 will have their major version number incremented by one.
!!! warning
The `-rc` pre-release identifier is used since some packages of Vapor 4 has not been officially released yet.
### Old Packages
Some Vapor 3 packages have been deprecated, such as:
- `vapor/auth`: Now included in Vapor.
- `vapor/core`: Absorbed into several modules.
- `vapor/crypto`: Replaced by SwiftCrypto (Now included in Vapor).
- `vapor/multipart`: Now included in Vapor.
- `vapor/url-encoded-form`: Now included in Vapor.
- `vapor-community/vapor-ext`: Now included in Vapor.
- `vapor-community/pagination`: Now part of Fluent.
- `IBM-Swift/LoggerAPI`: Replaced by SwiftLog.
### Fluent Dependency
`vapor/fluent` must now be added as a separate dependency to your dependencies list and targets. All database-specific packages have been suffixed with `-driver` to make the requirement on `vapor/fluent` clear.
```diff
- .package(url: "https://github.com/vapor/fluent-postgresql.git", from: "1.0.0"),
+ .package(url: "https://github.com/vapor/fluent.git", from: "4.0.0"),
+ .package(url: "https://github.com/vapor/fluent-postgres-driver.git", from: "2.0.0"),
```
### Platforms
Vapor's package manifests now explicitly support macOS 10.15 and greater. This means your package will also need to specify platform support.
```diff
+ platforms: [
+ .macOS(.v10_15),
+ ],
```
Vapor may add additional supported platforms in the future. Your package may support any subset of these platforms as long as the version number is equal or greater to Vapor's minimum version requirements.
### Xcode
Vapor 4 utilizes Xcode 11's native SPM support. This means you will no longer need to generate `.xcodeproj` files. Opening your project's folder in Xcode will automatically recognize SPM and pull in dependencies.
You can open your project natively in Xcode using `vapor xcode` or `open Package.swift`.
Once you've updated Package.swift, you may need to close Xcode and clear the following folders from the root directory:
- `Package.resolved`
- `.build`
- `.swiftpm`
- `*.xcodeproj`
Once your updated packages have resolved successfully you should see compiler errors--probably quite a few. Don't worry! We'll show you how to fix them.
## Run
The first order of business is to update your Run module's `main.swift` file to the new format.
```swift
import App
import Vapor
var env = try Environment.detect()
try LoggingSystem.bootstrap(from: &env)
let app = Application(env)
defer { app.shutdown() }
try configure(app)
try app.run()
```
The `main.swift` file's contents replace the App module's `app.swift`, so you can delete that file.
## App
Let's take a look at how to update the basic App module structure.
### configure.swift
The `configure` method should be changed to accept an instance of `Application`.
```diff
- public func configure(_ config: inout Config, _ env: inout Environment, _ services: inout Services) throws
+ public func configure(_ app: Application) throws
```
Below is an example of an updated configure method.
```swift
import Fluent
import FluentSQLiteDriver
import Vapor
// Called before your application initializes.
public func configure(_ app: Application) throws {
// Serves files from `Public/` directory
// app.middleware.use(FileMiddleware(publicDirectory: app.directory.publicDirectory))
// Configure SQLite database
app.databases.use(.sqlite(.file("db.sqlite")), as: .sqlite)
// Configure migrations
app.migrations.add(CreateTodo())
try routes(app)
}
```
Syntax changes for configuring things like routing, middleware, fluent, and more are mentioned below.
### boot.swift
`boot`'s contents can be placed in the `configure` method since it now accepts the application instance.
### routes.swift
The `routes` method should be changed to accept an instance of `Application`.
```diff
- public func routes(_ router: Router, _ container: Container) throws
+ public func routes(_ app: Application) throws
```
More information on changes to routing syntax are mentioned below.
## Services
Vapor 4's services APIs have been simplified to make it easier for you to discover and use services. Services are now exposed as methods and properties on `Application` and `Request` which allows the compiler to help you use them.
To understand this better, let's take a look at a few examples.
```diff
// Change the server's default port to 8281
- services.register { container -> NIOServerConfig in
- return .default(port: 8281)
- }
+ app.http.server.configuration.port = 8281
```
Instead of registering a `NIOServerConfig` to services, server configuration is now exposed as simple properties on Application that can be overridden.
```diff
// Register cors middleware
let corsConfiguration = CORSMiddleware.Configuration(
allowedOrigin: .all,
allowedMethods: [.POST, .GET, .PATCH, .PUT, .DELETE, .OPTIONS]
)
let corsMiddleware = CORSMiddleware(configuration: corsConfiguration)
- var middlewares = MiddlewareConfig() // Create _empty_ middleware config
- middlewares.use(corsMiddleware)
- services.register(middlewares)
+ app.middleware.use(corsMiddleware)
```
Instead of creating and registering a `MiddlewareConfig` to services, middleware are now exposed as a property on Application that can be added to.
```diff
// Make a request in a route handler.
- try req.make(Client.self).get("https://vapor.codes")
+ req.client.get("https://vapor.codes")
```
Like Application, Request also exposes services as simple properties and methods. Request-specific services should always be used when inside a route closure.
This new service pattern replaces the `Container`, `Service`, and `Config` types from Vapor 3.
### Providers
Providers are no longer required to configure third party packages. Each package instead extends Application and Request with new properties and methods for configuration.
Take a look at how Leaf is configured in Vapor 4.
```diff
// Use Leaf for view rendering.
- try services.register(LeafProvider())
- config.prefer(LeafRenderer.self, for: ViewRenderer.self)
+ app.views.use(.leaf)
```
To configure Leaf, use the `app.leaf` property.
```diff
// Disable Leaf view caching.
- services.register { container -> LeafConfig in
- return LeafConfig(tags: ..., viewsDir: ..., shouldCache: false)
- }
+ app.leaf.cache.isEnabled = false
```
### Environment
The current environment (production, development, etc) can be accessed via `app.environment`.
### Custom Services
Custom services conforming to the `Service` protocol and registered to the container in Vapor 3 can be now be expressed as extensions to either Application or Request.
```diff
struct MyAPI {
let client: Client
func foo() { ... }
}
- extension MyAPI: Service { }
- services.register { container -> MyAPI in
- return try MyAPI(client: container.make())
- }
+ extension Request {
+ var myAPI: MyAPI {
+ .init(client: self.client)
+ }
+ }
```
This service can then be accessed using the extension instead of `make`.
```diff
- try req.make(MyAPI.self).foo()
+ req.myAPI.foo()
```
### Custom Providers
Most custom services can be implemented using extensions as shown in the previous section. However, some advanced providers may need to hook into the application lifecycle or use stored properties.
Application's new `Lifecycle` helper can be used to register lifecycle handlers.
```swift
struct PrintHello: LifecycleHandler {
func willBoot(_ app: Application) throws {
print("Hello!")
}
}
app.lifecycle.use(PrintHello())
```
To store values on Application, you case use the new `Storage` helper.
```swift
struct MyNumber: StorageKey {
typealias Value = Int
}
app.storage[MyNumber.self] = 5
print(app.storage[MyNumber.self]) // 5
```
Accessing `app.storage` can be wrapped in a settable computed property to create a concise API.
```swift
extension Application {
var myNumber: Int? {
get { self.storage[MyNumber.self] }
set { self.storage[MyNumber.self] = newValue }
}
}
app.myNumber = 42
print(app.myNumber) // 42
```
## NIO
Vapor 4 now exposes SwiftNIO's async APIs directly and does not attempt to overload methods like `map` and `flatMap` or alias types like `EventLoopFuture`. Vapor 3 provided overloads and aliases for backward compatibility with early beta versions that were released before SwiftNIO existed. These have been removed to reduce confusion with other SwiftNIO compatible packages and better follow SwiftNIO's best practice recommendations.
### Async naming changes
The most obvious change is that the `Future` typealias for `EventLoopFuture` has been removed. This can be fixed fairly easily with a find and replace.
Furthermore, NIO does not support the `to:` labels that Vapor 3 added. Given Swift 5.2's improved type inference, `to:` is less necessary now anyway.
```diff
- futureA.map(to: String.self) { ... }
+ futureA.map { ... }
```
Methods prefixed with `new`, like `newPromise` have been changed to `make` to better suit Swift style.
```diff
- let promise = eventLoop.newPromise(String.self)
+ let promise = eventLoop.makePromise(of: String.self)
```
`catchMap` is no longer available, but NIO's methods like `mapError` and `flatMapErrorThrowing` will work instead.
Vapor 3's global `flatMap` method for combining multiple futures is no longer available. This can be replaced by using NIO's `and` method to combine many futures together.
```diff
- flatMap(futureA, futureB) { a, b in
+ futureA.and(futureB).flatMap { (a, b) in
// Do something with a and b.
}
```
### ByteBuffer
Many methods and properties that previously used `Data` now use NIO's `ByteBuffer`. This type is a more powerful and performant byte storage type. You can read more about its API in [SwiftNIO's ByteBuffer docs](https://swiftpackageindex.com/apple/swift-nio/main/documentation/niocore/bytebuffer).
To convert a `ByteBuffer` back to `Data`, use:
```swift
Data(buffer.readableBytesView)
```
### Throwing map / flatMap
The most difficult change is that `map` and `flatMap` can no longer throw. `map` has a throwing version named (somewhat confusingly) `flatMapThrowing`. `flatMap` however has no throwing counterpart. This may require you to restructure some asynchronous code.
Maps that do _not_ throw should continue to work fine.
```swift
// Non-throwing map.
futureA.map { a in
return b
}
```
Maps that _do_ throw must be renamed to `flatMapThrowing`.
```diff
- futureA.map { a in
+ futureA.flatMapThrowing { a in
if ... {
throw SomeError()
} else {
return b
}
}
```
Flat-maps that do _not_ throw should continue to work fine.
```swift
// Non-throwing flatMap.
futureA.flatMap { a in
return futureB
}
```
Instead of throwing an error inside a flat-map, return a future error. If the error originates from another throwing method, the error can be caught in a do / catch and returned as a future.
```swift
// Returning a caught error as a future.
futureA.flatMap { a in
do {
try doSomething()
return futureB
} catch {
return eventLoop.makeFailedFuture(error)
}
}
```
Throwing method calls can also be refactored into a `flatMapThrowing` and chained using tuples.
```swift
// Refactored throwing method into flatMapThrowing with tuple-chaining.
futureA.flatMapThrowing { a in
try (a, doSomeThing())
}.flatMap { (a, result) in
// result is the value of doSomething.
return futureB
}
```
## Routing
Routes are now registered directly to Application.
```swift
app.get("hello") { req in
return "Hello, world"
}
```
This means you no longer need to register a router to services. Simply pass the application to your `routes` method and start adding routes. All of the methods available on `RoutesBuilder` are available on `Application`.
### Synchronous Content
Decoding request content is now synchronous.
```swift
let payload = try req.content.decode(MyPayload.self)
print(payload) // MyPayload
```
This behavior can be overridden by register routes using the `.stream` body collection strategy.
```swift
app.on(.POST, "streaming", body: .stream) { req in
// Request body is now asynchronous.
req.body.collect().map { buffer in
HTTPStatus.ok
}
}
```
### Comma-separated paths
Paths must now be comma separated and not contain `/` for consistency.
```diff
- router.get("v1/users/", "posts", "/comments") { req in
+ app.get("v1", "users", "posts", "comments") { req in
// Handle request.
}
```
### Route parameters
The `Parameter` protocol has been removed in favor of explicitly named parameters. This prevents issues with duplicate parameters and un-ordered fetching of parameters in middleware and route handlers.
```diff
- router.get("planets", String.parameter) { req in
- let id = req.parameters.next(String.self)
+ app.get("planets", ":id") { req in
+ let id = req.parameters.get("id")
return "Planet id: \(id)"
}
```
Route parameter usage with models is mentioned in the Fluent section.
## Middleware
`MiddlewareConfig` has been renamed to `MiddlewareConfiguration` and is now a property on Application. You can add middleware to your app using `app.middleware`.
```diff
let corsMiddleware = CORSMiddleware(configuration: ...)
- var middleware = MiddlewareConfig()
- middleware.use(corsMiddleware)
+ app.middleware.use(corsMiddleware)
- services.register(middlewares)
```
Middleware can no longer be registered by type name. Initialize the middleware first before registering.
```diff
- middleware.use(ErrorMiddleware.self)
+ app.middleware.use(ErrorMiddleware.default(environment: app.environment))
```
To remove all default middleware, set `app.middleware` to an empty config using:
```swift
app.middleware = .init()
```
## Fluent
Fluent's API is now database agnostic. You can import just `Fluent`.
```diff
- import FluentMySQL
+ import Fluent
```
### Models
All models now use the `Model` protocol and must be classes.
```diff
- struct Planet: MySQLModel {
+ final class Planet: Model {
```
All fields are declared using `@Field` or `@OptionalField` property wrappers.
```diff
+ @Field(key: "name")
var name: String
+ @OptionalField(key: "age")
var age: Int?
```
A model's ID must be defined using the `@ID` property wrapper.
```diff
+ @ID(key: .id)
var id: UUID?
```
Models using an identifier with a custom key or type must use `@ID(custom:)`.
All models must have their table or collection name defined statically.
```diff
final class Planet: Model {
+ static let schema = "Planet"
}
```
All models must now have an empty initializer. Since all properties use property wrappers, this can be empty.
```diff
final class Planet: Model {
+ init() { }
}
```
Model's `save`, `update`, and `create` no longer return the model instance.
```diff
- model.save(on: ...)
+ model.save(on: ...).map { model }
```
Models can no longer be used as route path components. Use `find` and `req.parameters.get` instead.
```diff
- try req.parameters.next(ServerSize.self)
+ ServerSize.find(req.parameters.get("size"), on: req.db)
+ .unwrap(or: Abort(.notFound))
```
`Model.ID` has been renamed to `Model.IDValue`.
Model timestamps are now declared using the `@Timestamp` property wrapper.
```diff
- static var createdAtKey: TimestampKey? = \.createdAt
+ @Timestamp(key: "createdAt", on: .create)
var createdAt: Date?
```
### Relations
Relations are now defined using property wrappers.
Parent relations use the `@Parent` property wrapper and contain the field property internally. The key passed to `@Parent` should be the name of the field storing the identifier in the database.
```diff
- var serverID: Int
- var server: Parent {
- parent(\.serverID)
- }
+ @Parent(key: "serverID")
+ var server: Server
```
Children relations use the `@Children` property wrapper with a key path to the related `@Parent`.
```diff
- var apps: Children {
- children(\.serverID)
- }
+ @Children(for: \.$server)
+ var apps: [App]
```
Siblings relations use the `@Siblings` property wrapper with key paths to the pivot model.
```diff
- var users: Siblings {
- siblings()
- }
+ @Siblings(through: Permission.self, from: \.$user, to: \.$company)
+ var companies: [Company]
```
Pivots are now normal models that conform to `Model` with two `@Parent` relations and zero or more additional fields.
### Query
The database context is now accessed via `req.db` in route handlers.
```diff
- Planet.query(on: req)
+ Planet.query(on: req.db)
```
`DatabaseConnectable` has been renamed to `Database`.
Key paths to fields are now prefixed with `$` to specify the property wrapper instead of the field value.
```diff
- filter(\.foo == ...)
+ filter(\.$foo == ...)
```
### Migrations
Models no longer support reflection-based auto migrations. All migrations must be written manually.
```diff
- extension Planet: Migration { }
+ struct CreatePlanet: Migration {
+ ...
+}
```
Migrations are now stringly typed and decoupled from models and use the `Migration` protocol.
```diff
- struct CreateGalaxy: <#Database#>Migration {
+ struct CreateGalaxy: Migration {
```
The `prepare` and `revert` methods are no longer static.
```diff
- static func prepare(on conn: <#Database#>Connection) -> Future {
+ func prepare(on database: Database) -> EventLoopFuture
```
Creating a schema builder is done via an instance method on `Database`.
```diff
- <#Database#>Database.create(Galaxy.self, on: conn) { builder in
- // Use builder.
- }
+ var builder = database.schema("Galaxy")
+ // Use builder.
```
The `create`, `update`, and `delete` methods are now called on the schema builder similar to how query builder works.
Fields definitions are now stringly typed and follow the pattern:
```swift
field(, , )
```
See the example below.
```diff
- builder.field(for: \.name)
+ builder.field("name", .string, .required)
```
Schema building can now be chained like query builder.
```swift
database.schema("Galaxy")
.id()
.field("name", .string, .required)
.create()
```
### Fluent Configuration
`DatabasesConfig` has been replaced by `app.databases`.
```swift
try app.databases.use(.postgres(url: "postgres://..."), as: .psql)
```
`MigrationsConfig` has been replaced by `app.migrations`.
```swift
app.migrations.use(CreatePlanet(), on: .psql)
```
### Repositories
As the way services work in Vapor 4 has changed, that also means that the way to do database repositories has changed. You still need a protocol such as `UserRepository` but instead of making a `final class` conform to that protocol, you should make a `struct` instead.
```diff
- final class DatabaseUserRepository: UserRepository {
+ struct DatabaseUserRepository: UserRepository {
let database: Database
func all() -> EventLoopFuture<[User]> {
return User.query(on: database).all()
}
}
```
You should also remove conformance from `ServiceType` as this no longer exists in Vapor 4.
```diff
- extension DatabaseUserRepository {
- static let serviceSupports: [Any.Type] = [Athlete.self]
- static func makeService(for worker: Container) throws -> Self {
- return .init()
- }
- }
```
Instead you should create a `UserRepositoryFactory`:
```swift
struct UserRepositoryFactory {
var make: ((Request) -> UserRepository)?
mutating func use(_ make: @escaping ((Request) -> UserRepository)) {
self.make = make
}
}
```
This factory is responsible for returning a `UserRepository` for a `Request`.
Next step is to add an extension to `Application` to specify your factory:
```swift
extension Application {
private struct UserRepositoryKey: StorageKey {
typealias Value = UserRepositoryFactory
}
var users: UserRepositoryFactory {
get {
self.storage[UserRepositoryKey.self] ?? .init()
}
set {
self.storage[UserRepositoryKey.self] = newValue
}
}
}
```
To use the actual repository inside of a `Request` add this extension to `Request`:
```swift
extension Request {
var users: UserRepository {
self.application.users.make!(self)
}
}
```
Last step is to specify the factory inside `configure.swift`
```swift
app.users.use { req in
DatabaseUserRepository(database: req.db)
}
```
You can now access your repository in your route handlers with: `req.users.all()` and easily replace the factory inside tests.
If you want to use a mocked repository inside tests, first create a `TestUserRepository`
```swift
final class TestUserRepository: UserRepository {
var users: [User]
let eventLoop: EventLoop
init(users: [User] = [], eventLoop: EventLoop) {
self.users = users
self.eventLoop = eventLoop
}
func all() -> EventLoopFuture<[User]> {
eventLoop.makeSuccededFuture(self.users)
}
}
```
You can now use this mocked repository inside your tests as follows:
```swift
final class MyTests: XCTestCase {
func test() throws {
let users: [User] = []
app.users.use { TestUserRepository(users: users, eventLoop: $0.eventLoop) }
...
}
}
```
# Vapor Release Notes
Because it is hard, if not impossible to keep the documentation up-to-date constantly, here you will find release notes of various different packages linked to the Vapor ecosystem.
## vapor
## fluent
## fluent-kit
## leaf
## leaf-kit
## fluent-postgres-driver
## fluent-mysql-driver
## fluent-sqlite-driver
## fluent-mongo-driver
## postgres-nio
## mysql-nio
## sqlite-nio
## postgres-kit
## mysql-kit
## sqlite-kit
## sql-kit
## apns
## queues
## queues-redis-driver
## redis
## jwt
## jwt-kit
## websocket-kit
## routing-kit
## console-kit
## async-kit
## multipart-kit
## toolbox
## core
## swift-codecov-action
## api-docs